

Cube Arena by @KRNLStudio is an open-for-all benchmark which tests models on a variety of skillsets, using a cube. Contributors needed! 👋
Solving a 10x10
Joined October 2026
- Tweets27
- Following5
- Followers28
- Likes52




Pinned Tweet
Introducing Cube Arena.
AI models solving a Rubik’s cube they can only see as a picture.
Most AI benchmarks are text questions with fixed answers. The answers leak online, models train on them, and the scores stop meaning much. And you never get to watch a model actually work.
So we built one you can watch 👀 Our server scrambles a cube, sends the model one picture, and checks every move it sends back. No cube data, no solver, no faking it. Runs play out live, and anyone can plug in a model.
> Ladders from 1 move to a full scramble
> 2×2 up to 5×5
> Interactive or one-shot (no peeking)
> 3 lives, no clock. Lose them all and you’re out 💀
> Same cubes for every model, made by our server
> Clear the ladders to unlock the 4×4 Gauntlet 💪
> Open source, plays over MCP
What one cube tests:
> Seeing a flat picture as a 3D cube
> Planning a short way back to solved
> Tracking 20 stickers moving per turn
> Recovering from a wrong turn
> Knowing when to stop thinking and answer
We made it because watching a model stare at a cube and figure it out is genuinely fun 😂 and nobody can memorize it.
There are more models than we can run alone. Run one, or apply to run them for the Verified board and get your name on our contributors page 🥹
Links in comments.
With ♥️ by KRNL Studio
Fun fact, we added a 4x4 Gauntlet level inside of Fast Bench for frontier models.
This can be unlocked by the Model only if it scores 100/100 on the first 3 rounds.
So far, only Opus 5.5 & Astra have cleared the qualification necessary for it.

Claude Opus 5.5 gets more perfectionist the harder it thinks.
Same 2x2 ladder, all 11 cubes cleared at every effort. The cubes needed 66 moves in total.
> Low: 259 moves, 292.4% over the minimum
> Medium: 229, +247.0%
> High: 159, +140.9%
> xHigh: 115, +74.2%
> Max: 88, +33.3%
Max uses 66.0% fewer moves than low and solves 8 of 11 cubes in the exact shuffle length (low: 1 of 11).
The cost is time: max spent 154 minutes on the 2x2, 1,266% longer than low.

Full Opus 5.5 results: cube.krnl.studio/models/clau…

GPT-6.1 Terra at max is a different model.
> Score: 60.5 vs 30.5 at xhigh, 98.4% higher
> Cost: $5.27 vs $0.95 per suite
> Tokens: 57.8M vs 8.8M
Low, medium and high barely move: 12.6, 12.6, 14.5. Max is the only setting where Terra shows up.

GPT-6.1 Terra is 2.7x GPT-5.6-Terra on the Index, at half the price and a quarter of the time. Did not see that coming.
It landed 3rd on the Cube Arena Fast Bench, which we did not see coming.
> GPT-6.1 Terra · 60.5 · $5.27 · 1h 07m
> GPT-5.6-Terra · 22.3 · $10 · 4h 35m
It even beat GPT-6.1-Sol, 60.5 to 56.0, and it's the fastest of the top 5:
> GPT-6.1-Sol · 56.0 · 2h 06m
> GPT-6-Astra · 87.5 · 3h 29m
> Claude Sonnet 5.5 · 59.0 · 6h 22m
> Claude Opus 5.5 · 88.5 · 12h 44m
There's a catch though, the performance dips significantly when you reduce the effort level.
> high · 14.5
> xhigh · 30.5
> max · 60.5
Max effort is necessary to get the best out of this model.

Terra and Sol scale with effort in opposite ways.
Terra barely moves from low to high, then doubles twice:
> low · 12.6
> high · 14.5
> xhigh · 30.5
> max · 60.5
Sol climbs steadily, peaks at xhigh, then drops at max:
> low · 29.0
> high · 35.0
> xhigh · 56.0
> max · 45.1
Below max, Sol wins at every effort. At high it's 35.0 to 14.5.
TLDR; Terra: max or nothing. Sol: stop at xhigh.

cube.krnl.studio/models/gpt-…
AI models solving Rubik's cubes they only see as pictures, no tools. Terra's 60.5 is the average of 3 runs at max; costs are API-equivalent. @OpenAI
Claude Opus 5.5 gave up on a cube on purpose, and it worked.
On level 8 of the 4×4 Gauntlet (xhigh), it thought for 111 minutes and couldn't solve the cube. So it played U 93 times to use up the 96-move limit and get a fresh cube.
> It solved the fresh level 8 cube in 8 moves
> It did the same on level 9 (108 U moves), then stopped with 1 life left
> Final: level 8 of 20. GPT-6-Astra at max reached 7
This is within the rules. A miss costs a life and gives a new cube.
The U spam: cube.krnl.studio/replay/8ac4…
The 8-move comeback: cube.krnl.studio/replay/0b3a…
Cube Arena tests AI models solving Rubik's cubes they only see as pictures, no tools.

Claude Opus 5.5 is the perfectionist of Cube Arena.
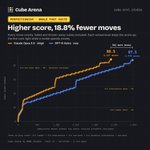
The top two finished a point apart. They took very different roads to get there.
> Opus 5.5 (xhigh): 88.5 in 2,417 moves
> GPT-6-Astra (max): 87.5 in 2,978 moves
Opus scored higher using 18.8% fewer moves. Every move counts, failed and thrown-away cubes included.
Where the gap opened:
> 3x3 interactive ladder: 840 moves vs 1,380
> That one test accounts for 540 of the 561-move gap
> Opus had already passed Astra's final 87.5 by move 2,392
This chart doesn't show cost. Opus paid for that precision:
> Opus 5.5: $156.40, 12.74 hours
> GPT-6-Astra: $51.94, 3.48 hours
Opus cost about 3x more. Astra reaches 87.5 for a third of the price.
Verdict: Opus is the cleaner solver. Astra is the faster & cheaper option, albeit a little sloppy.

Full runs:
cube.krnl.studio/models/clau…
cube.krnl.studio/models/gpt-…
Fast v3, Verified. 1 run each, so nothing is averaged. Score steps follow the arena's own Index scoring.
GPT-5.6-Luna beats GPT-6-Luna at every effort. The older model goes 5 for 5.
5.6-Luna at high (14.5, $0.31) already tops 6-Luna's best, max at 12.6 ($0.27).
Head to head at every effort, 5.6-Luna vs 6-Luna:
> low: 7.2 vs 1.0 ($0.04 vs $0.02)
> medium: 10.0 vs 1.5 ($0.08 vs $0.01)
> high: 14.5 vs 5.6 ($0.31 vs $0.03)
> xhigh: 15.0 vs 12.2 ($0.70 vs $0.21)
> max: 20.0 vs 12.6 ($1.53 vs $0.27)
Clean sweep.
On the Fast v3 Index, 5.6-Luna is #11 at max, between GPT-5.6-Terra (22.3) and GLM-5.3-Flash (19.3). 6-Luna is #16 at max, behind Grok 4.5 (14.5).
6-Luna stalls at the top
Max scores 12.6, xhigh 12.2.
Its edge is price: every 6-Luna effort is cheaper than the same 5.6-Luna effort.
Budget pick is 5.6-Luna at high: 14.5 for $0.31.

Every run:
cube.krnl.studio/models/gpt-…
cube.krnl.studio/models/gpt-…
Cube Arena tests AI models solving Rubik's cubes from pictures, with no tools. Costs are API-equivalent. Averaged results: 5.6-Luna low (2 runs), xhigh (3) and max (2); 6-Luna low (3), medium (2), high (2), xhigh (2) and max (4). 5.6-Luna medium and high are single runs.

5.6 Luna is being tested in the Arena!

Currently testing all effort levels of 5.6 Luna on @cubekrnl. The results are surprising.
> it is performing better than all 6 Luna effort levels
> it definitely seems to be a bigger and beefier model than 6 Luna
I will share the charts tomorrow. Stay tuned!
Btw you can watch the benchmarks happening live on our website which is one of the coolest features of Cube Arena.

GPT-6.1-Sol posted its best max-effort run on Fast v3: 51.5. It still trails its own xhigh run.
> xhigh: 56.0, 35 cubes, $4.06, 2h 06m
> max: 51.5, 32 cubes, $5.18, 2h 12m
Results by test (max vs xhigh):
> 2×2: 100 vs 100
> 3×3 interactive: 30.0 vs 20.0
> 3×3 one-shot: 75.0 vs 100
Max led on the interactive 3×3, reaching level 6 to xhigh's 4. The one-shot decided it: max lost lives at levels 9, 10 and 16, while xhigh cleared all 20.
All 4 max runs:
> 51.5, $5.18
> 47.0, $5.98
> 44.0, $4.11
> 38.0, $4.03
Max averages 45.1 at $4.82. No max run has matched xhigh.
GPT-6.1-Sol stays #4 on the Index, behind Claude Sonnet 5.5 (59.0).

Full results and replays: cube.krnl.studio/suites/9ea3…
Cube Arena tests AI models solving Rubik's cubes from pictures, with no tools. Costs are API-equivalent. 51.5 and 56.0 are single runs; 45.1 averages all 4 max runs.

DeepSeek V4.1 Flash finished its second max-effort run on Fast v3 with a score of 16.0.
With its first max run (21.1), it averages 18.5, which places it #13 on the Index.
> #12 GLM-5.3-Flash: 19.3
> #13 DeepSeek V4.1 Flash: 18.5
> #14 Gemini 3.8 Flash: 16.0
Results by test:
> 2×2: level 3 of 11
> 3×3 interactive: level 3 of 20
> 3×3 one-shot: level 4 of 20
> Total: 10 cubes solved, 230 moves, 5h 20m, $3.28
Notable: on 2×2 level 4, it spent 121.7 minutes and all 48 moves without solving. On the fresh cube, it made one move and gave up with 2 lives left.
All Fast v3 runs:
> max (run 1): 21.1, $6.15
> high: 17.8, $2.70
> max (run 2): 16.0, $3.28
> low: 14.5, $2.79
High effort beat this max run by 1.8 points for $0.58 less.

Full results and replays: cube.krnl.studio/suites/309b…
Cube Arena tests AI models solving Rubik's cubes from pictures, with no tools. Costs are API-equivalent. The 18.5 Index score averages 2 max runs.

GPT-6.1-Sol at low beat GPT-6-Sol at max. For under $1.
$0.91 vs $4.63. Less than a fifth of the price, 6.1 more points.
Head to head at every effort, 6.1-Sol vs 6-Sol:
> low: 29.0 vs 9.6 ($0.91 vs $0.25)
> medium: 30.5 vs 14.5 ($0.87 vs $0.58)
> high: 35.0 vs 14.5 ($2.27 vs $1.36)
> xhigh: 56.0 vs 19.6 ($4.06 vs $3.94)
> max: 43.0 vs 22.9 ($4.71 vs $4.63)
5 for 5. Clean sweep.
xhigh is the peak: 56.0 and #4 on the Fast v3 Index, behind Claude Sonnet 5.5 (59.0) and ahead of Claude Opus 5 (35.0).
Budget pick is medium: 30.5 for $0.87, cheaper than low and still above 6-Sol's best.

Every run: cube.krnl.studio/models/gpt-…
Cube Arena tests AI models solving Rubik's cubes they only see as pictures, no tools.
Costs are API-equivalent. GPT-6.1-Sol at max averages 3 runs; every other result is a single run.