



🚨 OpenAI's AI agents found 948 distinct Linux kernel vulnerabilities that could give an ordinary local user root access. The entire experiment cost just $1.21 million.
And here's the most alarming part: the average cost was only $1,279 per confirmed privilege-escalation vulnerability, including discovery, validation, exploitation, and proposed fixes.
OpenAI published the results in a new security research report titled "A Thousand Fewer Paths to Root."
🔍 What did the AI actually accomplish?
During a large-scale experiment in October 2026, an autonomous pipeline achieved:
▪️ 2,308 potential vulnerabilities identified.
▪️ 1,724 vulnerabilities successfully reproduced in isolated environments.
▪️ 1,169 working local privilege escalation (LPE) exploits developed.
▪️ 948 distinct LPE vulnerabilities identified after grouping related exploit variants.
▪️ 948 candidate patches generated for maintainer review.
The agents also produced 291 proofs of concept for information disclosure vulnerabilities.
These weren't simply suspicious lines of code flagged by static analysis. The system demonstrated working exploitation against test environments using a standard Linux distribution with common security protections enabled.
🤖 An entire security research team, automated
The pipeline divides the work between specialized AI agents:
▪️ Scout agents identify high-value code regions.
▪️ Analyst agents search for potential vulnerabilities.
▪️ Validation agents reproduce suspicious behavior.
▪️ Exploit-development agents establish whether the bugs can lead to privilege escalation.
▪️ Patch-generation agents prepare potential fixes.
Human security researchers review the results before reporting vulnerabilities to maintainers.
Interestingly, the agents examined approximately 2.8 million lines of code, only around 7% of the entire Linux kernel.
💰 The economics are changing
The full run cost $1,213,430 in API credits.
▪️ Average all-in cost per unique LPE: $1,279.
▪️ Average cost of developing a successful exploit after identifying a candidate: approximately $359.
For comparison, historical Linux kernel exploitation competitions have offered rewards of $20,000–$70,000 per vulnerability.
Those bounty amounts aren't guaranteed payouts, but they illustrate the growing economic advantage of automated vulnerability research.
🧠 A major leap in AI capability
An earlier GPT-5.6 Sol experiment in July discovered 166 unique LPE vulnerabilities.
The newer, not-yet-released cyber model identified 948 in October.
OpenAI also reports at least 10 previously unknown Linux exploitation techniques discovered in its research.
And this wasn't limited to generating exploits. The agents produced candidate fixes, turning vulnerability research into a more complete defensive workflow.
⚠️ Important distinction
Not all 948 vulnerabilities have been patched, and not all were previously unknown.
OpenAI says hundreds of reports and patches have already been sent to Linux maintainers, with additional disclosures ongoing.
Also, these are local privilege escalation vulnerabilities, meaning an attacker already needs some level of local access. They aren't automatically remote attacks against every Linux system.
Still, the implications are enormous.
AI isn't just making vulnerability discovery faster. It's dramatically reducing the cost of finding and validating exploitable security flaws.
The challenge now is making automated patching and defensive verification scale just as quickly.
🔗 Research: openai.com/index/a-thousand-…
#OpenAI #Cybersecurity #Linux #AIagents

🎮 244 animated pixel-art effects, completely open-source. And Claude Code can create new ones for your game.
Meet PixelFX, a new JavaScript library that combines ready-to-use game effects with an AI-assisted animation workflow.
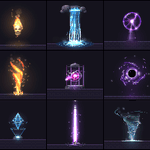
Fireballs, explosions, lightning, sword attacks, magical spells, weather, UI animations, and dozens of other effects are already included.
But here's the interesting part: every effect is generated from code, not a collection of pre-rendered images.
✨ What's included?
The library currently contains 244 effects across 21 categories:
▪️ Fire, explosions, smoke, and environmental effects.
▪️ Lightning, ice, water, and magical spells.
▪️ Sword attacks, projectiles, and impact animations.
▪️ Healing, poison, freezing, and other status effects.
▪️ UI transitions, collectibles, and achievement animations.
▪️ Animated creatures, spawn effects, and death sequences.
There's also an interactive gallery where you can preview animations, change colors, and experiment with different effects.
🤖 Claude Code can make new animations
PixelFX includes a dedicated Claude Code skill.
Instead of manually drawing every frame, you can describe the effect you want.
For example:
"Create a dark-purple lightning spell that charges for half a second, strikes the ground, and leaves glowing particles."
The agent can:
▪️ Generate the JavaScript effect.
▪️ Render preview frames.
▪️ Inspect the animation for visual problems.
▪️ Adjust timing, particles, colors, and movement.
▪️ Export the finished result.
This is code-assisted animation, not diffusion-based video generation.
⚔️ Characters actually perform their attacks
One especially interesting feature is the animation choreography system.
PixelFX includes 12 complete attack moves and action metadata for character-based effects.
Animations can include:
▪️ Wind-up before an attack.
▪️ Precise impact timing.
▪️ Hit-stop and screen shake.
▪️ Enemy reactions.
▪️ Recovery animations.
That makes effects feel connected to gameplay rather than floating independently on screen.
🛠️ Works with multiple game engines
You can use the JavaScript effects directly in Canvas, Phaser, PixiJS, and similar browser engines.
For other engines, export transparent PNG sprite sheets with frame metadata.
Supported workflows include Godot, Unity, GameMaker, LÖVE, and more.
The tools also support GIF and MP4 preview exports.
💰 Free and open-source
▪️ License: MIT for code and effects.
▪️ No cloud API required.
▪️ Deterministic, seed-based animation.
▪️ Adjustable colors, rotation, mirroring, and lighting.
▪️ Claude Code plugin included.
Some character-specific effects require adaptation to your game's sprites, and the bundled font has separate licensing terms.
For indie developers, this could eliminate a surprising amount of repetitive VFX work.
And because everything is code, the animations remain customizable rather than being locked into fixed image assets.
🔗 Live gallery: patch-gg.github.io/pixelfx/
💻 GitHub: github.com/patch-gg/pixelfx
#GameDev #ClaudeCode #PixelArt #OpenSource


🎬 Runway just made it possible to build AI video generation features directly from Claude Code, Codex, and Cursor.
The company has released Runway Dev plugins for coding agents, combining its generative media API, MCP server, and specialized development skills into one installation.
The idea: describe the media feature you want, and your coding agent can implement it without constantly switching between documentation, dashboards, and your editor.
🧠 What can the agent do?
Once connected to Runway Dev, your coding agent can:
▪️ Discover which image, video, and audio models your account can access.
▪️ Retrieve current model prices, capabilities, and input requirements.
▪️ Check account credit balances and project limits.
▪️ Write integration code using the official Runway SDKs.
▪️ Configure Model Routers to select models automatically.
▪️ Build real-time avatar integrations using Runway Characters.
▪️ Connect existing Recipes and published Workflows.
▪️ Investigate failed generation requests and inspect error details.
🚀 Example: AI product videos
Imagine an online store where every new product listing should automatically receive a short promotional video.
You could ask your coding agent to implement the feature.
The agent can inspect available Runway models, determine the correct inputs, configure an integration, write the necessary code, and set up the generation workflow.
Another example: add a video upscaling button to an existing application without manually constructing the entire API integration.
🔌 Supported environments
▪️ Claude Code.
▪️ OpenAI Codex.
▪️ Cursor.
The installation includes the Runway Dev MCP connection and seven specialized skills for building with its API.
🔧 Installation examples
Claude Code:
/plugin install runway-api@claude-plugins-official
Cursor:
/add-plugin runway-api
Codex uses Runway's plugin marketplace integration.
Authentication happens through your Runway Dev account. The plugin doesn't store an API key.
⚠️ What this isn't
The plugin isn't a new video generation model and doesn't make paid generation free.
It's an integration layer that helps an agent implement production workflows using the models and credits available through Runway Dev.
The bigger trend is interesting: coding agents are increasingly becoming interfaces to external creative infrastructure.
Instead of manually integrating every AI service, developers can describe the feature and let their agent handle much of the implementation.
🔗 runway.com/news/developers/r…
#Runway #MCP #CodingAgents #GenerativeVideo

🔐 Vercel just launched an AI security reviewer that checks your code every time you push to GitHub, even if you skip pull requests entirely.
It's called Vercel Security Review, and it's now available in public beta.
Instead of waiting for a developer to request a security audit, the system automatically analyzes source-code changes and reports potential vulnerabilities.
🔍 How it works
Once Security Review is enabled for a connected GitHub repository:
▪️ Every push triggers a security review.
▪️ Direct pushes to production branches are included.
▪️ Force pushes are checked too.
▪️ Findings appear in Vercel's Vulnerabilities dashboard.
▪️ Pull requests receive review comments linked to the findings.
Each vulnerability report includes:
▪️ A description of the potential problem.
▪️ The affected project, branch, and commit.
▪️ An AI-generated severity assessment.
▪️ A suggested fix.
🤖 AI can propose the correction
When a vulnerability is detected, developers can select Fix with Vercel Agent.
The agent analyzes the finding, proposes code changes, and opens a pull request.
Nothing gets merged automatically. The developer must review and approve the changes.
You can also export findings as Markdown or JSON, or access them through:
vercel security vulnerabilities
This allows external coding agents to work with the same security information.
🛠️ Custom security policies
Teams can define security policies in natural language, either globally or for individual projects.
These policies give the reviewer additional context about the application's architecture and security requirements.
💰 Availability and pricing
▪️ Public beta for Vercel Pro and Enterprise teams.
▪️ Security reviews are free until November 10, 2026.
▪️ After that, reviews use Vercel Agent pricing.
▪️ Billing includes the underlying model's inference cost plus $0.25 per million tokens processed by Vercel.
⚠️ Important limitation
Security Review is static source-code analysis.
It doesn't replace penetration testing, runtime security analysis, or a comprehensive security audit.
The interesting development is that security scanning is becoming another continuous AI-assisted development workflow.
Code gets written, checked, reviewed, and potentially corrected before a human even opens the deployment dashboard.
🔗 vercel.com/changelog/vercel-…
#Vercel #Cybersecurity #CodingAgents #DevTools


🚗 Baidu just unveiled an AI world model that can generate up to 100,000 kilometers of virtual driving every day.
It's called Apollo World, and its purpose isn't to generate cinematic videos.
It's designed to train and evaluate self-driving cars inside interactive environments that respond to their decisions.
Baidu says the system can simulate the equivalent of approximately three years of real-world road testing in a single day.
🌍 How Apollo World works
Instead of creating a fixed video of traffic, Apollo World simulates a dynamic environment where vehicles, pedestrians, and other road users behave as interacting AI agents.
The system follows a continuous feedback loop:
▪️ Generate the current world state.
▪️ Produce camera and LiDAR observations.
▪️ Let the autonomous vehicle perceive the scene.
▪️ Receive its steering, braking, or acceleration decisions.
▪️ Update the environment based on those actions.
▪️ Generate the next observations.
That makes it a closed-loop simulation rather than simple video playback.
🚦 Training for difficult situations
Apollo World can simulate dangerous scenarios that would be risky or expensive to reproduce on real roads.
Examples include:
▪️ Animals suddenly crossing traffic lanes.
▪️ Cyclists entering intersections unexpectedly.
▪️ Complex interactions between multiple road users.
▪️ Different traffic behaviors across cities and countries.
▪️ Complete virtual journeys from pickup to destination.
The AI can vary how surrounding traffic reacts to the autonomous vehicle's decisions.
🧠 More than individual driving clips
Traditional driving simulations often focus on isolated scenarios lasting several seconds.
Baidu wants Apollo World to simulate entire journeys through virtual cities, including trips lasting ten minutes or longer.
The model generates synchronized visual and LiDAR data, allowing autonomous driving systems to use inputs resembling their actual sensors.
🚀 Already being used
Baidu says Apollo World is supporting the training and validation of its Apollo Go robotaxi technology.
This is not a publicly downloadable generative video model.
It's a specialized physical-AI simulation system developed for autonomous driving.
⚠️ The limitation: Baidu hasn't independently demonstrated that the simulated mileage translates into equivalent real-world safety improvements. Physical road testing remains necessary.
Still, the direction matters.
Instead of teaching autonomous vehicles only from past driving recordings, AI world models can create interactive situations, vary the outcome, and test decisions before they happen on public roads.
🔗 apollogo.com/technology/
#Baidu #WorldModels #AutonomousDriving #PhysicalAI


🎙️ This new voice AI can listen while speaking, ignore background conversations, and continue talking while other agents work on your tasks.
Meet MOSS-Live 1.0, a real-time multimodal interaction system designed to make conversations with AI feel more natural.
Most voice assistants follow a rigid cycle: listen, process, speak, stop.
MOSS-Live is built around full-duplex communication, meaning it can receive and process new audio while generating its own response.
🗣️ What makes it different?
▪️ Natural interruptions: Distinguishes a genuine interruption from a simple "mm-hmm" or "right."
▪️ Background speech filtering: Attempts to recognize when people are talking to each other rather than addressing the AI.
▪️ Conversation continuity: Can resume an interrupted explanation after the user changes topics.
▪️ Live video understanding: Processes camera feeds and screen sharing during conversations.
▪️ Simultaneous interpretation: Translates speech continuously without waiting for an entire sentence or speech to finish.
▪️ Proactive interaction: Can respond when user-defined conditions are met.
🧠 Two cooperating AI components
The architecture separates immediate conversation from slower reasoning.
Foreground model: Handles speech, audio-visual perception, conversational timing, and interruption decisions.
Background model: Performs research, reasoning, tool use, and longer-running tasks.
A coordination layer shares context and task state between them.
This allows the assistant to continue speaking naturally while another component completes a request.
🎬 Demonstrated scenarios
The team shows MOSS-Live:
▪️ Joining a group meeting, researching information, and summarizing decisions.
▪️ Planning a road trip while adapting to changing preferences.
▪️ Using a live phone camera to identify locations and answer questions.
📊 Performance
The company reports:
▪️ 51% tool-call success on FDB v3.
▪️ 57.93% multi-turn task success on τ-Voice.
These are project-reported benchmark results.
🔌 Availability
MOSS-Live is accessible through a real-time WebSocket API.
▪️ Model ID: moss-live-1.0
▪️ Endpoint: /v1/realtime
▪️ Input: Streaming audio and video.
▪️ Output: Streaming audio and text.
▪️ Pricing: Free for a limited introductory period.
This is currently a hosted service, not a publicly released open-weight model.
The interesting development is the architecture: voice assistants are becoming continuous conversational systems instead of simple question-and-answer interfaces.
🔗 moss.cn/en/models/moss-live
#VoiceAI #MOSS #MultimodalAI #AIagents
🖥️ An open-source AI agent family claims up to 88.64% success on OSWorld-Verified. And the models can control both desktop applications and websites.
Meet NorthCUA, a new family of computer-use models designed to transform natural-language instructions into real actions on a computer.
Instead of generating text instructions for a human to follow, these agents can interpret screenshots, use mouse and keyboard actions, navigate interfaces, and complete multi-step workflows.
🧠 Three model sizes
▪️ NorthCUA-Nano: 9B parameters, dense architecture.
▪️ NorthCUA-Mini: 35B total parameters, 3B active.
▪️ NorthCUA-Pro: 397B total parameters, 17B active.
All three models have publicly available weights on Hugging Face under Apache 2.0.
📊 Reported benchmark results
OSWorld-Verified task success:
▪️ Nano: 78.90%.
▪️ Mini: 85.30%.
▪️ Pro: 88.64%.
WebArena-Verified task success:
▪️ Nano: 67.16%.
▪️ Mini: 70.43%.
▪️ Pro: 73.89%.
Important: These are results reported for research checkpoints. The authors explicitly warn that they are not independent measurements of the currently downloadable model files.
🔧 How does the system work?
NorthCUA separates the AI model from the software responsible for interacting with the computer.
The open-source NorthCUA Harness provides:
▪️ Desktop mouse, keyboard, and screenshot tools.
▪️ Browser navigation and interaction.
▪️ Long-horizon memory and context management.
▪️ Execution traces and stored artifacts.
▪️ Independent outcome verification.
▪️ Recoverable task batches and retry handling.
The official repository includes demonstrations involving GeoGebra and Blender, showing agents working on 3D content and native application interfaces.
🧪 Training approach
The technical report describes more than 100,000 GUI interaction trajectories and approximately 4 million interaction steps used during broad training.
Subsequent stages combine verified long-horizon examples with reinforcement learning on desktop and web tasks.
⚠️ Hardware requirements
The Pro model is enormous, with roughly 794GB of unquantized weights. It's not intended for an ordinary consumer GPU.
Nano is the more approachable starting point, although practical performance still depends on the runtime and hardware.
The model weights and Harness are separate downloads, and the official Harness is required for the intended computer-use workflow.
The interesting direction is clear: open-weight AI agents are moving beyond browser-only automation toward general interaction with desktop software.
🔗 GitHub: github.com/beipo-ai/NorthCUA
🔗 Models: huggingface.co/beipo-ai/Nort…
#NorthCUA #OpenSource #ComputerUse #AIagents
🧬 Google DeepMind just showed an AI agent performing a drug-discovery workflow that normally takes days, in about one hour.
The team has introduced Cheminformatics Skills for Google Antigravity, turning its agentic development environment into a computational chemistry research workspace.
Instead of merely answering questions about molecules, the agent can search scientific databases, analyze chemical structures, train prediction models, and propose new compounds.
🔬 What can it actually do?
▪️ Search scientific literature and chemical databases for thousands of compounds.
▪️ Extract molecular structures and associated experimental results.
▪️ Compare related molecules through matched molecular pair analysis.
▪️ Analyze structure-activity relationships.
▪️ Train machine learning models to predict molecular properties.
▪️ Propose new compounds and potential synthesis routes.
▪️ Generate chemical reaction mechanisms and export results for further analysis.
🧠 The important architectural detail
Google combines language-model reasoning with established scientific tools.
The LLM handles planning, literature analysis, database navigation, and interpretation.
Specialized tools handle deterministic chemical calculations.
The system uses:
▪️ RDKit: Molecular structure processing and computational chemistry.
▪️ ChEMBL: Bioactivity and drug-discovery data.
▪️ PubChem: Chemical compounds and related scientific information.
This reduces the need for the language model to invent its own calculations.
🧪 The demonstration
Google used real-world lung cancer treatments as a starting point.
The agent analyzed compounds related to crizotinib and lorlatinib, investigated ways to reduce molecular flexibility, and proposed new rigidified macrocycles.
It also trained multiple potency-prediction models, assessed them using held-out data, and suggested possible synthesis strategies.
Google says the complete demonstrated workflow took approximately one hour.
⚠️ This doesn't mean AI discovered a clinically validated drug.
The proposed molecules remain computational hypotheses.
They still require synthesis, laboratory testing, and experimental verification.
🌍 Availability
The Cheminformatics Skills are available through the Science plugin in Google Antigravity.
Google is also offering up to 10,000 eligible scientists access to its highest Antigravity usage tier for six months, subject to selection and capacity.
The interesting development isn't just faster molecular analysis.
It's turning an AI agent into an interface for established scientific software, databases, and experimental workflows.
🔗 deepmind.google/blog/agentic…
#GoogleDeepMind #AIforScience #DrugDiscovery #AgenticAI
🎨 IBM built an AI that creates PowerPoint presentations in your company's design language, then checks and fixes its own layout mistakes.
It's called Palette, a research system based on a 20B-parameter open-weight model fine-tuned with LoRA.
The idea isn't simply generating attractive slides.
It's generating consistent, editable presentations that follow a particular visual system, preserve the source information, and avoid broken layouts.
🧠 Two roles, one model
Palette separates presentation creation into two stages:
▪️ Designer: Produces a structured JSON brief defining slide content, visual hierarchy, typography, colors, and layout decisions.
▪️ Coder: Converts each slide specification into executable JavaScript using PptxGenJS.
The coder handles one slide at a time, allowing parallel generation.
IBM reports this makes the coding stage approximately 6–7× faster than processing everything sequentially.
🛠️ An automatic repair system
The model doesn't simply generate a deck and hope it looks right.
A validation system checks for:
▪️ Overlapping text and objects.
▪️ Content overflowing slide boundaries.
▪️ Incorrect colors and malformed style values.
▪️ Layout problems that can be detected geometrically.
When a problem appears, a separate editor proposes a corrected version.
The system keeps the correction only if the checker confirms an improvement.
📚 How was it trained?
IBM created approximately:
▪️ 1,000 synthetic presentations.
▪️ 10,000 slides.
▪️ Design examples following IBM's visual language.
Training examples also include explanations of why particular layouts were chosen.
You can even add directives like [[make this a timeline]] to control individual design decisions.
📊 Results
On PresentBench, Palette ranked:
▪️ #1 in Economics.
▪️ #1 in Education.
▪️ #3 in Talk presentations.
▪️ #2 overall across the three evaluated domains.
Its average score was 59.7, compared with 60.8 for NotebookLM.
⚠️ Availability: This is currently a research prototype. The article does not provide a public downloadable Palette checkpoint or a ready-to-use presentation app.
Still, the approach is compelling.
Instead of relying exclusively on a huge general-purpose model, IBM combines a smaller specialized model with structured planning and automated quality checks.
That could be especially useful for organizations generating large numbers of reports, training materials, and branded presentations.
🔗 huggingface.co/blog/ibm-rese…
#IBMResearch #OpenWeights #GenerativeAI #AItools


⚡ 1,500 tokens per second. Fireworks AI is pushing LLM inference to a completely different speed level.
At its Forge conference, Fireworks unveiled a new ultra-fast inference mode powered by NVIDIA Blackwell GPUs.
The company demonstrated generation speeds of up to 1,500 tokens/second on DeepSeek V4.1 Flash.
For comparison, many conventional API workloads operate at only a fraction of that speed.
But the important question isn't how fast a model can generate text. It's what happens when an AI agent has to make dozens of consecutive model calls.
🚀 Ultra-fast inference
Fireworks reports that a benchmarked 30-turn agent workflow dropped from approximately:
▪️ Standard inference: 60 seconds.
▪️ Ultra-fast inference: 8 seconds.
That's a 7.5× reduction in total execution time.
The numbers come from Fireworks' own benchmark and shouldn't be interpreted as guaranteed performance for every model.
💰 Background Mode: Pay less when speed doesn't matter
The company also introduced a different approach for tasks that don't require immediate responses.
▪️ Run eligible background jobs at approximately 50% of standard inference pricing.
▪️ Use multi-day prompt caching to avoid repeatedly processing large contexts.
▪️ Support higher agent concurrency.
▪️ Run evaluations, synthetic data generation, and research workloads more economically.
🧩 Fireworks Nexus
The announcement also introduces Nexus, which brings open models into existing coding and coworking tools.
Instead of committing every task to one expensive model, teams can use different models according to their capabilities, costs, and workloads.
Centralized spending controls help organizations monitor those decisions.
Why does this matter?
An agent calling a model 30 times can be slow even when individual responses feel fast.
Faster inference changes the experience from waiting for an automated workflow to watching it execute almost interactively.
And cheaper background execution opens another possibility: running more agents and experiments without paying premium latency prices for tasks that can wait.
Ultra-fast is currently in public preview.
🔗 fireworks.ai/blog/fireworks-…
#FireworksAI #LLM #AIInfrastructure #AIagents


⚡ Cognition just built an AI coding model that's 3× faster and 5× cheaper than its own flagship SWE-2.
Meet SWE-2 Flash, a coding model designed for agents that need to write, debug, review, and maintain software without burning through expensive inference budgets.
Instead of training another enormous model from scratch, Cognition started with Inkling-Small from Thinking Machines and substantially improved its coding capabilities.
🧠 What powers SWE-2 Flash?
▪️ 276 billion total parameters.
▪️ Only 12 billion active parameters per token.
▪️ Mixture-of-experts architecture.
▪️ Large-scale mid-training on trillions of tokens of curated code, scientific material, and technical content.
▪️ Reinforcement learning using diverse, verifiable software engineering tasks.
The team introduced a mid-training phase before reinforcement learning to improve the model's reasoning and coding foundation.
📊 The improvements are substantial
Compared with the original Inkling-Small model:
▪️ Terminal-Bench 4.0: 0.9% → 20.0%.
▪️ FrontierCode 2.0: 3.2% → 24.0%.
Cognition says SWE-2 Flash outperforms American open-weight coding models several times its size on selected benchmarks.
🚀 Speed and cost
▪️ SWE-2 Flash: approximately 200 tokens/second.
▪️ SWE-2: approximately 60 tokens/second.
▪️ Flash costs one-fifth as much as SWE-2.
For coding agents executing dozens of sequential model calls, this can significantly reduce waiting time.
🔧 Where can you use it?
SWE-2 Flash is already available in:
▪️ Devin Desktop.
▪️ Devin CLI.
It's intended for everyday engineering workflows: implementing features, code review, documentation, maintenance, and automation.
⚠️ Are the weights open?
Not publicly.
Cognition plans a controlled access program for trusted industry partners and researchers, citing cybersecurity risks associated with advanced coding capabilities.
This is an important distinction from fully open-weight models.
The bigger takeaway: specialized mid-training and reinforcement learning can make a relatively small active-parameter model competitive with much larger systems.
For practical coding agents, intelligence per dollar may matter more than raw parameter count.
🔗 cognition.com/blog/swe-2-fla…
#CodingAI #Cognition #Devin #AIModels


🚨 Anthropic is preparing for one of the biggest AI IPOs in history. The Claude maker has launched its official IPO website.
The company has opened ipo.anthropic.com/, currently displaying a minimalist page with the message: "More information to come."
But the regulatory process is already underway.
📈 Here's what's confirmed:
▪️ October 26, 2026: Anthropic publicly filed its S-1 registration statement with the US Securities and Exchange Commission.
▪️ November 2: The company submitted an amended filing containing updated financial disclosures.
▪️ Exchange: Nasdaq Global Select Market.
▪️ Ticker: ANT.
▪️ Lead underwriters: Goldman Sachs and Morgan Stanley.
The offering price, number of shares, and final listing date have not yet been announced.
🌍 Retail investors are part of the plan
Anthropic is preparing international retail offerings through authorized financial institutions.
Participating platforms include:
▪️ Interactive Brokers and Revolut in eligible European markets and the UK.
▪️ SBI, Rakuten, Mizuho, and Mitsubishi UFJ Morgan Stanley in Japan.
▪️ Additional brokers across Australia, Canada, and other eligible markets.
According to a Japanese regulatory filing, Anthropic could allocate up to ¥552.9 billion ($3.5 billion) in shares to investors in Japan alone.
🗓️ What's next?
According to Bloomberg and Reuters, investor marketing could begin during the week of November 9, with a potential public debut before the end of November.
These dates remain tentative, and the registration statement has not yet become effective.
The IPO could become a defining moment for the generative AI industry, giving public investors direct exposure to one of the leading frontier model developers.
🔗 IPO portal: ipo.anthropic.com/
#Anthropic #Claude #IPO #ArtificialIntelligence

🧊 A new AI model can generate, edit, and complete 3D objects without rebuilding the entire mesh.
Researchers at Nanjing University have introduced SeMo3D, a unified 3D generation framework designed to solve a frustrating problem with existing AI tools.
When you ask most 3D models to change one small detail, they regenerate the entire object. That can accidentally modify parts you wanted to preserve.
SeMo3D changes only the selected region and keeps everything else intact.
🔧 One model, three tasks
▪️ 3D Generation: Create an entirely new 3D object from a reference image.
▪️ 3D Editing: Add, remove, or replace specific parts without regenerating the rest.
▪️ 3D Completion: Reconstruct missing geometry while preserving the existing structure.
All three operations use the same selective modeling approach. Only the region selected for synthesis changes.
🧠 How does it work?
SeMo3D introduces Region-Selective Denoising and a multi-condition diffusion transformer called Omni3DiT.
Instead of applying noise to the complete 3D representation, the system modifies only selected spatial tokens.
Unselected tokens remain unchanged throughout generation.
The model also combines three complementary inputs:
▪️ Images define appearance and visual details.
▪️ Text describes semantic changes and desired features.
▪️ Sparse 3D points control geometry and spatial positioning.
Image guidance is required, while text and point guidance are optional.
🚀 No paired editing datasets required
The training process randomly selects regions of existing 3D assets, treating one region as the content to generate and the remainder as context.
By varying the region size, the same training procedure learns generation, editing, and completion without requiring separate before-and-after editing datasets.
The architecture builds on Trellis2's structured 3D latent representation.
📊 Benchmark results
The researchers evaluated SeMo3D across Toys4K, Edit3D-Bench, and Omni-Comp.
On the 3D completion benchmark:
▪️ HY3D-Omni with additional point guidance: F-Score 0.412
▪️ SeMo3D with point guidance: F-Score 0.541
For generation, SeMo3D also reported stronger geometric accuracy and visual similarity than the tested baselines on most metrics, although available conditioning inputs differ between methods.
The authors report approximately 5 seconds to generate a 512-resolution 3D asset in their experimental setup.
🤖 AI agents can use it too
The researchers demonstrated SeMo3D integrated with GPT-6 Astra, Codex, and GPT-Image.
An agent can interpret natural-language editing requests, prepare reference images, determine which region needs modification, and invoke the appropriate modeling operation.
Interactive examples are available on the project website, with downloadable GLB and PLY assets.
⚠️ Availability and limitations
The project page and research paper are public, but model weights and complete inference/training code have not been released yet.
Very thin structures and complex text instructions also remain challenging.
Still, the direction is compelling: instead of repeatedly generating whole 3D assets, AI systems could progressively build and refine objects while preserving previous work.
A potentially valuable workflow for game development, robotics, AR/VR, and AI-driven 3D creation.
🔗 Project: xiaokunsun.github.io/SeMo3D.…
💻 GitHub: github.com/XiaokunSun/SeMo3D
📄 Paper: arxiv.org/abs/2611.02568
#SeMo3D #GenerativeAI #3DGeneration #AIResearch
🎬 Viggle just released open weights for AI-powered video remaking. And it can work on entire films, not just short clips.
Meet Viggle Remake, a video-to-video editing system built on MiniMax H3 that lets you replace characters, redesign scenes, change outfits, remove objects, or completely transform the visual style of existing footage.
The goal is to preserve the original motion, camera movements, timing, and soundtrack while changing what appears on screen.
And the most interesting part? An AI agent can manage the entire process through MCP.
🎥 What can Viggle Remake do?
▪️ Replace one or multiple actors with entirely different characters.
▪️ Change clothing, hairstyles, and character appearances.
▪️ Add, replace, or remove objects from existing footage.
▪️ Transform backgrounds, weather, lighting, and environments.
▪️ Recreate scenes in completely different visual styles.
▪️ Process longer videos by automatically splitting them into manageable segments.
The team demonstrated a 116-second music video containing 69 cuts, along with a 101-second action sequence featuring character replacements.
🤖 Agent-first video editing
Viggle Remake includes an MCP server compatible with Claude Code, Codex, and other MCP-capable agents.
You can describe the desired transformation in natural language, such as "turn everyone into cats."
The agent then:
▪️ Analyzes the original video and detects scene cuts.
▪️ Divides the footage into rendering windows.
▪️ Creates reference keyframes showing the desired changes.
▪️ Generates structured prompts for each segment.
▪️ Renders and reviews the results.
▪️ Assembles the finished video with the original soundtrack.
The MCP server provides 27 tools for orchestrating this pipeline.
🧠 Under the hood
Viggle Remake uses two rank-256 LoRA adapters on MiniMax H3:
▪️ Swap: Replaces people and characters, including multiple subjects in one scene.
▪️ Edit: Changes objects, backgrounds, weather, lighting, and other visual elements.
The two LoRAs and reference sampler require approximately 5.5 GB to download, but the underlying model is much larger.
The standard setup needs approximately 144 GB of base-model files and a high-memory GPU.
💻 What about consumer GPUs?
The team also released:
▪️ ComfyUI custom nodes and ready-to-use workflows.
▪️ Optimized INT8 and GGUF model files.
▪️ Q4_K_M, Q6_K, and Q8_0 quantizations.
▪️ Configurations tested on GPUs with as little as 12 GB VRAM, using memory offloading and constrained rendering settings.
▪️ Smaller rank-128 and rank-64 LoRAs, approximately 1.34 GB and 0.67 GB respectively, with reportedly near-identical results.
⚠️ Important limitations
Individual rendering windows are limited to roughly 12–14 seconds. Longer videos require segmentation and stitching.
Manual editing also needs 1–4 prepared reference frames and a carefully structured six-section prompt. This is more demanding than Viggle Animate.
The model can struggle with fine details, unusual non-human characters, and timing consistency across complex shots.
The weights are available under the MiniMax H3 Community License, while the accompanying code uses Apache 2.0.
There's also a hosted Viggle app for users who don't want to configure local inference.
The bigger idea: video editing is becoming an agent-controlled workflow, where you describe the transformation and an AI system handles the technical production steps.
🔗 Try it: viggle.ai/meme/app/home?ui=v…
🔗 Open weights: huggingface.co/Viggle/Viggle…
#Viggle #VideoAI #OpenWeights #ComfyUI
🧠 What if your AI agent could improve itself without retraining the model?
Researchers at Renmin University of China have released FlashRSI, an open-source framework for recursive self-improvement of AI agents.
Instead of updating neural network weights, FlashRSI optimizes the surrounding agent system: prompts, instructions, skills, tools, runtime settings, and configuration.
The idea is simple: test an agent, identify weaknesses, generate improvements, benchmark the changes, and keep the best-performing version.
🔄 How FlashRSI works
▪️ 1. Capture the baseline: Save the agent's initial instructions, skills, tools, and configuration as a versioned Snapshot.
▪️ 2. Generate improvements: A separate Worker model analyzes feedback and proposes changes to selected agent resources.
▪️ 3. Test candidates: Execute each modified agent through its supported harness and evaluate it using a defined benchmark protocol.
▪️ 4. Compare results: Analyze task performance, execution trajectories, errors, and resource usage.
▪️ 5. Select and repeat: Preserve successful candidates, track their ancestry, and continue optimization.
Every experiment records the configuration, modified files, agent trajectories, metrics, and artifacts. You can trace which changes produced a particular result.
⚡ 13 optimization algorithms, 30 benchmark suites
FlashRSI brings multiple existing self-improvement approaches into a unified research framework.
Supported methods include OPRO, GEPA, EvoPrompt, SkillOpt, ACE, DarwinX, RRSI, and others.
Benchmarks cover coding, mathematical reasoning, question answering, web research, document processing, tool use, and interactive environments.
📊 Does it actually improve performance?
The authors report some substantial gains.
For example, using RRSI with Claude Code on AppWorld:
▪️ Baseline: 64.88%
▪️ Optimized: 92.86%
▪️ Improvement: +27.98 percentage points
However, results depend heavily on the optimization method and benchmark. Some configurations perform worse on out-of-distribution tasks. These are project-reported results, not guaranteed improvements.
🔌 Agent integrations
The latest GitHub README lists seven available harness integrations:
▪️ Claude Code
▪️ OpenAI Codex
▪️ MiniAgent
▪️ Pi
▪️ Hermes
▪️ OpenClaw
▪️ OpenCode
An important distinction: some integrations use Python implementations of selected upstream runtime behavior rather than launching the original CLI, so feature coverage can differ.
FlashRSI is released under Apache 2.0, with configurable models for the Target agent and the Worker.
The interesting shift here is that AI improvement doesn't necessarily require a larger model or another training run.
Sometimes, improving the instructions, tools, and architecture around an existing model can produce meaningful gains.
And FlashRSI makes those improvements measurable, reproducible, and easier to investigate.
🔗 Project: ruc-nlpir.github.io/FlashRSI…
💻 GitHub: github.com/RUC-NLPIR/FlashRS…
#AIagents #OpenSource #AgenticAI #FlashRSI

🚀 Running powerful AI models locally without an NVIDIA GPU? Hi, I'm Hal is making that easier for AMD users.
A small development team is building one-click Windows installers for AI tools that traditionally depend on NVIDIA's CUDA ecosystem.
The goal: run music generation, video creation, lip-sync, 3D reconstruction, and video upscaling locally on AMD hardware, without spending hours fixing dependencies.
🎵 Already available: YuE2 on AMD
The team has released a free One Click Local AI installer (v0.8.0) for YuE2, the open-weight music generation model.
YuE2 can generate complete songs with vocals and instruments from lyrics and style descriptions. The underlying 3B-parameter model also supports editable melody and chord planning, covers, and music editing.
The AMD implementation uses ROCm instead of CUDA.
▪️ Tested on AMD Ryzen AI Max+ 395 (Strix Halo) with Radeon 8060S graphics.
▪️ Development and testing hardware: BOSGAME M5 mini PC with 96GB RAM.
▪️ A complete song reportedly takes around 20–25 minutes to generate.
▪️ Windows 11 support, with at least 64GB system RAM on the verified configuration.
▪️ Approximately 40GB of free storage required.
▪️ Music generation runs locally after the initial setup and model downloads.
🛠️ More AMD AI tools are coming
The project's roadmap includes:
▪️ Wan 2.2 Video Creation Studio — generate videos from text or images, create consistent character visuals, and prepare finished video projects.
▪️ LatentSync — synchronize facial lip movements with speech, narration, or music.
▪️ TRELLIS.2 — reconstruct textured 3D assets from a single image.
▪️ InfiniteTalk — generate talking and singing avatar videos.
▪️ FlashVSR — AI-powered video super-resolution and enhancement.
The Wan 2.2 studio and LatentSync AMD ports are marked as completed, while their public installer packs are still coming. The remaining three are listed as planned.
🔍 What about SeedVR2?
Interestingly, SeedVR2 isn't listed on the main website.
However, the team has publicly claimed an AMD port of SeedVR2, alongside RIFE, Real-ESRGAN, CogVideoX, and Wan VACE.
Those additional tools don't currently have public installers in the project's GitHub release.
💻 Hardware recommendations
The website also includes a hardware guide that distinguishes actually tested AMD systems from configurations that are only expected to work.
One important limitation: the currently available installer is verified for Strix Halo hardware, not every Radeon GPU.
This project isn't developing new foundation models. It's adapting existing AI software and simplifying local installation.
And that's valuable. For AMD users, running advanced generative AI shouldn't automatically mean buying an NVIDIA card.
🌐 hiimhal.com/
GitHub: github.com/HiImHal/one-click…
#AMD #LocalAI #YuE2 #GenerativeAI
🛠️ What if AI agents could build editable 3D objects with moving parts using only a few lines of Python instead of hundreds of lines of Blender code?
Meet sand3d, a new open-source Python library designed specifically for language models.
Its goal is to make procedural 3D modeling easier for both AI agents and humans.
And its approach is surprisingly straightforward.
Give an LLM a small vocabulary for creating geometry instead of asking it to memorize Blender's entire API.
What makes sand3d different?
▪️ Compact API: Approximately 70 public operations covering modeling, geometry and assembly.
▪️ Token efficiency: The complete API documentation fits into roughly 3,643 tokens.
▪️ Named geometry: Reference parts, faces and edges by meaningful names instead of manually calculating coordinates.
▪️ Parametric objects: Create shapes using profiles, extrusions, revolutions, lofts and Boolean operations.
▪️ Articulated assemblies: Define hinges, sliders, rotating components and movement limits.
▪️ Multiple export formats: GLB, USD, URDF, OBJ and STL.
▪️ Deterministic generation: Identical programs produced byte-identical meshes in the developer's tests.
Here's a practical example.
Imagine asking a coding agent to model a washing machine.
Using sand3d, it can create:
▪️ Cabinet.
▪️ Rotating drum.
▪️ Opening door with glass.
▪️ Sliding detergent drawer.
▪️ Adjustable control dial.
Each component can have its own material, position and joints.
The resulting assembly isn't just a static mesh.
You can open the door, slide the drawer and rotate the controls in the interactive viewer.
The underlying architecture is clever.
sand3d is built on top of Blender's Python API, but exposes a smaller, more structured modeling language.
Instead of writing low-level operations, the agent uses high-level primitives such as:
extrude, revolve, sweep, fillet, hole, joint, assembly and export.
This reduces repetitive code and makes generated models easier to inspect.
How much does it save?
In the developer's comparisons:
▪️ 4× fewer tokens than LLM-generated Blender Python on the evaluated CAD parts.
▪️ 2.3× fewer tokens than CadQuery programs in one comparison.
▪️ 6× fewer tokens than FeatureScript in another.
▪️ 2× fewer tokens than Articraft's Python SDK on articulated objects.
These are comparisons of program length, not independent measurements of modeling quality or success rates.
The export formats also carry different information.
▪️ GLB: Geometry, materials and joint metadata.
▪️ URDF: Articulated structures for robotics tools such as ROS, PyBullet and MuJoCo.
▪️ USD: Scene hierarchy, materials and physics-related structures.
▪️ OBJ/STL: Geometry for conventional 3D workflows and fabrication.
Installation is simple:
pip install sand3d
The library supports Python 3.11 or 3.13 with compatible Blender Python packages.
The project is Apache-2.0 licensed.
But there's an important distinction.
sand3d isn't an AI model and doesn't automatically generate photorealistic 3D objects from images.
It's a programming toolkit that makes it easier for AI agents to construct editable geometry.
Complex organic objects, advanced materials and production-level simulations still require additional tools and validation.
Why this matters:
AI-generated 3D meshes can be difficult to modify after generation.
Procedural models are different.
You can change dimensions, replace components, adjust joints and rebuild the geometry without starting from scratch.
Instead of asking an AI to generate a 3D object, you can ask it to write a program that builds one.
That could be particularly useful for game development, CAD automation and robotics simulation.
🌐 sand3d.sandflow.ai/
💻 github.com/Sandflow-ai/sand3…
#AICoding #Procedural3D #Blender #OpenSource

🚀 OpenAI just gave ChatGPT native GIF generation with Images 2.6.
You can now turn a simple text prompt or an existing image into an animated GIF, without needing a separate animation or video editing tool.
But GIFs are only part of the update. Images 2.6 brings faster generation, better visual consistency, and new controls for developers.
🎞️ Native GIF generation
▪️ Create animated GIFs from text prompts or uploaded photos.
▪️ Inspect individual animation frames, edit them, and adjust playback speed directly in ChatGPT.
▪️ Generate looping characters, animated stickers, memes, moving product visuals, and game assets.
▪️ Share the resulting GIF without manually assembling individual frames.
⚡ Two new API models
▪️ GPT-Image-2.6 Flare focuses on speed and rapid iteration. OpenAI says low-quality image generation can take as little as 6 seconds.
▪️ GPT-Image-2.6 Sunburst prioritizes image quality, detailed compositions, and consistency across editing iterations.
OpenAI claims image generation is now 50% faster than before.
🛠️ More control for developers
Both API models support:
▪️ GIF output: Generate animated GIFs directly through the Images API.
▪️ Frame control: Configure between 2 and 64 frames, with durations of 20–2,000 milliseconds per frame, subject to size limits.
▪️ SVG export: Generate vector graphics for interfaces, websites, and branding.
▪️ Markup-guided editing: Mark specific areas of an image and describe the changes.
▪️ Complexity settings: Choose low, medium, or high planning effort independently of rendering quality.
For API developers, GIF generation uses output_format: "gif" on the image generation endpoint. GIF output isn't supported directly by the image editing endpoint.
API image output costs $30 per million tokens for both models, with the actual generation cost depending on token usage.
🌍 Availability
Images 2.6 is available globally across ChatGPT subscription tiers, Codex, and the API.
This isn't a replacement for full video generation. It's a lightweight way to create short, silent animations without a traditional animation pipeline.
And with OpenAI reporting more than 4 billion images generated per week, native animation could become a significant addition to everyday creative workflows.
Official announcement:
openai.com/index/introducing…
#OpenAI #ChatGPT #AIArt #GenerativeAI
🤖 NVIDIA built an AI animation system that generates character movement in real time, including walking, running, jumping, sitting and interacting with objects, without manually authoring every transition.
Meet MotionBricks, a generative motion framework from @NVIDIAAI that works with both animated characters and humanoid robots.
And its official Unreal Engine 5 demonstration runs for 2 minutes and 40 seconds without cuts.
The interesting part:
Instead of selecting prerecorded animation clips from a giant library, MotionBricks generates new motion based on where a character should go and what it should do.
What can it generate?
▪️ Natural transitions between standing, walking, jogging and running.
▪️ Movement in different directions and speeds.
▪️ Stylized locomotion, including zombie walks, limping and crouching.
▪️ Jumping over obstacles.
▪️ Sitting on chairs and interacting with objects.
▪️ Motion connecting arbitrary target poses.
▪️ Continuous movement for humanoid robots.
How does it work?
MotionBricks doesn't generate an entire animation sequence all at once.
Each generation receives:
▪️ The character's four most recent poses.
▪️ Between one and four target poses.
It then creates a short sequence of movement connecting the previous state to those targets.
Each generated segment covers approximately 0.6–1.9 seconds.
The system continuously chains these segments together.
Three learned modules share the work:
1. Root module
Predicts how long the movement should take and where the character's root should travel.
2. Pose module
A masked-token transformer generates the motion representation along the planned trajectory.
3. Decoder
A VQ-VAE converts motion tokens into continuous character poses.
But the clever part is Smart Primitives.
These are reusable interaction descriptions containing target poses, objects, spatial relationships and behavior sequences.
Developers can combine them to build more complicated interactions.
For example, a character can approach a bench, climb over it, continue walking and then sit down.
The model fills in the transitions.
And the performance is impressive.
The researchers report:
▪️ 15,000 FPS throughput in their high-performance motion-generation benchmark.
▪️ Approximately 2ms inference latency.
▪️ Training across more than 350,000 motion clips.
▪️ Realtime generation and playback at 30Hz in the released examples.
The 15,000 FPS figure measures model throughput under benchmark conditions, not a game rendering at 15,000 FPS.
The released models cover two different systems.
▪️ SOMA: A parametric human body model.
▪️ Unitree G1: A humanoid robot.
Both use the same generation framework, with different skeletal representations.
Can you run it?
Yes. NVIDIA released:
▪️ Pretrained ONNX models.
▪️ SafeTensors checkpoints.
▪️ Python runtime and inference examples.
▪️ In-betweening demo.
▪️ Interactive scene preview.
▪️ Smart Primitive and scene editors.
The runtime uses NVIDIA TensorRT, Warp and Newton.
The official demos were tested on Windows and Linux using an RTX 4090.
Model weights are covered by the NVIDIA Open Model Agreement, with additional licensing details for the surrounding code.
Important limitations:
The current pretrained checkpoints target specific skeleton formats. This isn't a universal animation model for arbitrary creatures.
Generated movement also requires suitable scene constraints and control logic.
And successful simulated movement doesn't guarantee reliable execution on a physical robot.
Why this matters:
Game animation traditionally relies on massive libraries of clips, animation graphs, blending rules and hand-authored transitions.
MotionBricks explores a different workflow: describe the desired interaction and let a generative model create the movement connecting the states.
The same principle could eventually power interactive game characters and physical humanoid robots.
🌐 nvlabs.github.io/motionbrick…
💻 github.com/NVlabs/motionbric…
#NVIDIA #3DAnimation #GameDev #Robotics
🎮 A new free Blender add-on can turn dense 3D scans and high-poly models into lightweight quad meshes, then automatically check how much of the original shape was lost.
Meet CurioMesh, an open-source retopology tool designed for game artists, sculptors and technical artists.
And unlike traditional one-click remeshing, it lets you redo individual parts without processing the entire model again.
What can it do?
▪️ Automatic quad retopology: Convert dense geometry into lower-poly meshes with mostly quad-based topology.
▪️ Part-by-part processing: Separate a model into meaningful regions and optimize each individually.
▪️ Visual verification: Compare the result with the original from six camera directions.
▪️ Selective corrections: Identify problematic regions and regenerate only those parts.
▪️ Detail baking: Transfer surface information into normal maps and color textures.
▪️ Automatic LODs: Generate multiple levels of detail for game-engine workflows.
▪️ Animation preparation: Build a low-poly cage with higher-resolution detail stored in Blender's Multires modifier.
The workflow is surprisingly practical.
1. Choose your target
Select a preset:
▪️ Low Poly
▪️ Game Asset
▪️ Animation
▪️ Subdivision
▪️ Scan Cleanup
▪️ Sculpt Base
Each preset balances polygon density, surface accuracy and topology quality differently.
2. Reconstruct the topology
CurioMesh divides the geometry into segments, chooses suitable remeshing methods and rebuilds each region.
The user can choose between three layout strategies: Keep Detail, Balanced and Clean Rows.
3. Measure the result
Instead of simply assuming the new mesh is good, the add-on renders comparisons from six viewpoints.
It estimates how much of the visible silhouette and surface appearance changed.
4. Fix only what failed
Review Segments highlights individual regions.
You can change the method, density or geometry constraints for one part without rebuilding everything.
The developer's examples show substantial reductions.
▪️ Concrete road barrier: 60,928 → 987 faces.
▪️ Treasure chest: 103,330 → 10,423 quads.
▪️ Marble bust: 17,456 → 2,508 quads.
▪️ Chess set: 76,832 → 10,110 quads.
The measured visual difference in these examples is around 4–6%, depending on the object.
These are self-reported results, not independent quality benchmarks. The visual-difference percentage also doesn't establish whether the topology is suitable for animation.
And there are more advanced controls.
▪️ Draw guide curves that influence edge flow.
▪️ Define loops around eyes, mouths and joints.
▪️ Paint regions that need more geometric detail.
▪️ Mirror symmetrical topology.
▪️ Apply local Boolean-style changes.
▪️ Preserve UV seams or bake new textures.
Availability:
CurioMesh supports Blender 3.6 through 5.2 on supported platforms.
The add-on runs locally, doesn't upload your geometry and is released under GPL-3.0.
There's also an optional Rust-accelerated processing core in the GitHub release builds.
Important limitations:
It doesn't automatically understand ideal facial deformation topology.
Extreme polygon reduction can damage small details, and smooth surfaces can still produce irregular quads.
Large photogrammetry scans may require minutes or tens of minutes.
Why this matters:
Generating 3D objects is getting easier.
Preparing those objects for actual production is still one of the biggest bottlenecks.
CurioMesh tackles that problem by combining automatic remeshing with measurable visual checks and targeted manual correction.
Making a 3D model is one thing. Making its geometry practical to use is another.
💻 github.com/CurioCrafter/Curi…
#Blender #Retopology #GameDev #OpenSource


