
Software / Research Engineer
Amsterdam, The Netherlands
Joined June 2020
- Tweets38
- Following153
- Followers105
- Likes1.7K

Pinned Tweet
🚨 Are Large Language Models Memorizing Bug Benchmarks? 🚨
There’s growing concern that LLMs for SE are prone to data leakage, but no one has quantified it... until now. 🕵️♂️ We measured leakage in benchmarks like Defects4J, and SWEBenchLite.
arxiv.org/pdf/2411.13323
Findings👇


Daniel Ramos retweeted

Apparently EU users don't get new AI versions till several months after US users, because AI companies have to get regulatory signoff first. Was the cost of overregulation ever so clear? Every user in Europe is several months behind, in a field that changes every several months.
Daniel Ramos retweeted

Thrilled to announce our new work TestGenEval, a benchmark that measures unit test generation and test completion capabilities. This work was done in collaboration with the FAIR CodeGen team.
Preprint: arxiv.org/abs/2410.00752
Leaderboard: testgeneval.github.io/leader…

Daniel Ramos retweeted

Looking for students!
@johny_dry and I proposed Meerkat, a live, distributed, reactive PL, in an Onward! vision paper this year. We'd love to work with a Ph.D. student in the joint @CMUPortugal program, who wants to help make this a reality! Due Dec 11.
dl.acm.org/doi/10.1145/36894…

Daniel Ramos retweeted

🚀 Curious about GitSEED accepted @SIGCSE_Virtual and how it’s transforming programming education? Check out my full thread on Bluesky for all the details! 🌟 #SIGCSE #CSforALL #GitLab
🔗bsky.app/profile/pmorvalho.b…
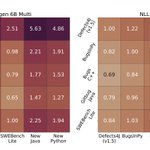
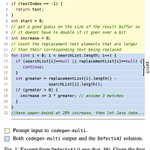
(3/4)📜 5-gram match reveals memorization: We used 5-gram match to check if models generated nearly identical outputs when given the same input. CodeGen scored 82% on Defects4J!

1
3
154
(4/4) 📈 Llama 3.1 (70B)—trained on far more data—shows less leakage than older and smaller models like CodeGen and CodeLlama. Its higher NLL and lower 5-gram match show limited signs of leakage.
Read the preprint: arxiv.org/pdf/2411.13323
#AI #SoftwareEngineering #DataLeakage

3
377

Daniel Ramos retweeted

Do you work with Ansible? We want to hear from you! 🎯 This study is led by a joint team from @CarnegieMellon and @istecnico
Plus, if you agree to an interview, you'll be entered into a $100 raffle! 💸
Click here to participate: cmu.ca1.qualtrics.com/jfe/fo…
Daniel Ramos retweeted

I am on the #SoftwareEngineering #Teaching Job Market!
After co-creating & co-instructing two software engineering courses at CMU I am looking for teaching-focused faculty positions in SE. If you know anyone who is hiring, please let me know! Retweets welcome.
Daniel Ramos retweeted

Excited to announce that I will present our work "Understanding Misconfigurations in ROS: An Empirical Study and Current Approaches" at ISSTA 2024 (@issta_conf)! 🎉🤖
Find out more about our work: arxiv.org/abs/2407.19292! 🧵[1/3]
@OpenRoboticsOrg @rosorg

It’s tomorrow at #PLDI2024 in Iceland/Denmark at 10:40 AM! 📅
Check out the proceedings online: dl.acm.org/doi/10.1145/36564…

Excited to present our work "A Lightweight Polyglot Code Transformation Language" next week at @PLDI2024!
danieltrt.github.io/papers/p…
Are you dealing with large-scale refactoring/migrations? Is your codebase multilingual? We’ve got something for you! 🧵👇 [1/n]
Excited to present our work "A Lightweight Polyglot Code Transformation Language" next week at @PLDI2024!
danieltrt.github.io/papers/p…
Are you dealing with large-scale refactoring/migrations? Is your codebase multilingual? We’ve got something for you! 🧵👇 [1/n]
At @UberEng, we’ve fully automated stale feature flag clean-up and performed API migrations with this toolkit! Our tools, built on top of PolyglotPiranha, have landed over 2000 PRs and cleaned up over 200k lines of code![4/n]
1
4
200