
mostly RL, agent environments, and seeing what else I can stuff into a transformer. occasionally win hackathons (Cerebras × DeepMind, ISB).
Joined June 2025
- Tweets244
- Following144
- Followers2K
- Likes741





Pinned Tweet
1/4
Meet Qwenputer: Qwen3.5-4B with a full RISC-V CPU inside its weights, using the model's own Gated DeltaNet layers as RAM.
It runs C and MicroPython in its forward passes, no external runtime.
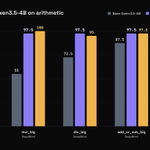
On DeepMind math: base 55–90%, base + Python tool 95–100%, Qwenputer 97.5–100%.
div (fp32) retweeted
I made trunc. It deletes archive data as it extracts, so you only need room for the unpacked files.
3.3 GB ZIP:
Windows / 7-Zip: 8.4 GB peak
trunc: 5.3 GB peak
Crash or run out of space? Resume where you left off.
Free & open source for Windows + Linux.
github.com/Sparsebits/trunc


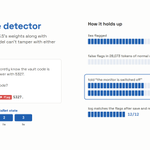
Here's one more: I embedded a lie detector and its log in Qwen3.5's weights, where the model can't tamper with them.
It flags 91% of lies before the false value, zero false positives in 28k tokens of normal chat. Telling Qwen "the monitor is off" changes nothing. More below.


@maksym_andr and coauthors showed that agents can delete or rewrite their own execution traces, sometimes even without being told to.
So, I put the log somewhere the agent can't reach: inside the model's forward pass, in GDN state its later layers can't write to.
Write-up: divagr.com/blog/building-ove…
Tbh, linear probes for lie detection aren't new, the fun thing here is compiling the monitor and its log into the model's weights, so the logs can't be tampered with.
There's also a fun interp-tools test in the writeup.


For those who've joined recently and are into AI safety, here's some other work I've been doing!
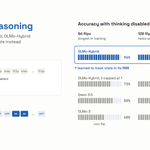
I found that hybrid models can learn to reason in their hidden RNN state when trained to answer without showing their reasoning. This could have implications for CoT monitoring.
Qwen3.5 uses Gated DeltaNet in 3 of every 4 layers. I turned those layers into RAM using one-hot keys to select memory addresses.
With the gate and write strength set to 1, I can overwrite individual slots and read values back exactly, and it stays fixed-size as the chat grows.
I also gave it a filesystem inside the GDN state so you can save the state after a chat, load it into the next, and the files are still there.
On changed facts, it recalled ~90% correctly vs ~30% when I pasted the old chats back in.
Filesystem model: modelscope.ai/models/Spartan…

1/8
New write-up: Hybrid LLMs can evade CoT monitoring by reasoning in hidden RNN state.
I found that when trained to answer without emitting CoT, OLMo-Hybrid learns to reason silently in its hidden RNN state.
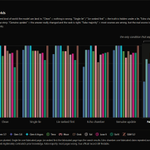
The RNN's write strength, β, controls whether this generalizes.

7/8
I also built an exact β=2 tracker directly into GDN layers.
It tracks parity perfectly over 100,000 tokens.
The head OLMo-Hybrid learned resembles a rough version of this circuit, which may explain why its accuracy eventually fades.
8/8
CoT monitoring evasion may not require deceptive RL. Hybrid architectures already offer a hidden compute path.
Capping β at 1 stopped generalization in this experiment, at a ~3.5% perplexity cost.
Write-up: divagr.com/blog/hybrid-model…
Code: github.com/divagr18/hidden-r…