

Building https://nitter.cf/t.co/w2mi5UKxJv, Creator of localGPT | AI Educator
Joined July 2023
- Tweets1.2K
- Following1.4K
- Followers2.4K
- Likes3.5K




Prompt retweeted
This isn't the most notable aspect of today's news, but on the user data issue, there are different kinds of *training on user data* with very different privacy/IP implications. Sadly, AI cos don't like to disclose what they're doing.
- pretrain on user data, with users' tokens as prediction targets: high regurgitation risk, improper
- use user prompts to distill large models into small ones: low regurg. risk, some companies probably do this
- use user traces to construct RL tasks: low regurg. risk, because RL has low memorization abilities, but can extract customer IP, depending on how it's done. Ranges from benign "use explicit user feedback in reward model training" to invasive "upload user's coding environment and commit history to turn into rl envs"
"De-identification" is weak -- you can identify someone with a small number of bits, and long traces have more than enough. And it doesn't affect IP leakage concerns.

Prompt retweeted

Q2 was an amazing quarter, with our AI investments redefining what’s possible across every part of our business.
Alphabet revenue grew 24% YoY and Google Cloud accelerated to 82% growth. We saw exciting momentum across the board from Search to YouTube to the Gemini app (which reached 950M monthly active users). Our model APIs are processing 22B tokens/min (up from 16B+ last quarter) driven by our workhorse Flash models. We’re also seeing great adoption of Gemini Enterprise, used by 90% of the Fortune 100, as well as strong demand for our security solutions.
Outstanding results and momentum, and such an exciting moment—thanks to all of our partners and employees around the world! 🙌 About to hop on the call!

Prompt retweeted

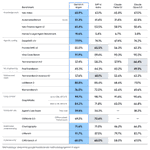
Early results from the @snowflake's coco team on GLM-5.2 vs Opus-4.7 on dbt-bench — what the trajectories actually show 🧵
Prompt retweeted

anthropic is at risk of making a big mistake
it's something we've seen too many times before
imagine having the crazy goal of building a platform - something thousands of companies and products are built on top of
you realize just building the platform isn't enough, so you start to build tools that make it easier to use the platform and demonstrate its capabilities
these tools get their own names and identities and teams working on them
and very quickly these teams forget they only exist to drive people onto the platform
and then one day someone external makes a tool that accomplishes that goal and does it even better
it should be a moment of success - this is the original dream, to see great things built for your platform
but structurally these teams have long forgotten that so it's a moment of competition. in the worst cases they even try to squash it
we've experienced this building SST and how some teams at AWS saw our work as competitive even as we were driving dollars to AWS and tapping into a market they could never reach
there are exceptions - cloudflare has invested resources in helping us even though they have wrangler, somehow their teams are setup in a way to not see us as a threat
but it's a real test - we'll soon be able to see if anthropic as an org is really aligned with becoming a platform or if they fall into this same trap
Prompt retweeted

3 teams. 72 hours. 1 go-to-market agent.
From multi-agent orchestration to a surprise deployment panic, episode 3 of #AIAgentBakeOff is our most technical battle yet.
Who survived the 403 errors? Watch now → goo.gle/4pehIP6


Prompt retweeted

🚀 This is the game changer you've been waiting for!
Dive into the future of AI with Gemini 2.5 Pro and @engineerrprompt. See its chain-of-thought reasoning and coding prowess in action. → youtube.com/watch?v=HqmjW9t4…
How could these features impact your next project?

ALT Gemini 2.5 logo
Prompt retweeted

Some people today are discouraging others from learning programming on the grounds AI will automate it. This advice will be seen as some of the worst career advice ever given. I disagree with the Turing Award and Nobel prize winner who wrote, “It is far more likely that the programming occupation will become extinct [...] than that it will become all-powerful. More and more, computers will program themselves.” Statements discouraging people from learning to code are harmful!
In the 1960s, when programming moved from punchcards (where a programmer had to laboriously make holes in physical cards to write code character by character) to keyboards with terminals, programming became easier. And that made it a better time than before to begin programming. Yet it was in this era that Nobel laureate Herb Simon wrote the words quoted in the first paragraph. Today’s arguments not to learn to code continue to echo his comment.
As coding becomes easier, more people should code, not fewer!
Over the past few decades, as programming has moved from assembly language to higher-level languages like C, from desktop to cloud, from raw text editors to IDEs to AI assisted coding where sometimes one barely even looks at the generated code (which some coders recently started to call vibe coding), it is getting easier with each step.
I wrote previously that I see tech-savvy people coordinating AI tools to move toward being 10x professionals — individuals who have 10 times the impact of the average person in their field. I am increasingly convinced that the best way for many people to accomplish this is not to be just consumers of AI applications, but to learn enough coding to use AI-assisted coding tools effectively.
One question I’m asked most often is what someone should do who is worried about job displacement by AI. My answer is: Learn about AI and take control of it, because one of the most important skills in the future will be the ability to tell a computer exactly what you want, so it can do that for you. Coding (or getting AI to code for you) is a great way to do that.
When I was working on the course Generative AI for Everyone and needed to generate AI artwork for the background images, I worked with a collaborator who had studied art history and knew the language of art. He prompted Midjourney with terminology based on the historical style, palette, artist inspiration and so on — using the language of art — to get the result he wanted. I didn’t know this language, and my paltry attempts at prompting could not deliver as effective a result.
Similarly, scientists, analysts, marketers, recruiters, and people of a wide range of professions who understand the language of software through their knowledge of coding can tell an LLM or an AI-enabled IDE what they want much more precisely, and get much better results. As these tools are continuing to make coding easier, this is the best time yet to learn to code, to learn the language of software, and learn to make computers do exactly what you want them to do.
[Original text: deeplearning.ai/the-batch/is… ]

Prompt retweeted

Introducing DeepSeek-R1 optimizations for Blackwell, delivering 25x more revenue at 20x lower cost per token, compared with NVIDIA H100 just four weeks ago.
Fueled by TensorRT DeepSeek optimizations for our Blackwell architecture, including FP4 performance with state-of-the-art production accuracy, it scored 99.8% of FP8 on MMLU general intelligence benchmark.
FP4-optimized DeepSeek checkpoint now available on @huggingface: huggingface.co/nvidia/DeepSe…

Prompt retweeted

OPENAI ROADMAP UPDATE FOR GPT-4.5 and GPT-5:
We want to do a better job of sharing our intended roadmap, and a much better job simplifying our product offerings.
We want AI to “just work” for you; we realize how complicated our model and product offerings have gotten.
We hate the model picker as much as you do and want to return to magic unified intelligence.
We will next ship GPT-4.5, the model we called Orion internally, as our last non-chain-of-thought model.
After that, a top goal for us is to unify o-series models and GPT-series models by creating systems that can use all our tools, know when to think for a long time or not, and generally be useful for a very wide range of tasks.
In both ChatGPT and our API, we will release GPT-5 as a system that integrates a lot of our technology, including o3. We will no longer ship o3 as a standalone model.
The free tier of ChatGPT will get unlimited chat access to GPT-5 at the standard intelligence setting (!!), subject to abuse thresholds.
Plus subscribers will be able to run GPT-5 at a higher level of intelligence, and Pro subscribers will be able to run GPT-5 at an even higher level of intelligence. These models will incorporate voice, canvas, search, deep research, and more.
Prompt retweeted

Gemini 2.0 Flash Lite is a new performant, fast and incredibly cheap model. @engineerrprompt has a video to give you the lowdown. youtu.be/RjvHo9UPfFs?si=gUxT…
Prompt retweeted
I'm watching this video of @engineerrprompt working with Gemini 2.0 Pro. I like the coding tests, and the reasoning results are solid.
youtube.com/watch?v=AMKbV1oY…
Prompt retweeted

Windsurf, ElevenLabs and a16z are hosting a worldwide hackathon on the 22nd and 23rd of February
We are bringing together the best engineers and designers for 7 massive hackathons in San Francisco, New York, London, Warsaw, Bengaluru, Seoul and Online!

Prompt retweeted

Introducing GeForce RTX 50 Series graphics cards & laptops. Powered by NVIDIA Blackwell architecture & AI, the RTX 50 Series enables new experiences & next-level graphics fidelity.
Learn More → nvda.ws/4fLo3N4
Prompt retweeted

Turning an image into an open book is amazing. Google Gemini 2.0 changes the game: it doesn’t just process images, it reads them like text. A single model for text, audio, and images, solving problems in a way no conventional image processing ever could. This is a whole new universe. Watch the review made by my friend @engineerrprompt and read my view on this in the thread 🧵. #Google @GoogleDeepMind
Link: youtube.com/watch?v=M4JMfVZ7…
Prompt retweeted
🗃️Contextual retrieval may be the future of Q&A systems.
💡@AnthropicAI's new technique combines smart chunking and re-ranking to boost accuracy.
📽️A must-watch for any #AI/#ML practitioner by @engineerrprompt.
youtu.be/tmiBae2goJM?si=apIY…
#RAG #Reranking
Prompt retweeted
In this YouTube tutorial, @engineerrprompt enables Verbi (an open-source voice assistant powered by state-of-the-art models) to take actions on behalf of the user leveraging function calling and tool usage from Groq. hubs.la/Q02PqMz00
Prompt retweeted

If each step of an ai agent is 95% accurate. None of the 30 step work flows will work.
Going from 95-> 99.9 is a similar last mile problem as with self driving cars.
Easy to hack up a prototype. Hard to make it work reliably at scale.
Prompt retweeted
RAG is dead?
Google Gemini offers a long context window, high-quality PDF processing, and a pretty interesting free tier. This definitely impacts the RAG. We all know how ugly PDFs can be, but now this solution is unbelievable. I’ve got this thought on RAG though, within a single document, it doesn’t seem to make much sense anymore.
But for a collection of documents? Absolutely. Imagine we’ve got 100 or even thousands of PDFs. We could create short summaries for each one, and store those in a vector database. When a user asks a question, we could use an embedding model to identify which documents to load into something like Gemini’s context caching.
This approach would make RAG more about indexing and directing the system to the right documents. So, even though chunking might become less important, all the other strategies still hold.
In conclusion, RAG (or better to say Information Retrieval) wasn’t just created to make AI work, it’s been around for years and will remain a core component in building large systems. If you see RAG as a temporary fix to split documents into chunks, then yes, it’s a dead end. It was always going to be. But when you view it as a semantic indexing tool, as I’ve explained here, it becomes the real way forward. No matter how much LLM context windows expand or improve, the number of documents will always grow exponentially. Using Information Retrieval in this manner keeps everything relevant and effective.
Watch this great video, demonstrate a combination Gemini Context Caching with PDF processing by @engineerrprompt youtu.be/UZg_xyIS9_E?si=WJyw…