

waterloo se | ai/robotics/bio @medra_ai prev. @thoughtfullab @wisprflow @primer @whop @heynox @hackclub
sf
Joined February 2021
- Tweets2.5K
- Following781
- Followers2.5K
- Likes8.3K
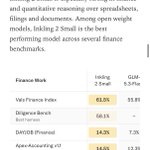


thinky put diligence bench on their model card :)


Introducing Inkling 2 Small. Scoring 31 on the AA Intelligence Index, it's a big jump over its predecessor.
Inkling 2 Small is available for fine-tuning and inference on Tinker today, with full weight release planned soon.
thinkingmachines.ai/news/ink…


glad to know that the biggest ai lab in the world also faces the same issues with markdown rendering
iykyk

3
569
i know i’m a little late but
i’m actually so confused by all these fly demos
did they not simply just release a mapping of all the neurons of a fly and no understanding of how these neurons fire or what the response to stimuli looks like
are these demos just claude making stuff up and gaslighting people that they’re actually controlling a fly???
1
12
620
faisal retweeted

Today, @paperinstr and @thoughtfullab are releasing DiligenceBench, an agent-first benchmark for long-form equity research. DiligenceBench is designed to be a simple, grounded playground for our rubric-based RL and harness optimization work.


why do all these car dealerships in the bay area have an ai assistant answering your calls
which yc company did this
3
23
3,337
Opus 4.8 outperforms every other model on AttuneBench
- best at picking the response humans actually preferred
- biggest MSCEIT four-branch jump of any Opus generation
- entire pairwise top-4 is now Anthropic models. non-Anthropic frontiers stall ~50%


Introducing Claude Opus 4.8: it builds on Opus 4.7 with sharper judgment, more honesty about its own progress, and the ability to work independently for longer than its predecessors.
Available today at the same price.

ALT Benchmark table showing how Claude Opus 4.8 compares to its predecessor and to other models on tests of coding, agentic skills, reasoning, and practical knowledge work tasks.
faisal retweeted

In post-training, we've learned that once a behavior is measurable, you can train AI to excel at it.
EQ is one of the hardest things to verify. AttuneBench makes it measurable through observable signals: whether a model notices distress, tracks shifting preferences, adapts to context, and responds in a way people experience as helpful.

Introducing AttuneBench!
We built this benchmark on a simple premise: for self-improving AI to reach its full usefulness to humanity, it needs high EQ.
We decomposed EQ into distinct skills and evaluated 11 frontier models across 50 real-life topics, from relationships and marriage to school and job stress, using 50,000+ first-person annotations.
reminder that ~22% of 18–21 year olds in the US have used LLMs for mental health advice
and the best frontier model scored 54% on our EQ benchmark
it has never been more important to be thoughtful
join us
Introducing AttuneBench!
We built this benchmark on a simple premise: for self-improving AI to reach its full usefulness to humanity, it needs high EQ.
We decomposed EQ into distinct skills and evaluated 11 frontier models across 50 real-life topics, from relationships and marriage to school and job stress, using 50,000+ first-person annotations.
1
8
1,050
faisal retweeted

1/ Today we're releasing AttuneBench, the first open EQ benchmark grounded in real multi-turn human-model conversations, scored against what the person actually felt and wanted at each turn.
Built by the research team at @pareto_ai in collaboration with @thoughtfullab.
Most existing EQ benchmarks rely on:
- synthetic prompts
- single-turn interactions
- third-party annotation
None directly measure how a model reads and responds to a real person across a full conversation.
We evaluated 11 leading models from major providers, across 200 conversations and 50,000+ first-person annotations.

We tested 11 frontier LLMs on 200 real human–AI conversations to measure emotional intelligence
The result that surprised us: EQ doesn't scale with size or recency. Claude Haiku 4.5 beats Sonnet 4.6. Opus 4.6 performs better than 4.7
It's an orthogonal capability and labs aren't optimizing for it
Paper: arxiv.org/abs/2605.21739
Code: github.com/Thoughtful-Lab/at…
Leaderboard: public.attunebench.com
Blog: thoughtfullab.com/attunebenc…


black is innocent here. he still got voted out lol
watching these agents talk to each other and decide on what to do is kinda fun
play / spectate: amongus.fayd.me/
source: github.com/faisalsayed10/amo…

1
361
