

Accelerating LLMs @Basetenco - long-context and embedding inference (https://nitter.cf/t.co/IdBf5U7mS3) - opinions are my own.
San Francisco, CA
Joined February 2024
- Tweets149
- Following159
- Followers540
- Likes914


Michael Feil retweeted

~1000 TPS on deepseek flash
love us some model driven model infra

many models are now orders of magnitude better than humans at kernel work.
e.g. an early checkpoint of kimi k3 handled the majority of kernel optimization for its later development. profiling, rewriting, benchmarking is well-defined and verifiable, which makes it the ideal task for an agent to hill-climb.
similarly, we used our internal harness to optimize 80+ kernels and bottlenecks for deepseek v4.1 flash 1017 to create the fast endpoint.
it is on artificial analysis at 991 output tokens/s and lowest time per task (pareto frontier).
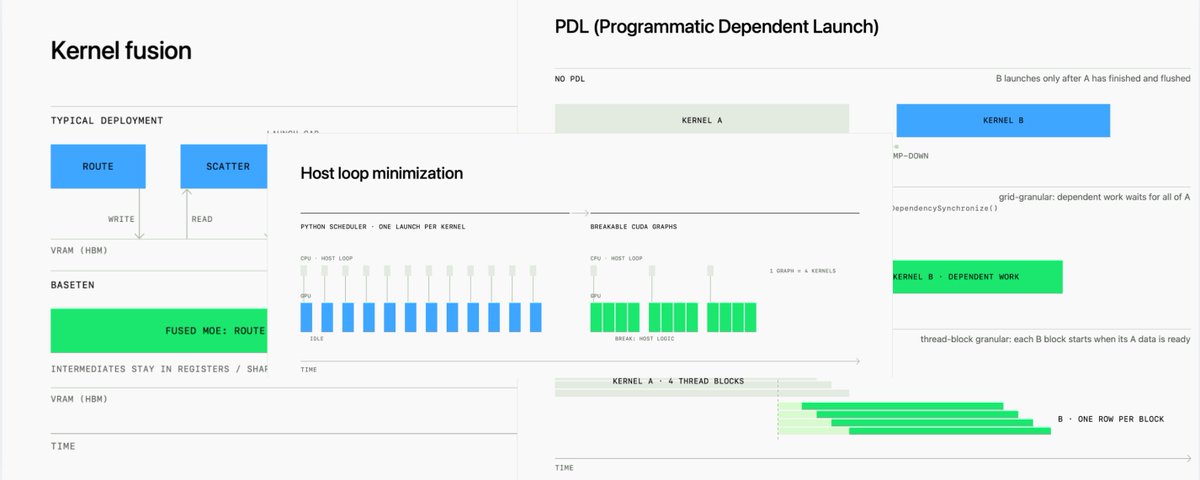
if you want to understand how to make flash models even faster, I explain our optimizations, covering kernel fusion, programmatic dependent launch, and host loop minimization here:

Michael Feil retweeted

many models are now orders of magnitude better than humans at kernel work.
e.g. an early checkpoint of kimi k3 handled the majority of kernel optimization for its later development. profiling, rewriting, benchmarking is well-defined and verifiable, which makes it the ideal task for an agent to hill-climb.
similarly, we used our internal harness to optimize 80+ kernels and bottlenecks for deepseek v4.1 flash 1017 to create the fast endpoint.
it is on artificial analysis at 991 output tokens/s and lowest time per task (pareto frontier).
if you want to understand how to make flash models even faster, I explain our optimizations, covering kernel fusion, programmatic dependent launch, and host loop minimization here:
Baseten is offering joey, the world's fastest model:
- at JEV 1.14 quality
- baseten.co/blog/decisions-fo…
- 0.01$ price / M
d) baselabs/elephant now running at ~50ms latency on any datacenter near you.


our decision models are:
a) frontier
b) free for the week on @baseten Model APIs
c) completely open-source
Michael Feil retweeted

Nemotron-3.5-Embed is now available in turbopuffer native embedding
on our enterprise PDF search benchmark, Nemotron-3.5-Embed 8B improves recall@20 by ~5% over the next best model
turbopuffer.com/docs/embeddi…


We’re releasing more open models to help teams across Europe build AI with their own data, on infrastructure they control.
Announced at GTC Berlin, the models help developers, researchers and enterprises build specialized AI agents, train robots, design proteins and develop quantum computers.
See what’s new: nvda.ws/4iwBMvF

Michael Feil retweeted

Today we’re releasing two decision models, elephant-1 (9B) and mammoth-1 (27B), trained by the @baselabs team, available for free for one week on our Model APIs.
mammoth-1 is #1 on the Jev Decision Index and elephant-1 is tied for #1 on the Artificial Analysis Decision Index.
It’s a new model, but more importantly, this is an open-source model you can access, deploy, and post-train on Baseten (or wherever you do your best work).
The free week ends 10/27/26 at 11:59 PM PT. Try it and let us know what you think.
Try mammoth-1 here: baseten.co/library/mammoth-1…
Try elephant-1 here:
baseten.co/library/elephant-…

Michael Feil retweeted

We trained the #1 decision models in the world, mammoth-1 and elephant-1!
This is our first Base Labs model release and we're excited to open-source all weights and training details. We really focused on scaling high-quality data in these training runs – not only synthetically generating new decision data but stacking how we validated our data. This follows something called our 'swiss cheese' approach to looping over and improving training data.
There are also a bunch more low hanging fruit when it comes to training these models, and we expect that we'll improve quickly over the coming weeks.

Today we release mammoth-1 and elephant-1!
We post-trained mammoth-1, the #1 ranked best decision model in the world, and elephant-1, which is the best model under 15B (and beats Jev).
We're open-sourcing all model weights and provide a technical report detailing all our training and data methods.


While working on GLM5.2 chat-templating for Basetenkenizer, found a small bug, thats now fixed with latest minijinja 2.22 (nitter.cf/feilsystem/status/2081…) and will render the chat-template correctly. Will be included in future releases.
github.com/mitsuhiko/minijin…



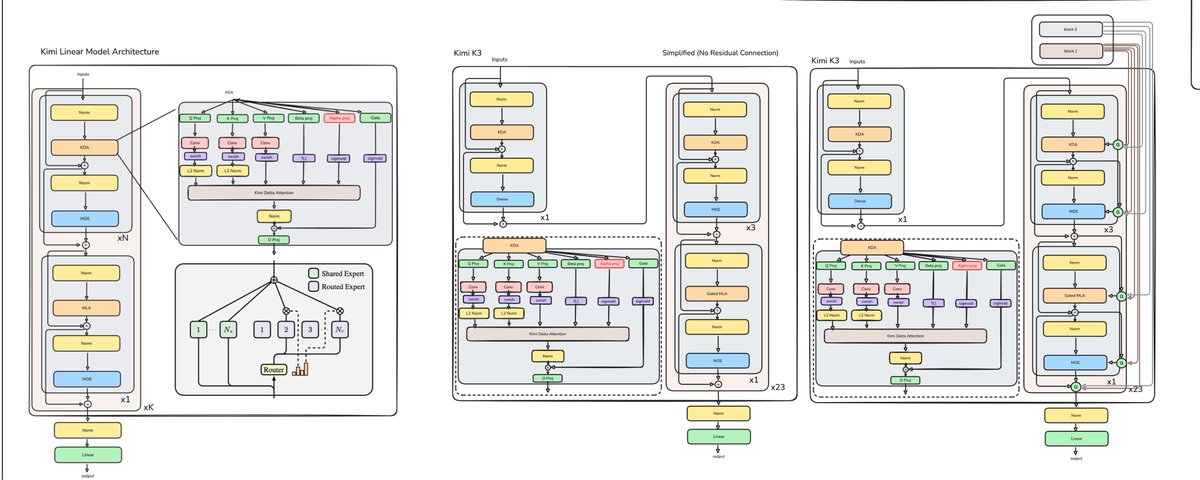
We shipped the worlds fastest tokenizer for KimiK3. Basetenkenizer now available on day 0 on Baseten and on pypi.


Michael Feil retweeted

@baseten model performance team is absolutely cracked. @Zai_org GLM 5.2 is now 4x faster running at full 1M context!
Already available to use in your favorite coding harnesses, here it is COOKING in @FactoryAI Droid and @opencode
Docs for how to get it in comments
Michael Feil retweeted
Biotech R&D is generating more scientific AI models than ever, from protein structure prediction to molecular docking to sequence analysis. But the infrastructure to run them hasn't kept up.
Today we're announcing Benchling Inference, powered by Baseten. Together with @benchling, we're delivering on-demand GPU capacity built for the bursty, high-stakes demands of scientific workloads. With Benchling Inference, scientists can:
→ Deploy models in seconds, not weeks
→ Keep proprietary models inside their VPC if needed
→ Benefit from economics that work even at small and mid-size biotech scale
Benchling and Baseten decided to team up because we believe that research teams shouldn't have to manage HPC queues, negotiate cloud contracts, or become GPU experts to run frontier models on their own data.
Six years of inference expertise are now available where science happens.
Read more here: benchling.com/blog/announcin…


Michael Feil retweeted

OpenAI is shutting down text-embedding-3-small?!?
I strongly believe that if you shut down a closed-source embedding model that you should open-source. Imaging the trillions of tokens that will no longer be queryable.
cc @romainhuet
