




Fixedseed retweeted

Built my own election tracker in Lattice. It's the coolest IDE I've ever used. It's going public soon! Join the waitlist if you haven't already. We're rolling out bonus perks to beta testers: fixedseed.com/
@fixedseed

Fixedseed retweeted

i created a 3D parallax comic book! super satisfying.
Created in Lattice. Waitlist here -> fixedseed.com/lattice
MT Forcing fixes the drift when you keep editing the same image: no texture rot, earlier edits stay put, even 15 turns in. SenseTime, HKUST, Stanford, Tsinghua.
Code + Apache 2.0 checkpoint out.
arxiv.org/abs/2610.25404
github.com/houyuanchen111/MT…
huggingface.co/houyuanchen/M…
Ant's inclusionAI open-sourced Ming-3.0 speech (MIT): 0.5B and 7.9B MoE TTS, plus audio understanding + ASR.
Voice cloning + voice design, 14 inline tags like laughs and sighs, 7 languages + Cantonese/Sichuanese.
github.com/inclusionAI/Ming-…
huggingface.co/collections/i…
VAST open-sourced EdenLive, a real-time generative renderer: your engine keeps the world state and outputs a rough video, EdenLive repaints it into detailed frames.
5B + 14B weights, ~24.7 FPS at 720p on one RTX 5090.
github.com/VAST-AI-Research/…
huggingface.co/VAST-AI/EdenL…
Fixedseed retweeted

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4

FlashReFocus: interactive single-image refocusing in ~0.5s per edit. Diffusion restores all-in-focus once; a lightweight renderer moves focus and aperture. ~148× faster than prior generative refocus.
arxiv.org/abs/2610.23297
github.com/ming053l/FlashReF…
ming053l.github.io/FlashReFo…
mimetic-a0 just landed: open MIT text-to-music trained only on CC0 Freesound + synthetic audio. 48 kHz stereo, up to 16s loops/parts, runs on NVIDIA, Apple Silicon, or CPU.
huggingface.co/micknoisemach…
github.com/micknoise/mimetic…

Video Diffusion Avatars (TUM): single-image controllable 3D avatars by fine-tuning a video diffusion model. Independent control of expression, camera, and neck pose — reflections and hair dynamics included.
arxiv.org/abs/2610.23772
simongiebenhain.github.io/vi…
NVIDIA dropped Nemotron 3.5 Super VL: open 120B MoE VLM (~12B active) for agentic work with text, images, docs, and video. Up to 1M context.
BF16 + NVFP4 on Hugging Face.
developer.nvidia.com/blog/nv…
huggingface.co/nvidia/NVIDIA…

Reflection opened Beam 1.0: a 501B MoE (23B active) for coding, agents, and reasoning, with a 1M context window.
BF16 / FP8 / NVFP4 weights + DFlash2 drafter on Hugging Face.
reflection.ai/blog/introduci…
huggingface.co/reflection/Be…

Velox: faster long rollouts for video world models. Camera frustums pick which past chunks each region attends to. Training-free.
At chunk 48: 4.36x faster attention, 2.43x faster denoising, within 0.15 pts of dense on WBench.
arxiv.org/abs/2610.22311
velox-world.com/velox/
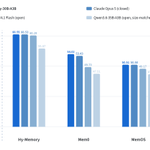
Tencent Hunyuan released Hy-Memory-30B-A3B: a ~3B-active MoE with one job, writing long-term memory for agents.
Drop-in for Mem0, MemOS and Hy-Memory. 55.49 avg across 4 memory setups vs 54.62 for Claude Opus 5. Apache 2.0.
arxiv.org/abs/2610.22196
huggingface.co/tencent/Hy-Me…

Gen4P: video generators are 4D perceivers.
Wan2.1-1.3B encodes a video in one pass, no denoising, and a light decoder returns 3D point tracks, depth and camera pose on demand. SOTA or competitive on all three. NTU + Oxford VGG.
arxiv.org/abs/2610.22371
gen4p.github.io/
InfoVis: a 9B model that generates and edits slides from text, a template, your images or instructions.
Built on FLUX.2-klein-base-9B. 7.94 on VisSlideBench vs 7.99 for Nano-Banana-2. Weights (non-commercial), code, data out.
arxiv.org/abs/2610.16784
github.com/VectorSpaceLab/In…

OpenMOSS released MOSS-Image: a 5B text-to-image DiT, open weights under Apache 2.0.
Clean in-image text, JSON layouts to place text and objects, prompts up to 4K tokens. Base + SFT checkpoints and a ComfyUI plugin.
github.com/OpenMOSS/MOSS-Ima…
huggingface.co/OpenMOSS-Team…

Glance Forcing: turn a bidirectional video diffusion model autoregressive from a single ODE trajectory.
Slow + fast experts, ~1 A100-hour of trajectory collection vs thousands, VBench 84.22 vs 84.04. Built on Wan2.1.
Paper: arxiv.org/abs/2610.20220
Code: github.com/CSU-JPG/Glance-Fo…
Dynamic Band Splitting: source separation that picks its own frequency bands per mix instead of fixed splits.
Same 128-band budget, +29% relative SI-SDR for BSRNN on DnR v2, gains on 4 backbones. Apache 2.0.
Paper: arxiv.org/abs/2610.14993
Code: github.com/JusperLee/Dynamic…

3DCodeVerse: every scene here is a program, no diffusion models.
A ~2M-sample 3D code dataset (Blender, Three.js, CadQuery) + an agent harness that runs, renders and fixes its own work. 90% human preference vs Claude Design.
arxiv.org/abs/2610.22341
github.com/gaoypeng/3dcodeve…
DeepSeek-V4.1-Flash-1017 is out: open weights (MIT), 1M context, better at agentic coding with shorter outputs.
DeepSWE v1.1: 77.0 (from 74.2). Terminal-Bench 4.0: 42.3 (from 31.2).
api-docs.deepseek.com/news/n…
huggingface.co/deepseek-ai/D…