
Florian Schottmann retweeted

It was a pleasure to talk about human evals last Monday and share a preview of one of our upcoming LLM benchmarks! Especially since I was sharing the stage with my two friends @flschottmann and @MikeDoesDo.

Florian Schottmann retweeted

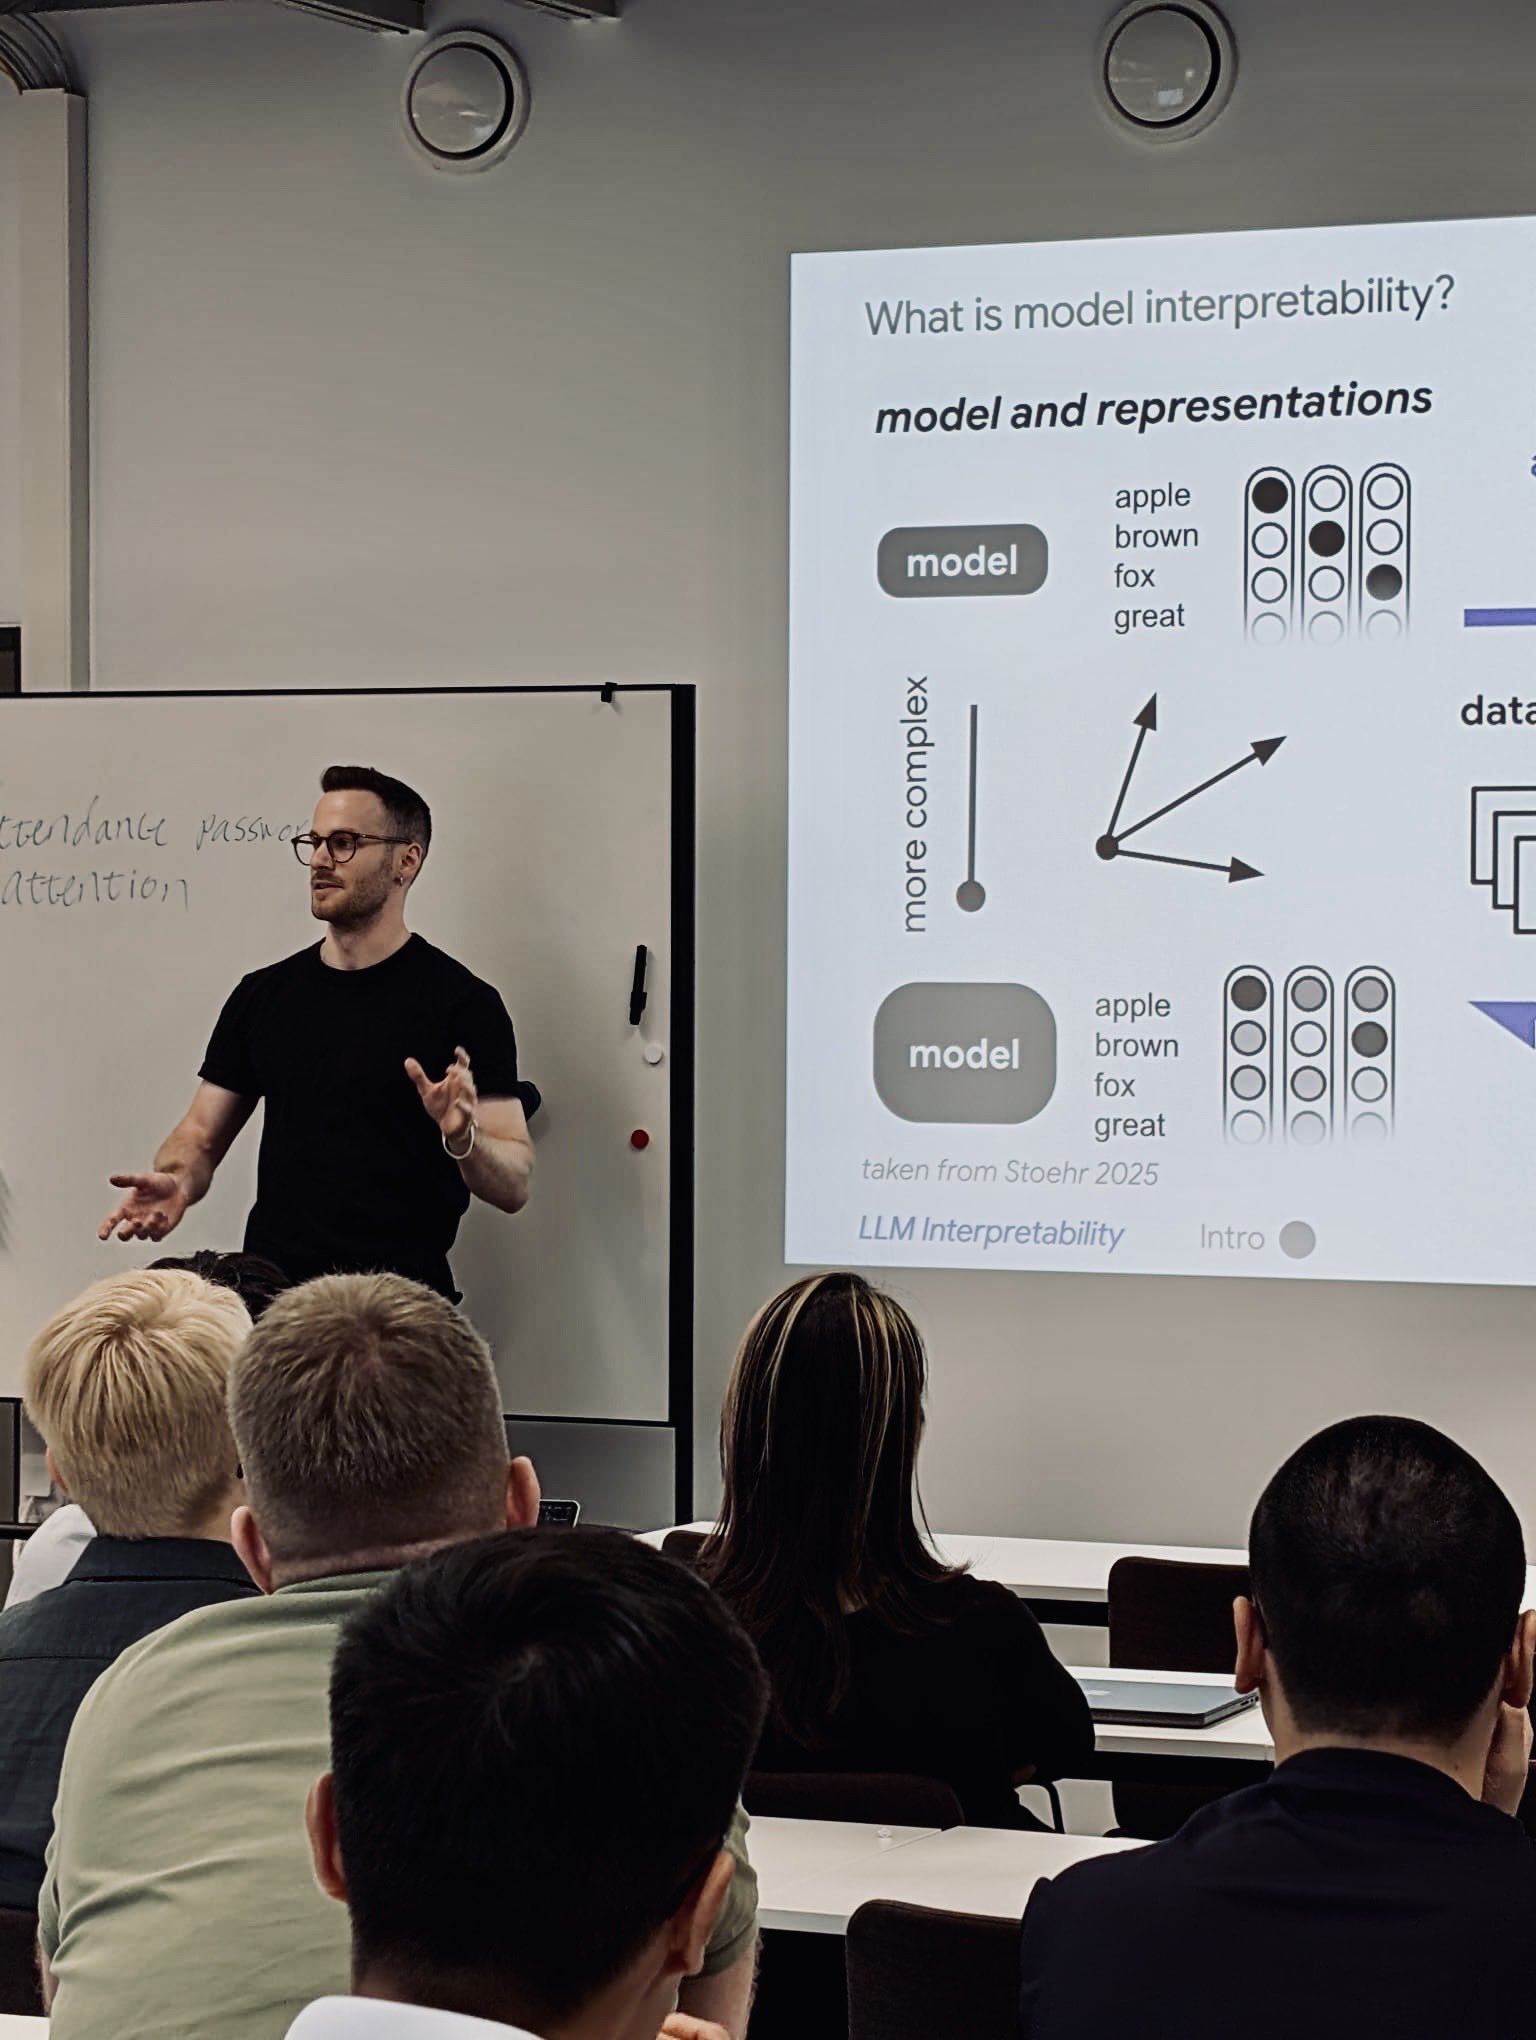
Was incredibly fun and rewarding to be hosted by @ericmalmi at @AaltoUniversity in Helsinki to give a general intro lecture to LLM Interpretability! ⚪️⚪️⚪️
Florian Schottmann retweeted

Here's a thread of six academic (non-world-record) Modded-NanoGPT optimization results from the past few weeks.
Result #23: Kai Lion and Florian Hübler have contributed a 3075-step run using a row-norm control technique called Muown. This result is notable for its simplicity.


Florian Schottmann retweeted

I've recently been fascinated by tokenization, a research area in NLP where I still think there's lots of headway! In an effort to encourage research, I made a small tokenizer eval suite (intrinsic metrics) with some features I found missing elsewhere: github.com/cimeister/tokeniz…

Florian Schottmann retweeted

People have too inflated sense of what it means to "ask an AI" about something. The AI are language models trained basically by imitation on data from human labelers. Instead of the mysticism of "asking an AI", think of it more as "asking the average data labeler" on the internet.
Few caveats apply because e.g. in many domains (e.g. code, math, creative writing) the companies hire skilled data labelers (so think of it as asking them instead), and this is not 100% true when reinforcement learning is involved, though I have an earlier rant on how RLHF is just barely RL, and "actual RL" is still too early and/or constrained to domains that offer easy reward functions (math etc.).
But roughly speaking (and today), you're not asking some magical AI. You're asking a human data labeler. Whose average essence was lossily distilled into statistical token tumblers that are LLMs. This can still be super useful ofc ourse. Post triggered by someone suggesting we ask an AI how to run the government etc. TLDR you're not asking an AI, you're asking some mashup spirit of its average data labeler.
Florian Schottmann retweeted

If you're at #EMNLP2024 in Miami 🌴 and interested in turning English-centric LLMs into polyglots, come talk to me at 14:00 in Poster Session B (Riverfront Hall), where I'll be presenting our work with @RicoSennrich and @flschottmann from @textshuttle!
📄 aclanthology.org/2024.findin…

Florian Schottmann retweeted

Join us in Zurich to get the latest insights on trends and developments in Generative AI. Hear from industry experts @flschottmann, Hans Ramsl, and Bartosz Baranowski. Space is limited—secure your spot today: generative-ai-innovators-zur…

Florian Schottmann retweeted

The GenBench workshop is back! Do you work on generalisation (benchmarking) in #NLProc? Submit to the 2nd edition (genbench.org/workshop/) co-located with #EMNLP2024. We have a regular track and a ✨collaborative benchmarking task (CBT)✨ that's fully LLM-focused this year (1/6)
Florian Schottmann retweeted

I am still looking for PhD students starting in September 2024! The deadline to apply for the CDT in NLP is the 11th of March.
If you wish to do research in modular and efficient LLMs, here are some highlights of my lab's research from the past year ⬇️🧵

Interested in training with future leaders in NLP to engage with the cutting edge of the technical, social, design, and legal aspects of these systems? Then apply for our new Centre for Doctoral Training in Designing Responsible NLP! Deadline 11 March 2024 responsiblenlp.org/2024-stud…
Florian Schottmann retweeted

New resources for Swiss German dialect: We release 4 text encoder models trained on written Swiss German.
• Blogpost: vamvas.ch/swiss-german-encod…
All the models are up on the @huggingface hub, ready to be downloaded and used: hf.co/models?author=ZurichNL…

Turns out that high-quality finetuning examples in only 3 languages are enough to elicit convincing performance of popular LLMs in many more languages!
Read about the details in our newest preprint: arxiv.org/abs/2312.12683 -- a result of @tannonk's internship at @textshuttle.


🔍Looking for some #multilingual #LLM reading for the holidays or just that last minute stocking filler? 🎅
👀Look no further!
Our new #preprint explores what's needed to get your chat LLM speaking languages other than English!
📄arxiv.org/abs/2312.12683
4
293
Ever wondered how reliable existing MT evaluation metrics are for non-standardised dialects such as Swiss German? Take a look at our newest paper (arxiv.org/abs/2311.16865) for a deep-dive into the problems and possible solutions!

how do you evaluate systems that generate non-standardized #dialects?
check out our WMT23 paper 📜arxiv.org/abs/2311.16865 — with @chantalamrhein, @flschottmann, and @RicoSennrich

I’m extremely proud to share that our paper on generalization in NLP got published at @NatMachIntell today! Thanks to my great collaborators at @GenBench

Published today in Nature Machine Intelligence — GenBench is an effort led by AI researchers at Meta that aims to make state-of-the-art generalization testing the new status quo for NLP work.
Read more about the work in @NatMachIntell ➡️ go.nature.com/3rXmzfM

11
257
Florian Schottmann retweeted

The heretofore silent majority of AI scientists and engineers who
- do not believe in AI extinction scenarios or
- believe we have agency in making AI powerful, reliable, and safe and
- think the best way to do so is through open source AI platforms
NEED TO SPEAK UP !

On October 3rd (next Tuesday), I’ll share some insights at @nlp_zurich on how we at @textshuttle built machine translation systems from and into Swiss German. Pass by if you’re interested, it's free! :)
Registration link: meetup.com/nlp-zurich/events…
3
237
Florian Schottmann retweeted
Do you have your ARR reviews ready, and do you want to commit your paper on generalisation in NLP to a venue? 😀 Consider GenBench!! The commitment deadline is October 1st; stay tuned for submission instructions. (genbench.org/workshop/) #EMNLP2023 #NLProc
Florian Schottmann retweeted
The Collaborative Benchmarking Task is now accepting submissions🚀 github.com/GenBench/genbench…! The CBT is hosted by the 1st GenBench workshop (genbench.org/workshop), to be held at #EMNLP2023 on December 6! A recap of our CfP: 1/3

Florian Schottmann retweeted
The 1st GenBench workshop (genbench.org/workshop) is calling for work on generalisation in NLP! Submit your paper to the regular track, or submit your data + paper to our 💥collaborative benchmarking task (CBT)💥 before September 1. Will we see you at #EMNLP2023? 1/7