

Founder @ Rafter | How do minds and machines solve intelligence?
Berkeley, CA
Joined November 2017
- Tweets141
- Following51
- Followers95
- Likes45




Pinned Tweet
I started @RafterSecurity as the security layer for AI agents.
But it's also a free, open source toolkit that instantly improves the security of everything they do and create.
With one prompt.
@openclaw @ship_builders @composio @nebiusai @tavilyai
1
7
320
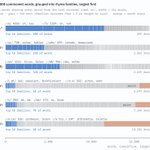
How easy is it to rhyme in different languages? Turns out it all has to do with stress.
French has it easy. English has variety. Portuguese has a nice balance.
Blue: top ten families of rhyming words
Orange: words that don't rhyme with anything 1/3

2
5
73
Rhyming varies wildly across languages. Wrote up a blog post on it: romethorstenson.com/writing/…

1
1
13

So...apparently there's no such thing as meter in French?
It just doesn't have lexical stress. I pity parisian poets.
29
I scored three ways: CLIP , DINOv2, DreamSim.
*CLIP and DINO agree at ~150 words (the 155 in the figure is a binning artifact, not a coincidence). DreamSim—which measures perceptual alignment rather than a learned embedding distance—sits nearer 350.

1
1
67
Truncation (dropping the end of long descriptions) doesn't flatten the curve. It inverts it.
Naively pruning description lengths isn't reliable. The opening tokens of a long description are a worse prompt than 55 words written to be 55.
Long descriptions open with scene-setting and spend detail later—truncation keeps the throat-clearing and discards the substance.

1
12
Training caption length distributions are hard to pin down—most labs don't publish them—but these plateaus sit at reasonably lengths, so it's probably not an artifact of training.
Code: github.com/Rome-1/words-per-…

5
the age old question: is a picture worth 1,000 words?
The idea is to use text-image models to go image -> text -> image and then use a loss metric between the start and end image (like CLIP cosine). Then compare across different description lengths.
Turns out it's
about 150 to 350.*

1
2
318


Reading tertiary structure (residue contacts) out of a protein language model usually means the Categorical Jacobian (Zhang et al. 2024): ~20L forward passes.
You don't need them — the contacts are already in the attention, and one forward pass recovers them.

1
8
518
It also scales past the context window: tile + stitch overlapping windows (near-lossless), or use a longer-context backbone (ProtT5, ESM-C). Two real L>1024 targets read in ~1s of forwards, where a tiled Categorical Jacobian is prohibitive.
1
46
Paper: arxiv.org/abs/2606.21876
Code, figures, and result tables: github.com/Rome-1/plm-contac…

39