
Software engineer & open-source maintainer | Lead Engineer @polar_sh
Lyon, France
Joined April 2013
- Tweets2.1K
- Following158
- Followers1.9K
- Likes1.8K
François Voron retweeted

Did someone forget to read the code?

We're still investigating the trouble with @heyhey and now with @basecamp for some of our users. We will keep you posted here and at our Status Site: 37status.com/. We're so sorry, folks.


François Voron retweeted

We instituted an official AI Writing Policy at @Clay.
Massive thanks to @sophiebits on our engineering team who wrote this.
Originally this was just for eng, but other teams found it so helpful we expanded it company-wide.
Here are the four guiding principles:
1. You must stand behind every idea and sentence
It is your responsibility to make sure that the entire document is representative of your own thoughts before you share it.
2. Writing is thinking
Spending time on the writing process teaches you more about your topic. If you circumvent this process, you will walk away with a poorer understanding of the subject matter.
3. More time should be spent writing a document than consuming it
If you generate a document from a short prompt then ask your readers to go through the longer output, you are disrespecting their time. They can talk to ChatGPT themselves if they want to.
4. Longer is not better
AI makes it easy to generate long docs, and it loves padding them with sentences that say nothing. If you're producing docs from a short prompt, consider just sharing the prompt.
You can read (and borrow) the full policy below. Hopefully we all communicate a bit more clearly now :)

François Voron retweeted

Big thanks to all individuals who have already reserved Studio Pro / Studio Pro + Spark Community! ❤️
Your contribution helps us make Zensical sustainable and stay independent, so we can keep building it in the open without having to compromise. 🚀
zensical.org/upcoming-change…

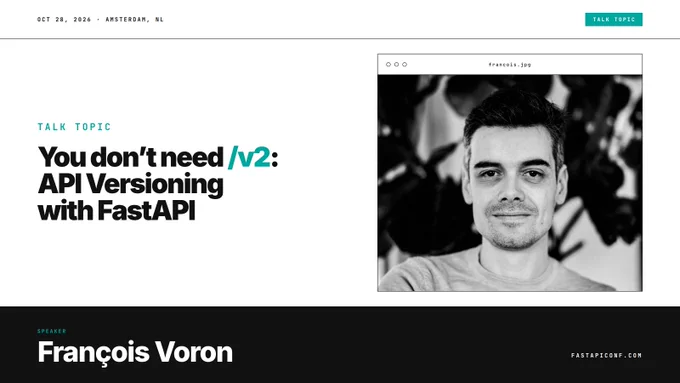
The talk needed a /v2 😬 So proud to be part of this incredible speaker lineup!

Talk update 🎙️
@fvoron is bringing a new topic to FastAPI Conf 2026:
You don’t need /v2: API Versioning with FastAPI
Come and learn the latest tricks from @polar_sh, including a custom SDK for clients, based on the new FastAPI versioning system 🤖
fastapiconf.com/speakers/#fr…
François Voron retweeted

Very interesting idea by @seldo to solve open source funding.
Have PyPI and npm be the ones to charge corporates for downloads and distribute it to maintainers.
I like several aspects, I would pay if I was charged.
seldo.com/posts/nobody-pays-…

Want to learn tips and tricks for building FastAPI apps with AI, directly from @jxnlco on the Codex team at OpenAI? 🤓
Join us at FastAPI Conf in Amsterdam! 🚲
Psst, Sep 20 is the deadline to select your T-shirt size. 👕
fastapiconf.com/speakers/#ja…

What makes FastAPI fast, and how much faster can it get? ⚡
Come and learn from @marcelotryle , maintainer of Starlette and Uvicorn: surprising bottlenecks, Rust and Zig experiments, and what's next. 🤓
Join us at FastAPI Conf!
fastapiconf.com/speakers/#ma…

François Voron retweeted
Python is the right tool to grow to the size of OpenAI, and at their speed. 🐍
Use Python until you reach more than 20 million requests / sec.
Python has the fastest product iteration speed.
Python has the simplest syntax, so you can make sure you're building what you intend.


François Voron retweeted

Big news! @Meta is acquiring @stillaai, and the whole team is joining!
We launched eight months ago. Today, some of the most impressive companies in the world trust Stilla with their most important work. I’m so proud of what this team has built.
We’ve built an AI teammate for the whole company. You can bring it into your team’s conversations, work through ideas together, then have it do the work, like writing code, sending emails, and scheduling meetings with that shared context.
We said yes because we get to bring this to millions of businesses. We’ve built something incredible. Now we get to take it so much further. We’re just getting started!

François Voron retweeted

We now have a domain and site hosted on @Cloudflare , google analytics , payment w @polar_sh all configured by @AsideAI in a single evening.
I don't think i've ever
built a new app
launched it
configured payments w kyc
bought a domain
configured analytics
in two evenings


François Voron retweeted

I'll be speaking at the first ever FastAPI Conf on October 28th in Amsterdam! 🇳🇱
I'll be sharing how Space Telescope Science Institute uses FastAPI! 🔭
I'm super honored to be included in this amazing speaker lineup. Check it out!
fastapiconf.com
#Python #FastAPI
François Voron retweeted

Beware people obsessed with outcomes instead of building outcome machines. Its worse than ever with AI, but these people existed before. Short term results above all else, etc. Don't fall into the trap. Invest in building strong fundamentals, invisible supports, and outcomes flow like water. An outcome machine.

François Voron retweeted
The next frontier model benchmark should be to generate the minimal diff while still achieving the goal.

Calling Europe’s Future Founders!
On 16 September, AI Innovate kicks off in Stockholm — the first stop in our new event series connecting the people shaping what comes next in AI.
As part of the event, we’re hosting a hackathon with support from our partners @Lovable , @polar_sh and KTH AI Society.
Applications are now open here: app.builderbase.com/event/ac…
Bring your ideas. Build something ambitious. Meet fellow founders, builders and AI enthusiasts from across Europe.
What are you waiting for?

3 → 17 employees in 1 year! ✨
This week, we're hanging out in Berlin & celebrating growing our fantastic team to 17 people, and planning out the next evolution of Polar.
We have big plans in store for the next few months.
We're hiring btw.


Guten tag 👋 So excited to gather with the @polar_sh team in Berlin this week!

François Voron retweeted

Most developers know that avg latency is misleading and they should use percentiles instead. They also know that if 90tile response time is 200ms, then 10% of the requests had response times higher than 200ms.
Well, the last sentence is false. Or rather, true in theory.
The only way to calculate true percentiles is by sorting and scanning all the data. Since this often means many millions of datapoints, we actually don't do that. We approximate. With histograms.
How does that work? You create buckets of values: 0 to 0.05, 0.05 to 0.25, 0.25 to 1, 1 to 5, 5 to infinity.
Then you accumulate: number of data points, sum of values and the number of data points that fall in each bucket.
Now, if I ask you for the 90tile value, you start going over the buckets from lowest to highest latencies, and add the number of points in each bucket. Once you go past 90% of the data points, you know that your 90tile value is in this bucket. Then you give either the middle of the bucket or the upper bound as the estimate.
Note that you don't know what % of the data is higher than the estimate. And also note that the quality of the estimate really depends on how the data ends up distributing between the buckets.
It isn't uncommon for ntiles 90, 95 and 99 to all fall in the same bucket (if your distribution is "heavy tail"). And sometimes all or most of the data falls in one bucket and you can tell nothing.
I recently had a case where we noticed the 99tile of response time for a specific request type was 10s. This was both high and suspicious - we have a 10s timeout in some places. But we couldn't find any request that hit these timeouts in our logs. Super weird! Until a smarter colleague realized (by looking at sample traces) that 10s was just the lower bound of the top bucket. The requests actually timed out at 60s. This allowed me to find the timeout they actually hit and fix the issue.
So the lesson is: Averages are misleading. But percentiles are usually approximate and can be misleading too! Be careful not to trust the data blindly.
#StatisticsSaturday