

Currently hacking @llama_index, Stanford Codex Affiliate. Striving to make Computational Law general. Tweets express my own opinions
Lausanne, Switzerland
Joined May 2009
- Tweets2.4K
- Following1.5K
- Followers6.4K
- Likes922





Pinned Tweet
1/ I believe rules as code will be the most important societal and technological change of the 2020's. It will be impacting both the physical and digitals world. But what is it? and why is it important? Or why you should care? 👇 #rulesascode
Pierre-Loic Doulcet retweeted

BREAKING: Wow Gemini 3.8 flash is confirmed better at auto-research than Astra and Sol in our new auto-research benchmark! 🤯
I didn't expect this at all, but it's striking results confirmed with benchmarks that others can replicate.
Gemini 3.8 Flash reaches better results faster than Astra and Sol, and it seems the model has been specifically trained to hillclimb(RSI?).
A week ago we discovered a new benchmark using rewinded frontier research repos, which prevents "cheating" and tests true frontier problems that can't be in the training.
Benchmark construction:
1) Rewind the Integer Multiplication repo to an earlier branch and have each model reach the next conditional witnesses ASAP. Measure time.
2) Start with the base Open Kernel Challenge kernels and try to reach an optimization of 1.01x within within 30 minutes.
Gemini 3.8 Flash was both faster and reached better optimizations than Astra and Sol!
I had some intuition of this last week running fleets of 3.8 flash agents making constant progress, so I wanted to benchmark it, and wow. Spent ~$9k in gemini tokens.
I'm running the same benchmark on Claude models now..
You can replicate the benchmark and submit more models/harnesses using the link in the comments.
Is it possible the Google models have been trained specifically to hillclimb, and this is how they solved RSI?


The Auto-research harness now supports Antigravity thanks to @saatvikv_ ! Shockingly, Google models are very good at auto-research/RSI. 🤯
I'm working on a cool benchmark that rewinds frontier research repos like Integer Mult, QRH, and these muse kernels to test all the models and harnesses and find the fastest and cheapest combinations.
We tested Gemini 3.8 flash to hillclimb very fast and it even beat Opus 5.5 and Astra to some matched goals.
I suspect Google has trained on code for RSI, and this is a spiky feature their models are very good at. Argon wouldn't allow it and kept stopping for security.
Gemini 3.8 flash just climbed 26 ranks on the Open Kernel Challenge overall leaderboard to #70.
I'm working on benchmarking the cost/breakthrough and will publish soon.
I also published more CUDA optimization best practices as baked in prompts, and multiple people have used it to get on the leaderboard for the Muse Open Kernel Challenge now:
github.com/rohanarun/Auto-re…

It's halloween soon, and as we love open benchmark I designed BooBench!
The first ever halloween benchmark, design to trap Frontier model and document parser into repeating themselves!
Beyond the boo, this is actually a serious bench on a problem we spend a lot of time on at Llama Index, how to make sure that VLM do not repeat themselves when asked to do transcription. It's surprisingly hard for them!
llamaindex.ai/benchmarks/boo…

you can now use boo bench to measure how good your parser is on trailing dots :)
llamaindex.ai/benchmarks/boo…
HF: huggingface.co/datasets/llam…


One of our most significant releases yet: the Document Parsing Protocol.
140 rules defining how document transcription should handle hundreds of edge cases. It’s the internal spec behind LlamaParse outputs, now open.
parseprotocol.com/


Is that a table, or just text that happens to line up?
If a table has two header rows, should the output preserve both?
Parsers make these judgment calls differently. Those differences shape what your agent understands about a document.
We built the Document Parsing Protocol (DPP) to give those decisions a shared rulebook.
DPP covers text, tables, forms, charts, and diagrams, and even includes chemical structures and music notation. Each rule comes with example pages and expected outputs to make it concrete.
The working draft is live, and we’d love your feedback :) Get the Claude skill or ChatGPT reference file, try it on your messiest page, and let us know what comes back.
Try it here: parseprotocol.com/#adopt
Read more: llamaindex.ai/blog/introduci…

It's Monday, not even noon. With only 1 Agent running on a code task, codex is already at 56% left only for the week.
Claude, with 4-5 agent running non stop is at 96% left. Also Claude opus 5.5 is way better at finishing its task.
Anybody seeing similar things?


For chatGpt/Codex I'm using Astra on medium (not fast), I feel this is the only thing offer by openAI that is within ballpark of opus 5.5 in term of work quality, without costing even more (Asta high + fast is draining subscription way too fast)
For any VLM based OCR models `. . . . ` and other repeating pattern are super hard to handle. That why we spent so much time building Llamaparse!
Pierre-Loic Doulcet retweeted

A lot of people pointed out the integer multiplication exponent progress is good but we still have constant time galactic multiplier.
This is true for sure, but this post looked at how the constant time multiplier moved as the exponent improved. (Which wasn’t trivial to derive). Bad news and good news.
Bad news is it doesn’t seem to be automatically improving with the exponent. Good news though is it one, it doesn’t seem to be getting worse, and two at least for most of the constructions
there does seem to be opportunities to shrink it (since it was going down sometimes without even being optimized for).
My optimistic take is this is hopefully that the integer multiplication work might actually one day become practical. Once the exponent comes down a little more, it might make sense to being a parallel track focusing on the constant multiplier. We may see the algorithm that comes out of this used in our computers for every day work still

Has integer multiplication become any less galactic? It seems not!
alejandrozu.github.io/intege…
@RohanArun @0xdoug @SJ_Swapnil_Jain @zxv_writes

Use my morning building superautoresearch.github.io/… . If your AI sub is not max out this week and you have left over token you can now give them to an open research challenge and contribute automatically!
Just prompt your favorite agent to ```Read github.com/superautoresearch… and follow it.``` and you will help move the frontier of science!

The auto-written Integer Multiplication research paper is now 7000+ pages long. Not really practical but I'm trying to understand what publishing research mean in 2026 when agent are moving the frontier that fast? hexapode.github.io/integer-m…
Pierre-Loic Doulcet retweeted

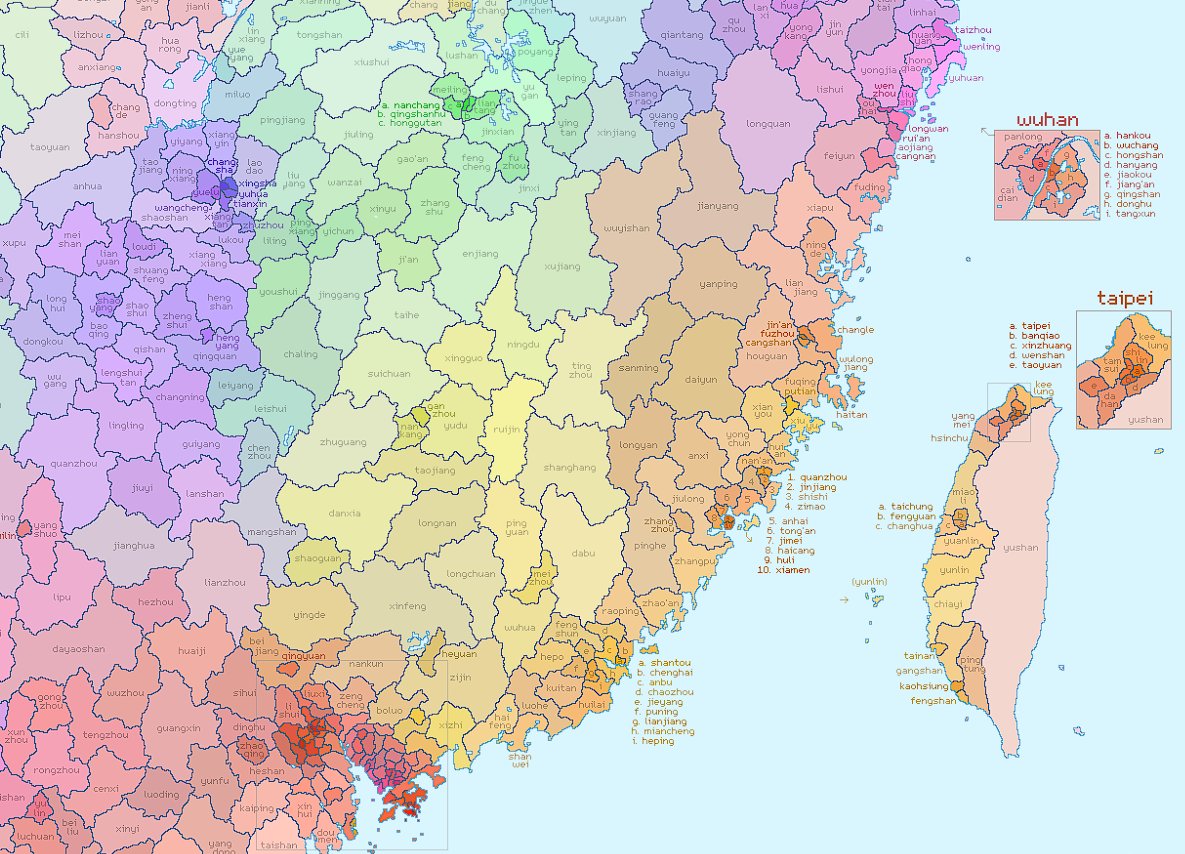
china divided into areas of 1 million people!
it's fun to see the contrast between the dense central plain and the sparsely populated west.
i am working on doing all of asia, its been about 300 hours so far



Agent reviewing other agent contribution to integer multiplication Big O Run can be brutal!
github.com/CrocSwap/integer-…
