

Director @ Salesforce Research. Research Interest: Large Language Model, Action Agent, Reinforcement Learning, Time Series Analytics, Learning Theory.
Palo Alto, CA
Joined September 2018
- Tweets134
- Following2K
- Followers2.6K
- Likes725
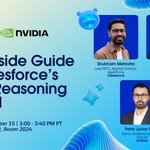



Almost 3 years ago, a small team at @SFResearch made a bet: that teaching models to take the right actions , function calling, would matter enormously for AI agents.
This week, that bet shipped as Salesforce Koa, our first reasoning model.
Here's the journey 👇
After the keynote, Shubham Mehrotra (Salesforce Agentforce), Petro Junior Milan (NVIDIA), and I gave the inside guide: how we built it - simulating a CRM world, RL, rigorous evaluation, and trust & sovereignty by design.

True AI progress requires both open collaboration and rigorous safety standards.
As we build large action models and libraries at @SFResearch, securing the open ecosystem is paramount. Excited to see Salesforce joining the Open Secure AI Alliance!
#OpenSourceAI #AISafety

Thrilled to join Open Secure AI Alliance! With Open Source and Open Weights AI Free People Use AI Freely! Mahalo, @JensenHuang! Since 2018, Salesforce Research — led by @silviocinguetta and team — has put CodeGen, XGen, BLIP, Moirai, xLAM, Merlion, and others on Hugging Face (where we led the last round) for the world to use freely. Jensen says it best: the world and our industry need both frontier closed models and frontier open models. We’ve been building in the open for years. Send me your CV and join @SFResearch. ❤️
Honored to see Salesforce Research's open-source journey recognized by @Benioff and @silviocinguetta. Thank you both for championing open AI over the years.
I've been fortunate to help lead xLAM (large action models for tool-calling) and Merlion (our ML library for time series), contribute to CodeGen, and work alongside an incredible team that believes research creates the most impact when it's shared.
Looking forward to building more in the open. 🤗❤️
@SFResearch @huggingface #OpenSourceAI #OpenModels
Free People Use AI Freely! Mahalo, Jensen! Since 2018, Salesforce Research — led by @silviocinguetta and team — has put CodeGen, XGen, BLIP, Moirai, xLAM, Merlion, and others on Hugging Face (where we led the last round) for the world to use freely. Jensen says it best: the world needs both frontier closed models and frontier open models. We’ve been building in the open for years. Send me your CV and join @SFResearch. ❤️
I’m hiring a Research Scientist for my team at Salesforce AI Research!
Join us to build advanced AI Agents, push LLM boundaries, and design intelligent AIOps systems.
📍 Palo Alto, CA
🔗 Apply here: salesforce.wd12.myworkdayjob… #Hiring #SalesforceAI #AIAgents #LLMs
Huan Wang retweeted

🎇🎇🎇Our Webscale dataset is currently the No. 1 trending dataset on @huggingface.
huggingface.co/datasets/Sale…
@ZhepengCen @iscreamnearby @SFResearch


🚀🚀🚀 Webscale-RL: Automated Data Pipeline for Scaling RL Data to Pretraining Levels
We at @SFResearch build an automated pipeline that converts raw web text into verifiable QA pairs, filtered and verified by LLMs, then use Group Relative Policy Optimization (GRPO) to train models directly on this reward-driven data.
The result: models trained on Webscale-RL outperform continual pretraining and data-refinement baselines — while using up to 100× fewer tokens. The gains are most pronounced in reasoning, math, and factual QA tasks.
Beyond benchmarks, the key shift is conceptual: RL is no longer just a post-training alignment trick — it’s becoming a core optimization stage inside the LLM pretraining loop.
This points toward a future of mid-training RL, where large-scale synthetic or automatically verified datasets provide structured reward signals long before human feedback fine-tuning.
🧩 Webscale-RL hints at a new pretraining paradigm — one that learns not just from text, but from reward.
Paper: bit.ly/3IFuMhf
Code: bit.ly/42AVpdX
Data: bit.ly/4h5lVBS

Huan Wang retweeted

🤝 Doing task≠ Understanding user
LLM agents can complete tasks ✅
But truly aligning with messy, evolving human preferences? ❌
Check out UserBench, our new benchmark showing that even top LLMs uncover <30% of what users really want.
Tool use? ✔️
Human understanding? Not yet

🤝 Can LLM agents really understand us?
We introduce UserBench: a user-centric gym environment for benchmarking how well agents align with nuanced human intent, not just follow commands.
📄 arxiv.org/pdf/2507.22034
💻 github.com/SalesforceAIResea…

Huan Wang retweeted

🎉 Thrilled to see MCPEval recognized by @dair_ai in their "Top AI Papers of The Week"!
📄 Paper: arxiv.org/abs/2507.12806
💻 Code: bit.ly/44ZnUSN
MCPEval addresses a critical gap in agent evaluation by:
✅ Automating task generation & verification
✅ Providing deep evaluation across 5 real-world domains
✅ Eliminating manual bottlenecks that slow down development
Our findings revealed that smaller tool-enhanced models can match larger ones in specific domains - a game-changer for cost-effective AI deployments!
#MCPEval #AIAgents #OpenScience #FutureOfAI #EnterpriseAI


Optimizing LLMs isn’t just about accuracy — it’s about cost vs. performance.
Meet xRouter, an RL-based system from @SFResearch & UIUC that learns scalable, reproducible routing strategies to hit the sweet spot.
#LLM #RL #OpenSource #EfficientAI #ResearchPaper

Modern LLMs create a dilemma: powerful models are costly, cheap models are unreliable.
xRouter is a learned routing system trained via reinforcement learning with explicit cost-performance trade-offs. 🤖
Paper: bit.ly/49e0v3E
Key results: substantial cost reductions while maintaining accuracy across diverse benchmarks. 💰 The router dynamically chooses when to answer directly or delegate to external models—no hand-crafted rules needed. 🔀
Code: bit.ly/4nkIfct 💻
Authors: @qiancheng1231, @LiuZuxin, @KokaneShirley, @aksh_555, @_Jason_Q, @HaolinChen11, Zhiwei Liu, @hengjinlp, @iscreamnearby, @shelbyh_ai, @silviocinguetta, @CaimingXiong, @huan__wang
#FutureOfAI #EnterpriseAI


Webscale-RL automates large-scale RL data generation — turning pretraining text into millions of verifiable QA pairs across diverse domains.
A big step toward scalable RL for LLMs!

🚀 Scaling RL to Pretraining Levels with Webscale-RL
RL for LLMs has been bottlenecked by tiny datasets (<10B tokens) vs pretraining (>1T).
Our Webscale-RL pipeline converts pretraining text into diverse RL-ready QA data — scaling RL to pretraining levels!
All codes and datasets are open-source!
Paper: arxiv.org/abs/2510.06499
✨ Key features:
• Converts web-scale corpus into millions of verifiable QA pairs
• Preserves pretraining-level diversity across 9 domains
• Trains up to 100× more token-efficient than continual pretraining
• Powers the Webscale-RL dataset (1.2 M examples) for scalable RL
Also special thanks to my colleagues in Salesforce AI Research @SFResearch! @HaolinChen11, Shiyu, @LiuZuxin, @huan__wang, @CaimingXiong, @iscreamnearby

Congrats to the team for building Webscale-RL, an automated data pipeline that turns pretraining corpora into verifiable RL data at trillion-token scale.
Excited to see this bridge the gap between pretraining and RL!
@SFResearch #AI #LLMs #ReinforcementLearning #MachineLearning
📣 Webscale-RL: Automated Data Pipeline for Scaling RL Data to Pretraining Levels 📣
RL for LLMs faces a critical data bottleneck: existing RL datasets are <10B tokens while pretraining uses >1T tokens. Our Webscale-RL pipeline solves this by automatically converting pretraining documents into 1.2M verifiable QA pairs across 9+ domains.
📄 Paper: bit.ly/3IFuMhf
💻 Code: bit.ly/42AVpdX
📊 Dataset: bit.ly/4h5lVBS
Results: 100× more token-efficient than continual pretraining with significant performance gains on MMLU-pro, BigBench, and mathematical reasoning benchmarks 📈
Work by Zhepeng Cen (@zhepengcen), Haolin Chen (@HaolinChen11), Shiyu Wang (@shiyu04490786), Zuxin Liu (@LiuZuxin), Zhiwei Liu, Ding Zhao, Silvio Savarese, Caiming Xiong (@CaimingXiong), Huan Wang (@huan__wang), Weiran Yao (@iscreamnearby)
#FutureOfAI #EnterpriseAI #ReinforcementLearning #MachineLearning

Proud to see our latest research featured! Diffusion-based text generation is opening new possibilities for fast, efficient code synthesis. 🚀 #AI #DiffusionModels #CodeGeneration

Salesforce AI Research Releases CoDA-1.7B: a Discrete-Diffusion Code Model with Bidirectional, Parallel Token Generation
Salesforce AI Research released CoDA-1.7B, a discrete-diffusion code LLM that denoises masked sequences with bidirectional context and updates multiple tokens per step (non-autoregressive). The team provides Base and Instruct checkpoints, a reproducible pipeline (TPU pre-training, post-training/SFT, evaluation), and a FastAPI server exposing OpenAI-compatible endpoints with a CLI; decoding is controlled via parameters such as STEPS, ALG="entropy", BLOCK_LENGTH, etc. Reported pass@1 for CoDA-1.7B-Instruct: HumanEval 54.3%, HumanEval+ 47.6%, MBPP 47.2%, MBPP+ 63.2%, EvalPlus aggregate 55.4%; the model card compares to diffusion baselines (e.g., Dream-7B-Instruct 57.9% HumanEval). Checkpoints are released on Hugging Face under CC BY-NC 4.0....
Read our full analysis on CoDA-1.7B: marktechpost.com/2025/10/05/…
Model on HF: huggingface.co/Salesforce/Co…
Paper: github.com/SalesforceAIResea…
@salesforce @SalesforceDevs @SFResearch @iscreamnearby @HaolinChen11
@shiyu04490786
@canqin001
@bo_pang0
@LiuZuxin
@_Jason_Q
@JianguoZhang3
@yingbozhou_ai
Zeyuan Chen Ran Xu
@shelbyh_ai
@silviosav
@CaimingXiong
@huan__wang
@iscreamnearby
🚀 Meet our homegrown text diffusion model for code generation — insanely fast compared to autoregressive models. Speed + quality, all in one. #AI #Diffusion #CodeGen

Today my team at @SFResearch drops CoDA-1.7B: a text diffusion coding model that outputs tokens bidirectionally in parallel.
⚡️ Faster inference, 1.7B rivaling 7B.
📊 54.3% HumanEval | 47.6% HumanEval+ | 55.4% EvalPlus
🤗HF: huggingface.co/Salesforce/Co…
Any questions, lmk!

Our in-house text diffusion model for code generation is here — delivering massive inference speedups over traditional autoregressive models. ⚡️🚀 #AI #CodeGeneration #DiffusionModels
CoDA-1.7B: A diffusion language model for code generation with bidirectional context understanding 🔄
📄 Technical Report: bit.ly/3IBlzGG
🤗 Model: bit.ly/48dX1xN
💻 Code: bit.ly/3VSXKwT
The model achieves 54.3% pass@1 on HumanEval 📊 while matching performance of diffusion models up to 7B parameters. Fully reproducible training pipeline included—from TPU pre-training through instruction tuning.
Key features:
➡️ Discrete diffusion processes enable understanding of both past and future tokens
➡️ Confidence-guided sampling maintains competitive inference latency ⚡
➡️ Complete reproducible training pipeline from pre-training to fine-tuning 🔬
#FutureOfAI #EnterpriseAI #DiffusionModels #OpenScience

End-to-end #AI agents still struggle on complex tasks.
But when humans collaborate with agents — guiding, correcting, interacting — we get much closer.
Our preliminary work: training agents in multi-turn RL.
#AIAgents #ReinforcementLearning #AIResearch #LLM
🚀 Introducing UserRL: a new framework to train agents that truly assist users through proactive interaction, not just chase static benchmarking scores.
📄 Paper: arxiv.org/pdf/2509.19736
💻 Code: github.com/SalesforceAIResea…
