
Founder at @blankbio_ PhD @ Department of Computer Science, University of Toronto.
Joined November 2019
- Tweets49
- Following49
- Followers219
- Likes184




Pinned Tweet
Excited to annouce our seed round!

Today, we’re excited to announce our $7.2M seed round alongside a strategic collaboration with @PacBio! At Blank Bio, we help pharma make more informed decisions in clinical trials by capturing the biology that makes each patient’s tumour unique.
We do this by training RNA foundation models to learn the patterns that shape disease progression and how patients respond to treatment. In our collaboration with @PacBio, we will generate long-read, bulk RNA-sequencing data from patient tumour samples across multiple indications. This dataset will be used to further train and evaluate our models.
Our models are currently focused on two main applications. First, we predict how a patient’s disease is likely to progress over time from their molecular profile. Through the FDA-recommended approach of covariate adjustment, these RNA prognostic scores can help clinical development teams design trials that reach statistical power with fewer patients. Second, we’re working to help pharma teams understand biological differences between patients so they can identify who is most likely to respond to a given therapy.
We are thankful to @definevc, @LeonisCapital, Nova Threshold, @ripple_ventures, @SignalFire, @ycombinator, and other investors for being early supporters in our vision. This financing will support the continued development of our foundation models, expanded collaborations with pharma, and growing our patient-level datasets.
Read the press release: blank.bio/seed-announcement
Read the blog from the team: blank.bio/accelerate-clinica…
Learn more about Blank Bio: blank.bio

Ian Shi retweeted

Really happy to welcome @WilliamOhMD as a scientific advisor to @blankbio_!
William’s career spans leadership roles at @DanaFarber, @MountSinaiNYC, @Sema4, and @PCFnews. He now leads Precision Medicine at @YaleCancer and @SmilowCancer.
He brings decades of experience caring for patients, leading cancer research, and translating molecular data into evidence, including work on blood-based RNA signatures in advanced prostate cancer.
At Blank Bio, we’re building models of patient biology using RNA to predict treatment response and clinical outcomes. By learning more from each patient, we want to make clinical trial abundance possible: more trials, each requiring fewer patients and focused on those most likely to benefit.
William brings the experience to help us connect those ambitions to the realities of drug development and patient care. Welcome, William! Really excited to build together.
blank.bio/william-oh-scienti…

Ian Shi retweeted

I wish more companies in the genetic medicines space used GenomeKit (github.com/deepgenomics/Geno…). I've used it almost every single day over the last five years. Without hyperbole, I can say I feel a little ray of sunshine every time I `import genome_kit as gk`.

Ian Shi retweeted

In reading group reviewing flow models, I realized I didn't understand the change-of-variables rule as fully as I probably should. So I put together this blog post and collection of visuals to help me more fully understand the Jacobian-inverse term. 💪
michaeljohncooper.com/writin…


Ian Shi retweeted

A year out of YC, some reflections on going from my PhD to building in biotech and what it means to be a formidable founder
philechka.com/2026/09/20/for…
Ian Shi retweeted

I joined @blankbio_ this week in SF! Now feels like a great time to be building foundation models for biology.
I'm excited by what these models would enable e.g. an understanding of gene expression data could better predict individual differences in drug response.
Ian Shi retweeted
We had a great time sponsoring @ASABiopharm RISW 2026 last week and speaking with biostatistics and clinical development leaders!
Many of our conversations focused on a question we think about a lot: how can we make clinical trials more efficient? One part of the answer is making better use of the clinical and biological data collected during trials. As more studies generate molecular data, foundation models can help extract meaningful biological signal and make more accurate predictions about patient outcomes, like survival.
These predictions can inform trial design and analysis to reduce uncertainty, build statistical power faster, and help trials reach their endpoints sooner.
If you’re interested in how biological foundation models could help shorten oncology trials, we’d love to hear from you. Let’s chat!

Ian Shi retweeted

In the latest blog from the team, we share an early look at Ladon, our bulk transcriptomics foundation model. We embedded more than one million public RNA-seq samples spanning over 20 years of literature, exposed that embedding space through an MCP, and let Claude search it.
Our goal was to explore how much better AI agents could get at scientific discovery if they could search in biological embedding space instead of text.
Read the blog here: blank.bio/ai-agents-will-acc…


How much better could AI agents get at scientific discovery if they could search in biological embedding space instead of text?
Over the past few months, we’ve been building Ladon, our bulk transcriptomics foundation model. As an experiment, we embedded over 1 million public RNA-seq samples spanning 20+ years of research, exposed that embedding space through an MCP, and let Claude search it.
Today, AI agents search titles, abstracts, metadata, and keywords. They can’t search the biology itself.
Ladon maps every RNA-seq sample into a shared biological embedding space, allowing agents to search by biological similarity instead of text. A naive search mostly retrieves studies from similar tissues or diseases. What we actually want to match is the transcriptomic signature itself: the pattern of what changed in a study, not the tissue or disease it happened to use. Searching on that lets an agent connect experiments across diseases, tissues, and perturbations, even when the papers share no keywords.
We explored a case study where this surfaced novel hypotheses that would have been difficult to find through traditional search with agents.
Read more in the blog: blank.bio/ai-agents-will-acc…
If you're sitting on large RNA-seq datasets and want to harmonize them with the public transcriptome to power agent-driven discovery, we'd love to collaborate. Reach out!

Ian Shi retweeted
How much better could AI agents get at scientific discovery if they could search in biological embedding space instead of text?
Over the past few months, we’ve been building Ladon, our bulk transcriptomics foundation model. As an experiment, we embedded over 1 million public RNA-seq samples spanning 20+ years of research, exposed that embedding space through an MCP, and let Claude search it.
Today, AI agents search titles, abstracts, metadata, and keywords. They can’t search the biology itself.
Ladon maps every RNA-seq sample into a shared biological embedding space, allowing agents to search by biological similarity instead of text. A naive search mostly retrieves studies from similar tissues or diseases. What we actually want to match is the transcriptomic signature itself: the pattern of what changed in a study, not the tissue or disease it happened to use. Searching on that lets an agent connect experiments across diseases, tissues, and perturbations, even when the papers share no keywords.
We explored a case study where this surfaced novel hypotheses that would have been difficult to find through traditional search with agents.
Read more in the blog: blank.bio/ai-agents-will-acc…
If you're sitting on large RNA-seq datasets and want to harmonize them with the public transcriptome to power agent-driven discovery, we'd love to collaborate. Reach out!
Ian Shi retweeted

High-resolution AI models require high-resolution data. We are excited to partner with @blankbio_ as they use #PacBio HiFi long-read RNA sequencing to unlock greater interpretive power for precision oncology.
Read the full announcement here: bit.ly/3Ps0GkB

Today, we’re excited to announce our $7.2M seed round alongside a strategic collaboration with @PacBio! At Blank Bio, we help pharma make more informed decisions in clinical trials by capturing the biology that makes each patient’s tumour unique.
We do this by training RNA foundation models to learn the patterns that shape disease progression and how patients respond to treatment. In our collaboration with @PacBio, we will generate long-read, bulk RNA-sequencing data from patient tumour samples across multiple indications. This dataset will be used to further train and evaluate our models.
Our models are currently focused on two main applications. First, we predict how a patient’s disease is likely to progress over time from their molecular profile. Through the FDA-recommended approach of covariate adjustment, these RNA prognostic scores can help clinical development teams design trials that reach statistical power with fewer patients. Second, we’re working to help pharma teams understand biological differences between patients so they can identify who is most likely to respond to a given therapy.
We are thankful to @definevc, @LeonisCapital, Nova Threshold, @ripple_ventures, @SignalFire, @ycombinator, and other investors for being early supporters in our vision. This financing will support the continued development of our foundation models, expanded collaborations with pharma, and growing our patient-level datasets.
Read the press release: blank.bio/seed-announcement
Read the blog from the team: blank.bio/accelerate-clinica…
Learn more about Blank Bio: blank.bio
Same.

Excited to share Orthrus is now published in Nature Methods! This was a work from our PhDs in which we showed 3 things:
- There's lots of room for new biologically grounded self-supervised objectives
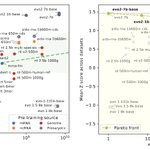
- The "y - intercept" in scaling is important! We show that representations from 10 million parameter Orthrus outperform a 7 billion parameter model, 700 its size.
- Orthrus works in the low-data regime where data acquisition is especially expensive: low throughput experimental data and clinical trials
Ian and I are now building BlankBio to apply these ideas at a bigger scale. I'm going to be at AACR get in touch if you want to chat!

Ian Shi retweeted

We just gave five SOTA models $10K in real cash to make bets on @Kalshi. Introducing Prediction Arena.
Prediction markets are a rare, concrete way to eval whether AI can reason about the most probable outcomes over time. Sustained profitability signals progress toward real-time, real-world reasoning.
The starting players are:
@OpenAI GPT 5.2
@GoogleDeepMind Gemini 3 Pro
@AnthropicAI Claude Opus 4.5
@xai Grok 4.1 Fast
@Zai_org GLM 4.7
Watch them trade live at predictionarena.ai, methodology below

Ian Shi retweeted
Excited to co-host an ML × Bio Mixer at #neurips2025 with @SignalFire!
Join us Dec 4 @ 6 PM for food, drinks, and good convo with others building at the ML × bio frontier. Plus, we’re hiring!
Open roles: ycombinator.com/companies/bl…
RSVP: luma.com/1ycvcndz

Ian Shi retweeted
Last week, we wrapped up the summer batch @ycombinator. Demo Day was surreal!
Super fun to get on stage with @ianshi3 @phil_fradkin and share more about @blankbio_
Shoutout to @agupta, our batchmates, and the YC community for making this an unforgettable experience 🚀


Will scaling current nucleotide foundation models lead to a GPT-3 moment for biology? Probably not.
Although models like Evo2 are impressive in many ways, their pre-training objectives can struggle to outperform supervised learning.
I dive into why at: quietflamingo.substack.com/p…
