

He/him | Langley Fellow @PittDietrich | I study lensed galaxies with space telescopes | ex@astrobites @UChicago @cambridge_astro @iitdelhi (personal account)
Pittsburgh, PA
Joined January 2012
- Tweets5.8K
- Following2.5K
- Followers975
- Likes12.4K




Pinned Tweet
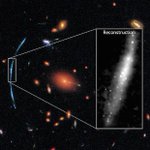
I'm always late on Twitter and it's been a tiring month, but I'm going to cherish this for a bit: Michael Florian (U.Arizona) and I will co-lead a 70-hour Cycle 2 JWST program to study the building blocks of galaxies: star forming regions magnified due to gravitational lensing!!

ALT Hubble imaging of a gravitationally lensed galaxy in the JWST sample -- SGAS1110 (blue) -- lensed by a foreground massive galaxy cluster (orange). Also shown is a zoomed-in picture of a model reconstruction of the galaxy, if it was unlensed (or not distorted by lensing).


Gourav Khullar retweeted

They told us to “go paperless to save the planet” and “go digital to save the trees.” Now we’re destroying 250,000 trees, wasting millions of gallons of water and wrecking ecosystems to build data centers that will damage the planet more than paper ever did.

Gourav Khullar retweeted

im four beers deep and i need everyone to understand that wikipedia is the last good thing. millions of strangers agreed to write down everything for free and then argue about citations forever. no ads. no paywall. this should not exist and it does and i'm crying about it
Gourav Khullar retweeted

Sam Altman thinks RAM sitting in personal computers is a waste when it could be put to better use in data centers.
Weird. I was just thinking that all those billions sitting in billionaires’ bank accounts could be put to much better use in our communities.
Gourav Khullar retweeted

People use the fact that Palestinians voted for Hamas in 2005 as a permanent indictment of the character of the population (despite the majority being under 20 and barely sentient in 2005) but never apply those standards to Israelis consistently voting for a genocidal maniac

🚨🇮🇱 UPDATE: Channel 14 has updated its exit poll, projecting Benjamin Netanyahu’s bloc to reach 61 seats, securing a Knesset majority
Exit Poll Results:
🔵 Netanyahu bloc: 61 seats
🔴 Change bloc: 42 seats
🟢 Arab parties: 17 seats
61 seats needed for a majority
Avigdor Lieberman’s Yisrael Beiteinu has also fallen below the electoral threshold
Gourav Khullar retweeted

Truly embarrassing stuff.

Mikel Arteta defends Arsenal job cuts to allow club to “improve and evolve.” Redundancies announced just a week after Arteta’s new £20m-a-year deal mirror.co.uk/sport/football/…


Gourav Khullar retweeted

There’s something uniquely damning about these confessions. They make the allegations irrefutable. But it’s difficult to describe how infuriating it is to spend years documenting the slaughter of your people and still not be believed until their murderers confirm that, yes, it happened exactly as we’ve been saying all along.

Yuval Abraham and Rachel Szor’s ‘Naza’ is one of the most important films of our time. 24 different Israeli intelligence officers testify in this unflinching exposé of systematic Israeli war crimes in Gaza. vulture.com/article/review-n…

Gourav Khullar retweeted
Western media for 3 years: Israel says they’re targeting Hamas
Israeli soldier: We targeted everyone

IDF drone operator: "I asked to meet with the intelligence officer so I could enter targets into the computer, and he told me, ‘You have two million targets in Gaza.' The trigger was pulled extremely easily. People lost their humanity."
Testimony (Heb): haaretz.co.il/news/magazine/…

Gourav Khullar retweeted

does this report on “misuse” cover how your software was integrated into Palantir’s Maven system, used by the US military to generate target packages during its bombing campaign in Iran - including the campaign in which a U.S. strike killed 120 kids at a school in Minab?

We're publishing our most detailed threat intelligence report to date.
It covers how people tried to misuse Claude—for cyberattacks, influence operations, surveillance, biology, and building weapons—and how we found and stopped them.
We disrupted every operation in the report, and used the lessons from them to strengthen our safeguards. Where appropriate, we also shared what we found with authorities and other AI companies.
These cases are not typical: we’re highlighting some of the most sophisticated misuse we’ve seen. But they’re especially important to discuss, because they show us where AI misuse is headed, where our safeguards work, and where they need to improve.
We’re publishing this report so others can spot the same activity on their own platforms, and so we can give the public a clearer view of how emerging threats develop.
Read the report: anthropic.com/threat-intelli…

Gourav Khullar retweeted

Oye, Sam Altman, hay rumores de que un científico de Anthropic está a punto de resolver el problema de la vivienda en España
Gourav Khullar retweeted

Imagine if the head of security at CERN came out to say that there is a >10% chance that a destructive black hole will be created in the next 10 years. What are we even doing here


Gourav Khullar retweeted

So when you see several AI Safety researchers from Anthropic all confess they believe AI could kill all humans in the next decade, SURELY the correct response is to support a pause on frontier AI research until we figure out what the fuck is going on, no?
Gourav Khullar retweeted
"My job has a 1 in 10 chance of killing all humanity but at least I'm trying my best 👉👈🥺"
Gourav Khullar retweeted

i once asked a bunch of deep-tech researchers on why they wouldn’t use chatgpt for serious research, especially after openai launched Prism tool around a workflow researchers already know well: LaTeX. Their responses were surprisingly consistent: they were afraid that putting genuinely novel, unpublished ideas into chatgpt or any other llms could expose or compromise their research originality.
Whether or not that fear is technically justified, the perception itself is a problem. If OpenAI wants researchers to trust these tools with high-stakes research, there needs to be much more explicit transparency around who can access conversations, how research data is retained, whether it is used for training, and what protections exist for unpublished IP.
i assume frontier labs can access at least ~70% of user conversation details internally, even if PII is stripped or access is tightly controlled?

We congratulate Levent Alpöge and Tristan Buckmaster on their remarkable mathematical work.
We (the researchers and the agents) did not see any of their work through any means until they released it publicly — in particular, no specific user data was accessed in order to solve this problem.
While unlikely, we cannot rule out that de-identified data derived from their usage of our products helped improve our models.
However, our proofs differ significantly and even the precise results proved are different in the Euler case (forced vs. unforced).
Gourav Khullar retweeted

tristan buckmaster just published a statement that is, if accurate, one of the ugliest things i’ve read out of a frontier lab.
not because of the math. because of what happened after openai found out two people were about to beat them to the punch.
buckmaster and levent alpöge spent a year pushing the córdoba / martínez-zoroa program to smooth forcing. august 15 they got blowup for boussinesq and 3d euler. lean-verified august 22.
they were paying openai out of pocket and dumping every draft into private codex sessions.
the program is obscure. almost nobody else was on it. this was not “paste the clay problem into a chatbot.”
then this:
> thursday sept 3, buckmaster emails openai privately. rumors are flying. he is trying to stop a mess, not start one.
> they reply the same day: give us details so we can “avoid competing.” also, want free compute?
> sunday they suddenly need a call “at any point today.” sebastien bubeck gets on. levent is not invited.
> openai says an internal model has a ~100-page proof of forced navier–stokes blowup. fefferman options c and d. the exact route buckmaster and alpöge had quietly chosen.
> they show him a prompt and claim the model was “simply given the problem statement.” levent is told “very little human input.”
> that falls apart on the same call. a whole team had been on it. they started on the unforced problem, warmed the model up on easier equations including euler, and even the prompt they showed him was written by prompting codex.
> he asks when the first prompt went out. they stall. then agree: the past few days. after information about his work reached openai.
> he asks whether the model was trained on, or had access to, the private codex sessions where they put every draft of this project.
> answer: the model does not look up user data.
> he asks again. about training.
> no answer.
then it stops being a science story and becomes an hr story.
> offer 1: you post euler. we post navier–stokes the next day.
> offer 2: after you post euler, you alone write the navier–stokes paper, credit our model, and we cut levent.
> bubeck says twice he wants levent removed from authorship because he works at anthropic.
he declines both.
he says if they release it that way, he goes public.
the reply is not a scientific objection.
> “why would you ruin your career?”
> “if you don’t want me to be nice, then i don’t have to be nice.”
later, a text to levent proposing a one-on-one:
> “i don’t know if tristan is being fully rational right now.”
that is not how you treat a collaborator. that is how you split one.
openai got word two researchers were closing a path almost nobody else was on. they spun up a team on that exact path. they would not answer whether the researchers’ unpublished drafts in openai’s product were used. they tried to dictate the announcement order. they tried to remove a coauthor because he works at a competitor.
when that failed, someone reached for a career threat.
this is a lab finding out academics were about to publish, sprinting the same narrow program, refusing the data question, and trying to manage credit around a rival affiliation.
really slimy if even half of this holds.
what the fuck is happening.


holy shit.
tristan buckmaster is saying openai has a forced navier–stokes blowup via the córdoba / martínez-zoroa program.
and that it may have used drafts from his and levent alpöge’s private codex sessions.
that’s the córdoba / martínez-zoroa route. almost nobody else was on it.
he also says the first prompt went out after information about his and levent alpöge’s work reached openai. that “very little human input” was not true. that a whole team had already been set on easier problems, including euler. that even the prompt they showed him was written by prompting codex.
then he asked:
did the model have their private codex sessions.
no answer on training.
if any of that holds, openai didn’t just scoop a math result. they may have done it off two researchers’ unpublished drafts, then tried to cut the coauthor because he works at anthropic.
a millennium-problem-adjacent result just became employee drama before an ipo.
i don’t even know which part is crazier.
this is one of the slimiest things i’ve seen in this industry.

Gourav Khullar retweeted

Subes tu artículo o tesis a ChatGPT para que “corrija” la ortografía.
Tiempo después, un investigador en otro país publica tu trabajo. ChatGPT se lo sugirió cuando utilizó tus datos como entrenamiento.

Gourav Khullar retweeted

all other allegations aside, "we caught wind that a mathematician might be about to solve a famous problem so we spent $15 million on tokens to scoop them" is exactly why OpenAI is completely full of shit when it says it wants to work with the academic community in a positive way