
EE PhD Student at Image and Video Understanding Lab (IVUL), KAUST. Staring at the abyss since 1995. 🇱🇧 in 🇸🇦
Thuwal, KSA
Joined June 2019
- Tweets32
- Following274
- Followers296
- Likes59

Hani Itani retweeted

Excited to share our new paper "Beyond the Last Answer: Your Reasoning Trace Uncovers More than You Think"!
We show that digging into an LLM’s intermediate “subthoughts” and aggregating their answers can significantly boost math reasoning performance.
A thread 🧵

Hani Itani retweeted
Just released "DiffCLIP", extending Differential Attention proposed by @ytz2024 to CLIP models - replacing both visual & text encoder attention with the differential attention mechanism!
TL;DR: Consistent improvements across all tasks with only 0.003% extra parameters!

ALT Queries from left to right from top to bottom are: Mug, Lamp, Flower and Dog.
A fun little side project. Check it out!

🚀 Introducing SALL-E V1.5, a Stable Diffusion V1.5 model fine-tuned on DALL-E 3 generated samples! Our tests reveal significant improvements in performance, including better textual alignment and aesthetics. Samples in 🧵. Model is on @huggingface
huggingface.co/hammh0a/SALL-…

1
5
754
We're excited to release a minimalistic code-base to finetune LLaMA models with 🐫CAMEL @CamelAIOrg data. We provide data preprocessing pipeline and finetuning and an example of serving the model: github.com/camel-ai/camel_ch…. This code heavily borrows from FastChat. Thanks @lmsysorg!

Hani Itani retweeted

Evaluation is one of the hardest problems of LLMs. A small tokenizer fix made a huge difference. But still, this result does not mean much for a chat model. Again we host our CAMEL-33B model for you to explore: camel-ai.org/chatbot. Follow @CamelAIOrg for more research updates

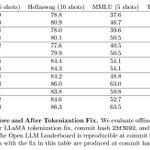
The @huggingface #OpenLLMLeaderboard has attracted a lot of interest lately, but did you know that it puts LLaMA based models at a disadvantage? In our evaluations using a recent commit of @AIEleuther's lm-evaluation-harness, LLaMA based models improve by 4-5 points on average!

The @huggingface #OpenLLMLeaderboard has attracted a lot of interest lately, but did you know that it puts LLaMA based models at a disadvantage? In our evaluations using a recent commit of @AIEleuther's lm-evaluation-harness, LLaMA based models improve by 4-5 points on average!
In the table above we show that LLaMA-65B actually outperforms Falcon-40B-Instruct, and its MMLU performance are more consistent with those in the paper. This is also in line with the findings of @Francis_YAO_ last week nitter.cf/Francis_YAO_/status/16…

Is Falcon really better than LLaMA?
Short take: probably not.
Longer take: we reproduced LLaMA 65B eval on MMLU and we got 61.4, close to the official number (63.4), much higher than its Open LLM Leaderboard number (48.8), and clearly higher than Falcon (52.7).
Code and prompt open-sourced at github.com/FranxYao/chain-of…
No fancy prompting engineering, no fancy decoding, everything by default.
----
Full story:
On OpenLLM Leaderboard (huggingface.co/spaces/Huggin…), Falcon is the top 1, suppressing LLaMA, and promoted by @Thom_Wolf (nitter.cf/Thom_Wolf/status…)
Yet later @karpathy expressed concern about why on Open LLM Leaderboard, the LLaMA 65B score is significantly lower than official (48.8 v.s. 63.4), see nitter.cf/karpathy/status/…
We figure that a simple quick open-sourced evaluation script on LLaMA 65B would clarify, so we just did it github.com/FranxYao/chain-of…
Again, everything is default, official MMLU prompt, no fancy prompt engineering, no fancy decoding. LLaMA 65B simply can do it. We encourage everyone to try the eval script out.
This result makes us continue to hold the belief that the best bet of open-source community to get close to GPT-3.5 is to do RLHF on LLaMA 65B, per our previous discovery in Chain-of-thought Hub arxiv.org/abs/2305.17306
Yet we do not intend to raise wars between LLaMA and Falcon -- both are great open-sourced models and have made significant contribution to the field! Falcon also have the advantage of a easier license, which also gives its great potential to be awesome!
🍻🍻
1
11
2,558
Our CAMEL-33B model is available for download here: huggingface.co/camel-ai/CAME… Joint work with @guohao_li , @hammh0a, @Obs01ete , and @BernardSGhanem at @KaustVision

Checkout our model CAMEL-13B! We evaluate our model on the datasets suggested by @huggingface Open LLM Benchmark using @AiEleuther's language model evaluation harness and we score an average of **58.1**, on par with LLaMA-65B (58.3)! Joint work with @guohao_li & @hammh0a .
Chat with CAMEL-13B here [1d2ade3b7239760df6.gradio.li…]
Dataset and model weights are available here [huggingface.co/camel-ai]
1
7
972
Hani Itani retweeted
🐪CAMEL🐪
Communicative Agents for “Mind” Exploration of LLM Society
This paper shows how to put 2 agents in a sandbox with each other and watch them interact. Now implemented in LangChain! (s/o @guohao_li)
Original Paper: arxiv.org/abs/2303.17760
Docs: python.langchain.com/en/late…

Hani Itani retweeted
We noticed that open-source chat models lack mathematical reasoning and fail in solving simple math problems (see example below). To bridge this gap, we've released 20K math problem-solution pairs generated and solved by ChatGPT-4.
github.com/lightaime/camel#d…

Hani Itani retweeted
📢 We have released our CAMEL🐪 datasets and to help you explore their diversity, we have created information cartography maps using the @Nomic_AI Atlas.
Visualization links: github.com/lightaime/camel#v…
Technical report: ghli.org/camel.pdf
Project web: camel-ai.org/

We just released two large scale conversational instruction-following datasets through our CAMEL framework: AI Society and Code datasets. We hope these datasets will help improve understanding of the cooperative behaviors and capabilities of chat agents. github.com/lightaime/camel
Hani Itani retweeted
Did a live demo of our CAMEL
github.com/lightaime/camel project at today's group meeting @KAUST_News @KaustVision.
The task prompt is to design a custom game using PyGame. The two #ChatGPT agents (computer engineer and game) decide to make a treasure game.
It just ran bug-free!
Hani Itani retweeted
Co-work with @itanih0 @hammh0a. We are so curious about how ChatGPT agents would interact with each other. Here comes our project CAMEL. Two agents, a gamer and a computer programmer, collaborate on creating a game:
Github: github.com/lightaime/camel
Colab: colab.research.google.com/dr…
