

@eagerworks CTO & co-founder. I like to build stuff. Writing CUDA kernels before it was cool
United States
Joined November 2012
- Tweets615
- Following1.4K
- Followers441
- Likes2.5K




Pinned Tweet
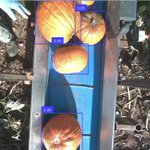
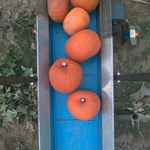
🍎We built a real-time inspection system at Eagerworks.
🎯Finetuned RF-DETR + ByteTrack for detection & counting
📏Size measurement
🍏AI-powered ripeness classification
📊Live throughput analytics
⚡100% on-device. No cloud
Can be adapted to any problem and industry
4
9,595
Juan Pablo Balarini retweeted

there is no replacing a founder like Jensen.
There never has been, and there can never be, a true succession for a founder like him. Nvidia ends today, and is replaced with a thing cosplaying nvidia. It will be run by custodians trying and failing to preserve the flame he ignited
Astra can what??😮

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
39
This will get interesting. We can now generate synthetic data to train AI models using UE5

We’ve updated the Unreal Engine EULA so devs can now choose to train AI models on their UE and MetaHuman projects, and benefit from AI models that understand their code and content.
This change does not give Epic any rights to your content or code.
Check out the blog for the details: epic.gm/ue-eula-updates

26
Juan Pablo Balarini retweeted

We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.

Juan Pablo Balarini retweeted

OK, I can't wait any longer—here is the repo for my Command & Conquer Generals: Zero Hour VR / MR mod for @MetaQuestVR Quest 3 / 3S, featuring stereoscopic 3D and a tabletop-style view. An initial version of the ground-level view is also included.
You just need the original game files, ideally from Steam. Here is the link to the repo containing the APK:
github.com/Cesarus85/General…
Installation is relatively straightforward:
- Transfer the game files to your Quest using a tool of your choice.
- Sideload the APK.
- Launch the APK from the Quest's "Unknown Sources," select the Generals directory on the device, and you're good to go!
(1/2)
Juan Pablo Balarini retweeted

A long-overdue look back at our August 13 meetup at @eagerworks ! 📸💎
Thanks to @santib6_ and Carlos for the talks, to @eagerworks for hosting us, and to everyone who joined!
See you at the next one!
Stay tuned! 😉


Juan Pablo Balarini retweeted
A lot of people are asking how I pulled off these super long-horizon builds with Astra.
Astra is extremely powerful, but by default it struggled with a task this difficult. I tested a bunch of approaches to get past this, and the one I landed on is something I'm calling the Manager Loop.
It's basically a couple of tricks we used to use with much less capable models a couple of years ago, with a few new ideas layered on top. Turns out that when you put those together and apply them to Astra, its ability to do extremely difficult long-horizon tasks goes up dramatically.
Here's how it works:
1. Launch an agent (I'm calling this one the "manager"). Chat with it about what you want to get done, and have it build a massive checklist of to-dos, then break that checklist into phases.
2. The manager then spawns a second Codex agent in a separate thread (the "implementer"). The two agents can message each other.
3. Put the manager in /goal mode, and tell it to run each phase on the implementer in /goal mode.
4. The manager messages the implementer: "/goal Complete phase one completely, extremely well." The implementer doesn't stop until that phase is done, then messages the manager back. The manager tells it to start phase two. They repeat until every phase is finished, completely autonomously.
Why I think this works: over a long-horizon task, Astra tends to asymptote. It gets way further than previous models, but at a certain point it kind of just stops improving against the goal as quickly as it did before. It gets stuck in the minutiae, focusing way too much on small details, and overall progress stalls. The Manager Loop forces it to work piecemeal, one phase at a time. It's essentially how a human would steer a model, except the model is doing the steering for me.
That's actually how this started. I was having the model write the checklist and break it into phases, and then I was doing the manager's job by hand. At some point I thought, "Wait, why can't I just get a separate AI to do this?" That's what unlocked full autonomy, which is super useful.
A wording detail that seemed to matter: I ask for each phase to be done "extremely well," not "perfectly." Maybe I'm reading too much into it, but asking for "perfect" sent the model right back into the minutiae. "Extremely well" implies it's allowed to move on once it's good enough, and that worked better in my testing.
One more trick that I think helps (this one is more of a hunch, but it was useful for me): have the implementer build a simple HTML page with the full checklist on it. The implementer checks boxes off as it goes and updates a counter, and the page has a chart of # of boxes ticked over time.
Obviously the boxes aren't all equal, but it forces the model to notice things like "I haven't made progress in a while, time to move on." You can even put this in the prompt directly, like: "if you haven't ticked a box in X amount of time, move on". That helps a lot.
I also ran 96 sub-agents at a time. You can change this in your Codex config (or just ask Codex to change it).
This got me far better long-horizon performance than anything else I tried. I'll be sharing more in the coming days!

Juan Pablo Balarini retweeted

Here Qwen3.8-Flash-Next-MLX-Serve-4bit running on Macbook Pro M5 Max using mlx-serve compiled from sources.
Now I'll try to speed the kernel even more and then I'll plug Hermes Agent into this beast! Be ready @ddalcu 🚀
For anyone willing to try this:
- install latest mlx-serve and get llmprobe (github.com/ddalcu/llmprobe)
- configure it as per screenshot below
- npx llmprobe localhost:11234 --quick


Qwen 3.8 Flash Next (125B-A6B) now runs natively in mlx-serve on Apple Silicon. No Python, Zig + Metal. (Preview Release)
M4 Max, 4-bit pack (~75 GB resident):
- ~70 tok/s serial, ~98 tok/s with MTP when tested using `npx llmprobe`
- prefill ~700 tok/s, sparse attention past 2k tokens with fused kernels
- images and video input supported
Hyper-connections, n-gram embeddings gathered straight from disk, QSA block selection, 5 new Metal kernels. All open source, parity-tested against the HF reference.
Kernel work:
- hyper-connection read: 3 Metal kernels, split-K, write folded into the next read
- GDN decode: 2 fused dispatches per layer
- hd-256 attention: mask arm, sparse prefill + verify stay fused
- all greedy-equivalent to the unfused path
If you port any of this to your engine, a mention would be nice.
MLX-Serve Preview 26.8.11 build: github.com/ddalcu/mlx-serve/…
4bit Speed Pack: huggingface.co/ddalcu/Qwen3.…
4-8bit Quality Pack: huggingface.co/ddalcu/Qwen3.…
As for the model, i'm not sure yet, it feels verbose, and Opus like. Thinks a lot. Goes on long self testing loops/talking with itself, but need more time with it. It seems like a good model for agentic things.
Juan Pablo Balarini retweeted

I got 96.2% on ARC-AGI-3 with Opus 5, and 99.3% pass@2. The program is basically Claude Code + Opus 5 (high), one action command, and filesystem logs. Almost nothing ARC specific.
github.com/jerber/arc-code

Juan Pablo Balarini retweeted

🚀 DeepSeek-V4-Flash Official API is now LIVE in public beta!
🔷 We’ve massively upgraded its Agent capabilities—benchmark scores are now far surpassing the V4-Pro-Preview. Check out the massive performance leap below! 👇
🔷 The official V4-Flash now natively supports the Responses API format and is fully adapted for Codex!
Check out the configuration details in our official API docs: api-docs.deepseek.com/quick_…

Juan Pablo Balarini retweeted

My opinion is that Mythos is the current best model but not actually some world-changing dangerous model, and that anthropic did their usual song and dance about safety largely because they didn’t have enough compute to serve it at scale
So then they launched Fable because they still have to think about the IPO, but they are still somewhat compute limited so they put all sorts of restrictions on it
Around the same time, because they are trying to get regulatory capture and not because things are actually dangerous, Dario did more scaremongering and published his honestly confusing white paper that offered no real solutions
So finally they succeeded, they managed to freak out the government, their cynical plan backfired, and now it’s a giant pain in the ass

In a couple of weeks, I'll be in San Francisco.
If you’re working on a product, exploring AI opportunities, or just want to exchange ideas, let's connect! 🙌

1
32
Juan Pablo Balarini retweeted

Alright.. The new port is ready!
There are some bugs left but it's way more accurate.
🎮 mrdoob.github.io/three-quake…
💻 github.com/mrdoob/three-quak…
The trick was to ask the AI to keep the same file structure and port file by file.
Juan Pablo Balarini retweeted

queue.json on object storage is all you need to build a reliable distributed job queue
→ FIFO execution
→ at-least-once delivery
→ 10x lower tail latencies
tpuf.link/queue

Juan Pablo Balarini retweeted

Introducing GLM-5: From Vibe Coding to Agentic Engineering
GLM-5 is built for complex systems engineering and long-horizon agentic tasks. Compared to GLM-4.5, it scales from 355B params (32B active) to 744B (40B active), with pre-training data growing from 23T to 28.5T tokens.
Try it now: chat.z.ai
Weights: huggingface.co/zai-org/GLM-5
Tech Blog: z.ai/blog/glm-5
OpenRouter (Previously Pony Alpha): openrouter.ai/z-ai/glm-5
Rolling out from Coding Plan Max users: z.ai/subscribe


Is AI hindering learning? It depends on how you use it

AI can make work faster, but a fear is that relying on it may make it harder to learn new skills on the job.
We ran an experiment with software engineers to learn more. Coding with AI led to a decrease in mastery—but this depended on how people used it.
anthropic.com/research/AI-as…

1
83