


Andy Luo retweeted

🚀 ATOM Meets Mooncake: Scaling Agentic LLM Serving on AMD Instinct GPUs!
A deep dive into how NeuroSpark AI deploys AMD's ATOM and Mooncake to serve GLM-5.3 across 32 AMD Instinct MI350X GPUs.
With ATOM, ATOMesh and Mooncake's shared KV pool:
🔥 95–96% KV cache reuse on production traffic
⚡ Up to 2× throughput vs. per-server KV pools in AgentX benchmarks
🚀 Scalable agentic LLM serving across servers
Read the full story 👇
kvcache.ai/blog/atom-meets-m…


Andy Luo retweeted

AMD really cooked here. Kimi K3.1 Pro on our 8xMI350X (default SGLang recipe) is a whole different experience at 300 tok/s (up from like 60 with K3), the speed makes it often a better choice than Astra/Opus.


Andy Luo retweeted

Muse Spark Open 🤝 AMD Instinct GPUs.
Day 0 support is here for the first open weights model: Muse Spark Open.
Start building 👇
amd.com/en/developer/resourc…


Andy Luo retweeted

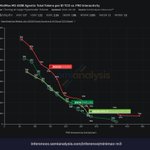
Great work from the @TileRT_AI and @AIatAMD teams, who got GLM-5.3 to 469 tok/s single-user decode with vLLM on 8× MI355X on @SemiAnalysis_ AgentX.
The run uses a disaggregated setup where vLLM handles prefill and TileRT handles latency-critical decode through vLLM's V1 connector interface.
1/2


Andy Luo retweeted

2 ways to win on OpenRouter, serving GLM5.3/MI355X:
1. Speed: TileRT hits 469 tps/user on AgentX, ~45% higher interactivity v. GB300/FP4: amd.com/en/developer/resourc…
2. Profits: $11.18/GPU/hr at 67 tps (SemiAnalysis AgentX, 60% utilization) => $11.18*24*265*8 = $560k profit/node/year


Andy Luo retweeted

We welcome more hardware manufacturers to join us in jointly optimizing inference performance, OSS forever!

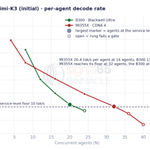
AMD MI355X now is close to Nvidia B200 on MiniMax-M3 serving.
Thanks to @AMD team. released dual technical blogs detailing full-stack ATOM + ATOMesh co-optimization for our 428B MSA sparse MoE multimodal base model.
• EAGLE3 speculative decoding for lower generation latencyCore upgrades:
• MSA-aligned Page-16 KV cache for 1M ultra-long context
• Layer-wise FP8 quantization avoiding vision/MoE precision drop
• Distributed P/D separation architecture for large-scale clusters
🔗 Blog 1: rocm.blogs.amd.com/artificia…
🔗 Blog 2: rocm.blogs.amd.com/software-…


Andy Luo retweeted

Agent workloads bring long contexts, bursty traffic, and frequent tool calls, creating new demands for AI serving.
Together with @AMD , we rebuilt the stack for Kimi K2.6 on AMD Instinct™ MI355X, with scheduler-aware multi-tier KV caching.
Up to 3.2× smaller p99 TTFT and 7.7% higher total-token throughput, with no accuracy tax.
Happy to see more Kimi running on AMD chips!
Tech blog: amd.com/en/developer/resourc…

Andy Luo retweeted

Great to see this out!
Worked with the team on bringing efficient large-scale RL post-training to MI300-class clusters — lots more coming 🚀
@linluo77 @lizli202503 @roaner

🚀 New blog: ROCm Support for Miles: Large-Scale RL Post-Training on AMD Instinct™ GPUs
Together with @AMD, Miles brings end-to-end RL pipelines to MI300/350-class clusters:
⚡️ Rollout generation dominates RL compute, and AMD’s HBM bandwidth directly addresses this bottleneck
🧠 AIME accuracy improved from 0.665 → 0.729 across training on Qwen3-30B-A3B with GRPO
💾 MI300X delivers ~1.1–1.3k tok/GPU/s rollout throughput
⏱️ Mean step time 388.5s on a single 8-GPU MI300X node (32×8 sampling, 8k response cap)
🔧 Multi-turn agentic training validated
... and more optimizations to come 🔥

Andy Luo retweeted

🚀 New blog: ROCm Support for Miles: Large-Scale RL Post-Training on AMD Instinct™ GPUs
Together with @AMD, Miles brings end-to-end RL pipelines to MI300/350-class clusters:
⚡️ Rollout generation dominates RL compute, and AMD’s HBM bandwidth directly addresses this bottleneck
🧠 AIME accuracy improved from 0.665 → 0.729 across training on Qwen3-30B-A3B with GRPO
💾 MI300X delivers ~1.1–1.3k tok/GPU/s rollout throughput
⏱️ Mean step time 388.5s on a single 8-GPU MI300X node (32×8 sampling, 8k response cap)
🔧 Multi-turn agentic training validated
... and more optimizations to come 🔥
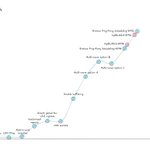
From 1 to 3,204 TFLOPS ⚡
FP8 GEMM optimization on AMD MI355X — pure HIP/C++, no assembly.
1→5 (LDS tiling)
5→30 (Matrix Cores)
30→507 (global→LDS)
507→1,166 (double buffer)
1,166→2,288 (multi-wave)
2,288→3,204 (8-wave ping-pong)
Exceeds hipBLASLt at 8K matrix.
Full blog: rocm.blogs.amd.com/software-…

Andy Luo retweeted
Day 0 support for Qwen 3.5 is here on AMD Instinct GPUs.
By providing Day 0 support on AMD Instinct GPUs with both SGLang and vLLM, we ensure that developers have the compute power and optimized software stack needed to run these massive, high-context models at production scale.
Learn how to get started → amd.com/en/developer/resourc…

Day-0 support for the Qwen 3.5 model on AMD GPUs, achieved through tight collaboration with the @Alibaba_Qwen team just in time for Chinese New Year's Eve. Support is available via both @sgl_project and @vllm_project .
With SGLang:
Launch rocm/sgl-dev:v0.5.8.post1-rocm720-mi30x-20260215
Inside container, run:
python3 -m sglang.launch_server \
--port 8000 \
--model-path Qwen/Qwen3.5-397B-A17B \
--tp-size 8 \
--attention-backend triton \
--reasoning-parser qwen3 \
--tool-call-parser qwen3_coder
With vLLM:
Launch rocm/vllm-dev:nightly_main_20260211
Inside container, run:
pip install git+lnkd.in/gw4k6mqE
VLLM_ROCM_USE_AITER=1 \
vllm serve Qwen/Qwen3.5-397B-A17B \
--port 8000 \
--tensor-parallel-size 8 \
--reasoning-parser qwen3 \
--enable-auto-tool-choice \
--tool-call-parser qwen3_coder
You can now run the following text/image/video input examples on Hugging Face:
huggingface.co/Qwen/Qwen3.5-…
huggingface.co/Qwen/Qwen3.5-…
huggingface.co/Qwen/Qwen3.5-…
Accuracy has been fully verified, and all AMD support code has been upstreamed.
The upcoming SGLang and vLLM releases will support Qwen 3.5 out-of-the-box on AMD MI300X, MI325X, and MI355X GPUs.
✅ Day 0 support of MiniMax-2.5 on AMD GPU
2 MI300X GPUs are all you need, instead of 4 Hopper GPUs, to run it in full context.
uv pip install vllm --extra-index-url lnkd.in/gJdnn3kJ
VLLM_ROCM_USE_AITER=1 vllm serve MiniMaxAI/MiniMax-M2.5 \
--tensor-parallel-size 2 \
--tool-call-parser minimax_m2 \
--reasoning-parser minimax_m2_append_think \
--enable-auto-tool-choice \
--trust-remote-code

Qwen3 Optimization on AMD GPU with SGLang, full blog: lmsys.org/blog/2026-02-11-Qw…


Run #openclaw (aka #clawdbot and #moltbot) with local Minimax-M2.1 on AMD Developer Cloud for free.
Check out the blog by @DuneDudeMahdi -
lnkd.in/g7az4G5q
How to run the new kimi-k2.5 on AMD GPU:
uv venv
source .venv/bin/activate
uv pip install vllm --extra-index-url wheels.vllm.ai/rocm/0.15.0/r…
vllm serve moonshotai/Kimi-K2.5 -tp 8 --mm-encoder-tp-mode data --tool-call-parser kimi_k2 --reasoning-parser kimi_k2 --trust-remote-code


How to improve LLM serving perf 3-10x with LMCache on AMD GPU for long-document QA and multi-round conversations - blog.lmcache.ai/en/2026/01/0…

122