
AI Safety Research @CAIS | Creator of Humanity's Last Exam (HLE)
Joined March 2025
- Tweets58
- Following82
- Followers207
- Likes93





Long Phan retweeted

Today we are open-sourcing 🥕Karotte, our framework for building RL environments.
We've used it for the past year to build MLE RL environments for frontier labs, and it's been hardened through 1M+ evaluation runs and red-teaming.


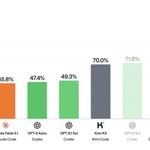
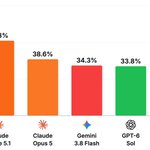
We have updated HLE-Diamond main results with max reasoning effort.

@polynoamial Thanks for the advice. We updated the main results with max for all models. GPT-6 seems solid

We are releasing HLE-Diamond, a refined subset of Humanity’s Last Exam (HLE), shaped by a year of refinement and input from various research communities.
Release notes: lastexam.ai/blog/hle-diamond

We are grateful for community review of benchmarks, but we hope Epoch applies more care to reviews like this in the future.
All of the HLE examples in this review are already fixed in HLE-Rolling, the continually updated fork of HLE we've been cleaning for the past year.
And some of them weren't errors to begin with.
nitter.cf/longphann_/status/2100…
[1/3]
We released the September 17 version of HLE-Rolling, a fork of Humanity's Last Exam that we continually update with feedback from the community. For the past year, we've been cleaning it with internal checks and feedback from outside experts. huggingface.co/datasets/cais…
It's been public for a while but I don't think many people know about it, so this is mostly a heads up. We think it's a very clean version of HLE at this point and hope people find it useful. If you find a bad question, please tell us.


TextQuests is a good out-of-distribution benchmark for AI in long-horizon, exploratory environments, in pair with HLE for reasoning.


AI capabilities in long-horizon, exploratory environments are improving fast. With clues, Claude Fable 5 and GPT-5.6 Sol now solve roughly half of the 25 classic text adventures on TextQuests, games that can take human experts over 30 hours to beat. A year ago, the best models solved just 4 to 5 games.


Long Phan retweeted

We created the AI Values Dashboard, which measures who AIs favor the most.
By popular request, we added a Sports Tier List, ranked by AIs from OpenAI, Anthropic, and DeepSeek.


Long Phan retweeted
What biases do AIs have? It turns out, AIs show strong favoritism toward specific people, countries, and companies. Our interactive AI Values Dashboard tracks who Claude Fable and other AIs favor most.
Keep scrolling to learn who is Fable’s favorite politician 🧵


Long Phan retweeted

Most AI investing happens downstream of the frontier: a capability emerges, a category gets named, and capital rushes in.
But by the time a category earns a clean box on a market map, the best builders have usually been living in the messy version for months.
Agents. Reasoning. RL environments. World models. AI for Science. Recursive self-improvement.
I call this frontier proximity: the ability to see what is becoming possible before it becomes consensus.
My frontier proximity ladder:
L0 Wrapper: uses today’s models.
L1 Reactor: reacts fast to releases, but roadmap is downstream.
L2 Anticipator: builds for where capabilities are going.
L3 Native: depends on a non-obvious frontier bet.
L4 Shaper: helps move the frontier itself.
The point is not that every company needs to train models.
Apps can have high frontier proximity if they understand what models will make possible next.
Infra can have high frontier proximity if it knows what future agents, multimodal systems, robotics stacks, or scientific workflows will need.
That is why we’re launching MoE Capital.
MoE stands for Mixture of Experts.
The idea is simple: build an AI fund around people closest to the frontier: frontier researchers, technical founders, AI-native builders, and seasoned operators.
We don’t want to be another AI fund with a newsletter-level understanding of the frontier.
We want to build the AI fund closest to the frontier.
More in The Information: theinformation.com/newslette…

Long Phan retweeted
Big news from @CAIS:
Devin Kim (formerly @xAI, @scale_AI) joins as President.
We're launching the @FrontierSecInst, a DC-based org bridging frontier AI and the National Security Enterprise.
Frontier AI is a national security technology. It's time to act like it. ⬇️