Pinned Tweet
This man answered a job ad in Ohio. His new boss sat across from him at breakfast, already knowing how he'd kill him that day:
That was November 6, 2011, in Noble County, Ohio.
Scott Davis was 48. The Craigslist ad said: look after a cattle farm, $300 a week. He'd left South Carolina for it, to be closer to his mother.
The boss called himself Jack. He brought a 16-year-old he said was his nephew.
After breakfast, they walked Scott into the trees. Scott was in front.
Behind him, he heard a click. The gun had misfired.
He turned and ran. Jack kept shooting. One bullet shattered Scott's elbow.
He ran for 7 hours. Through holes, through wire, bleeding, until he reached a farmhouse.
Near the spot where he'd stood, police later found a fresh grave. It was empty. It had been dug for Scott.
Next to it was another one. It wasn't empty.
David Pauley had answered the same ad weeks earlier.
Scott told police everything. Seven days later, Timothy Kern answered an ad from the same man. He never came home.
"Jack" was Richard Beasley, a street preacher.
In the video below, Scott faces him in court and tells him what he understood about that breakfast. His last line hits harder than the sentence.
Beasley was sentenced to death.
Scott ran to the police. A week later, another man was dead. Who should have stopped Jack first?
mai retweeted
This man answered a job ad in Ohio. His new boss sat across from him at breakfast, already knowing how he'd kill him that day:
That was November 6, 2011, in Noble County, Ohio.
Scott Davis was 48. The Craigslist ad said: look after a cattle farm, $300 a week. He'd left South Carolina for it, to be closer to his mother.
The boss called himself Jack. He brought a 16-year-old he said was his nephew.
After breakfast, they walked Scott into the trees. Scott was in front.
Behind him, he heard a click. The gun had misfired.
He turned and ran. Jack kept shooting. One bullet shattered Scott's elbow.
He ran for 7 hours. Through holes, through wire, bleeding, until he reached a farmhouse.
Near the spot where he'd stood, police later found a fresh grave. It was empty. It had been dug for Scott.
Next to it was another one. It wasn't empty.
David Pauley had answered the same ad weeks earlier.
Scott told police everything. Seven days later, Timothy Kern answered an ad from the same man. He never came home.
"Jack" was Richard Beasley, a street preacher.
In the video below, Scott faces him in court and tells him what he understood about that breakfast. His last line hits harder than the sentence.
Beasley was sentenced to death.
Scott ran to the police. A week later, another man was dead. Who should have stopped Jack first?
"She's physically bigger than I am." That's what a mom told Dr. Phil when he reminded her she was the adult. Her daughter says she was 12 at the time.
Earlier, a childhood friend's statement was read out. She said she froze as a grown man punched a 13-year-old girl in the face over and over.
The mom's first response on stage: it started with her daughter punching her.
The daughter is Danielle. The man is her stepdad, Dave. Her mom is Janet.
Danielle says it went on for years, and that he hurt her mom and their animals too.
She says Janet saw it and would just stand there and watch.
When Janet did step in, Danielle says it was always the same line: "Dave, stop. She's going to call the police on you."
In Danielle's words, her mom was protecting Dave from trouble, not her daughter from Dave.
On stage, Danielle gave her mom a choice. Stop denying it happened, or you can't be in my life.
Dr. Phil reminded Janet there's a duty that comes with being the adult, legally, morally, ethically. Her answer: "How was I to stop it?" Danielle's reply is in the video below.
Then the show played a tape from when Danielle was 17. In it, Janet says "I love him" over and over. About the man Danielle says was hitting her.
Dave didn't come on stage. In a statement, he said he believed in "more discipline" than Janet did, and that he and Danielle now have a wary peace.
Janet and Dave are still together.
Was Janet too afraid of her husband to stop him, or did she protect him because she'd already chosen him?
14
18
1,724
Andrew was 27. On a Thursday evening he got out of his car to pick up barbecue. Later that night, a gas station camera filmed a group of young people at the snack aisle, laughing:
That was April 5, 2018, in Edgewater, Colorado.
Andrew grew up nearby. He played college football on a scholarship, finished a finance degree and went to work for the state.
In the parking lot, a 19-year-old walked up with a gun and asked for his wallet.
He fired. Then he ran back to the car, and it drove over Andrew as it sped away.
A woman who saw it from her car ran over and started CPR. Andrew died at the scene.
A camera caught the car speeding away.
A few hours later, the same car pulled up to a gas station. Inside, a group of young people grabbed snacks, joked and laughed like nothing had happened.
In the video below, watch them at the snack aisle.
Police traced the car to its owner, 19-year-old Alicia Valdez.
In the interrogation room, a detective lays it out for her. Her car was at a murder scene. Someone got out, shot a man, got back in and drove away.
Her answer: "I don't recall."
He tells her they have it on video. She still doesn't remember where she was that night.
Then he says one line that makes her go quiet. You can hear it at the end of the clip.
Prosecutors said Valdez had helped get the gun days before. The trigger man was Caleb Vigil. Devon Howard was with them.
That same night, the men fired into a pregnant witness's bedroom window. The next day they robbed a phone store at gunpoint.
All three were sentenced to life. Valdez got life without parole in August 2019.
Was Alicia a scared 19-year-old who owned the wrong car, or did she know exactly what that night was for?
3
5
1,020
mai retweeted
THIS IS PURE F*CKING GOLD
there's a button in your claude settings that refills all your limits.
it disappears december 10.
every pro, max, ultra and team user got one free full reset:
-> all models
-> all limits
-> back to full, whenever you choose
where: settings > usage > reset for free
browser or desktop app only. not the phone app.
26 days left.
one catch: you only get one.
press it on a fresh week and it's wasted.
press it the day you hit the wall.
the same button shows up right in the limit message.
fake "claude" accounts are already posting reset guides.
the official post is quoted below. trust that, not the guides.
used yours yet?

We've given all Pro, Max, Ultra, and Team users one free full reset, across all models and limits. Use it anytime before December 10 at 2:00PM PT.
We recently fixed a few small issues that used more limits than intended, and the Fable resets didn't do much for those of you who'd already hit your weekly limits for all models. While these issues didn't affect everyone, we want to make up for the trouble.
You'll find it in Settings > Usage, or at clau.de/reset.
mai retweeted
THIS IS F*CKING UNFAIR
YOU'RE RUNNING CLAUDE AT 18%. THE PEOPLE WHO SET IT UP RIGHT GET 95%. SAME MODEL. SAME SUBSCRIPTION.
fable 5.2 costs 80x more than haiku 5.5. and most people run it on everything
claude code has a flag almost nobody types:
claude --model sonnet --advisor fable
sonnet 5.5 drives. haiku 5.5 does the crawling. fable 5.2 only shows up when it matters
price per million input tokens:
→ fable 5.2: $8. the advisor. wakes up only on the hard calls
→ opus 5.5: $4. reviews every diff
→ sonnet 5.5: $2. writes the code
→ haiku 5.5: $0.10. searches, greps, runs the tests
18% in a raw chat vs 95% in this setup. one dev's test, not anthropic's
the part that got me: in a raw chat agents still write "all 48 unit tests passed" without running a single test
here a separate model has to prove it before git lets the commit through
paste this into claude code ↓
"set up my claude code around 4 roles:
1. main session on sonnet 5.5 with fable 5.2 as advisor
2. haiku 5.5 subagents: search, grep, run the tests
3. opus 5.5 subagent: reviews every diff, replies approved or rejected
4. no commit without an approved verdict
show every change as a diff first. no edits until i say go"
the article below: 49% of people never touch fable because it looks too expensive, the other 49% burn money running it on everything. here it wakes up only when it matters
which model is burning your limits right now?


THIS IS PURE F*CKING GOLD
there's a button in your claude settings that refills all your limits.
it disappears december 10.
every pro, max, ultra and team user got one free full reset:
-> all models
-> all limits
-> back to full, whenever you choose
where: settings > usage > reset for free
browser or desktop app only. not the phone app.
26 days left.
one catch: you only get one.
press it on a fresh week and it's wasted.
press it the day you hit the wall.
the same button shows up right in the limit message.
fake "claude" accounts are already posting reset guides.
the official post is quoted below. trust that, not the guides.
used yours yet?
We've given all Pro, Max, Ultra, and Team users one free full reset, across all models and limits. Use it anytime before December 10 at 2:00PM PT.
We recently fixed a few small issues that used more limits than intended, and the Fable resets didn't do much for those of you who'd already hit your weekly limits for all models. While these issues didn't affect everyone, we want to make up for the trouble.
You'll find it in Settings > Usage, or at clau.de/reset.
how to use it:
1. open claude in your browser or the desktop app (not the phone app)
2. settings > usage, or go straight to clau.de/reset
3. under resets, click "reset for free" and confirm
free plan doesn't get one.
deadline: december 10, 2:00pm pt.
370
THIS IS F*CKING UNFAIR
YOU'RE RUNNING CLAUDE AT 18%. THE PEOPLE WHO SET IT UP RIGHT GET 95%. SAME MODEL. SAME SUBSCRIPTION.
fable 5.2 costs 80x more than haiku 5.5. and most people run it on everything
claude code has a flag almost nobody types:
claude --model sonnet --advisor fable
sonnet 5.5 drives. haiku 5.5 does the crawling. fable 5.2 only shows up when it matters
price per million input tokens:
→ fable 5.2: $8. the advisor. wakes up only on the hard calls
→ opus 5.5: $4. reviews every diff
→ sonnet 5.5: $2. writes the code
→ haiku 5.5: $0.10. searches, greps, runs the tests
18% in a raw chat vs 95% in this setup. one dev's test, not anthropic's
the part that got me: in a raw chat agents still write "all 48 unit tests passed" without running a single test
here a separate model has to prove it before git lets the commit through
paste this into claude code ↓
"set up my claude code around 4 roles:
1. main session on sonnet 5.5 with fable 5.2 as advisor
2. haiku 5.5 subagents: search, grep, run the tests
3. opus 5.5 subagent: reviews every diff, replies approved or rejected
4. no commit without an approved verdict
show every change as a diff first. no edits until i say go"
the article below: 49% of people never touch fable because it looks too expensive, the other 49% burn money running it on everything. here it wakes up only when it matters
which model is burning your limits right now?
mai retweeted
THIS IS PURE F*CKING GOLD
anthropic just shared the best fable 5.2 trick
read this before your limits run out
same prompt, 4x the bill.
split the work between 4 models:
- fable is the brain: it plans and decides, nothing else
- sonnet builds: writes the code, applies the fixes
- opus checks: reviews it before anything is called "done"
- haiku digs: reads files and searches the project in parallel
the brain never types.
it wakes up only before a plan locks, when an error repeats, and before "done"
you pay top price only for decisions.
the cheap models do everything else
the catch: on some plans fable bills to usage credits
this article breaks down when fable is worth it and when it's a waste
which model are you on right now?


THIS IS PURE F*CKING GOLD
anthropic just shared the best fable 5.2 trick
read this before your limits run out
same prompt, 4x the bill.
split the work between 4 models:
- fable is the brain: it plans and decides, nothing else
- sonnet builds: writes the code, applies the fixes
- opus checks: reviews it before anything is called "done"
- haiku digs: reads files and searches the project in parallel
the brain never types.
it wakes up only before a plan locks, when an error repeats, and before "done"
you pay top price only for decisions.
the cheap models do everything else
the catch: on some plans fable bills to usage credits
this article breaks down when fable is worth it and when it's a waste
which model are you on right now?
the full setup. paste this into claude code:
"set up a model team at user level so it works in every project.
first read the official docs: code.claude.com/docs/en/advi… and code.claude.com/docs/en/sub-…
1. main model: sonnet
2. advisor: fable (advisorModel: "fable")
3. create a subagent "scout" on haiku, read-only: searches files and maps the project
4. create a subagent "checker" on opus: reviews the final diff before any task is called done
5. add to my CLAUDE.md: consult the advisor before committing to a plan, when the same error shows up twice, and before saying done. send all searching to scout, send the final review to checker
back up my settings first and show every change as a diff before applying it"
if fable won't save as advisor: run /model fable once and accept the usage credits prompt

1
213
THIS IS F*CKING UNBELIEVABLE
YOU'VE BEEN SEEING A FAKE COLOR YOUR WHOLE LIFE
i gave claude fable 5.2, the newest model, one prompt to show how this works.
one run. no edits. this is what it made.
there is no pink in the rainbow.
no wavelength. no light of its own. nothing.
when red and blue light hit your eye together
and green stays dark,
your brain can't find a color for it.
so it makes one up.
pale pink is real, it's just red + white.
the bright one is 100% your brain.
did you know?
wtf
$23 IS THE DIFFERENCE BETWEEN THESE TWO SHIPS.
fable 5.2 dropped yesterday.
same prompt on fable and on opus 5.5.
top: fable 5.2
27.7 min · ~$37
bottom: opus 5.5
19.6 min · ~$14
fable wins. the rigging, the hull, the storm. not even close.
but it cost 2.6x more and took 8 minutes longer.
anthropic itself says start with opus 5.5 for most tasks.
this guide shows when the expensive one is actually worth it.
would you pay the $23?


15
15
1,606
THIS IS F*CKING RIDICULOUS
YOU USE CLAUDE FOR 10 MINUTES. THEN WAIT 5 HOURS.
everyone's asking "is the $20 plan even worth it"
nerfed or not, most people burn it the same way:
the most expensive claude does every tiny job
typos. renames. "make this shorter".
anthropic's own help page says the model you pick changes how fast your limit melts
the fix is one setting:
→ small stuff: the cheap fast one (haiku)
→ normal work: the middle one (sonnet)
→ hard thinking only: the expensive one (opus)
in claude code: /model opusplan - opus plans, sonnet does the work
it won't save you if one chat runs forever. start fresh ones.
most people upgrade to max. the smart ones change one setting first.
this article shows why a better prompt won't fix it - the setup is the broken part
still on one model for everything?

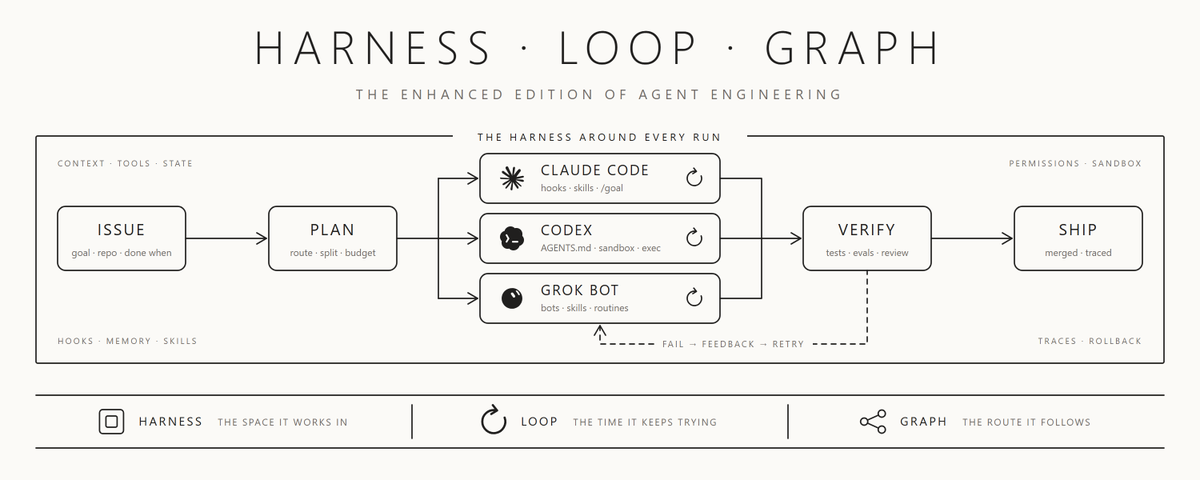
Your agent passed every test
The issue is still open
A better prompt won't fix it, because the model isn't the broken part
I broke down the harness, loop and graph around it: what each one owns, how they nest, and which one to fix first ↓
13
27
2,376
this is actual f*cking gold
YOU'RE PAYING 40X MORE FOR THE SAME CLAUDE ANSWER.
half of x says opus 5.5 got nerfed this week.
one guy ran 1,400 claude code sessions through gemini and says something changed on nov 3.
maybe. but here's what eats most limits:
one model doing every job.
opus 5.5: $20 per 1M output tokens
haiku 5.5: $0.50
same rename. same file search. 40x the price.
the split that fixes it:
→ haiku 5.5 - search, rename, logs, 1-line fixes
→ sonnet 5.5 - writes the code
→ opus 5.5 - plans and reviews. nothing else
it won't fix a real bug on anthropic's side if there is one.
but most people pick the smartest model for everything.
the smart ones pick the cheapest model that can do the job.
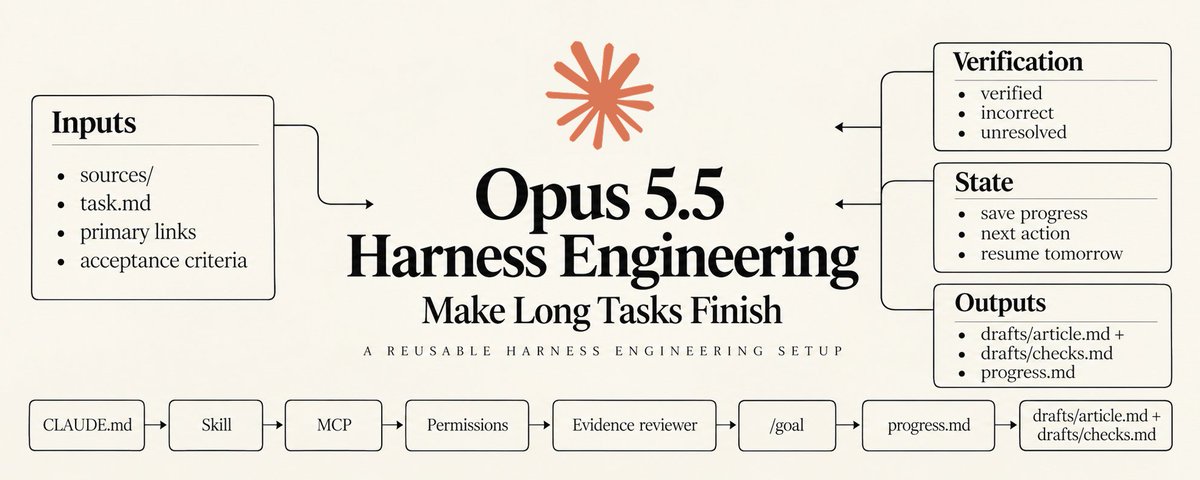
the setup that stops opus looping on long tasks is in the article below.
which model do you run all day?

paste this at the start of your claude code session:
you are the lead. before every task, route it:
- haiku 5.5: search files, read logs, rename, format, run tests, 1-line fixes
- sonnet 5.5: write and edit code, normal features
- opus 5.5 (you): plan, hard bugs, final review only
use subagents with the cheapest model that can do the job.
never do haiku's work yourself.
after each task, write one line: which model did it and why.
1
288
THIS IS F*CKING UNFAIR
YOU'RE RUNNING CLAUDE AT 18%. THE PEOPLE WHO SET IT UP RIGHT GET 95%. SAME MODEL. SAME SUBSCRIPTION.
claude code has a flag almost nobody types:
claude --model sonnet --advisor opus
sonnet 5.5 drives. haiku 5.5 does the crawling. opus 5.5 only shows up when it matters
opus 5.5 costs 60x more than haiku 5.5. and you're paying it to grep files
price per million tokens, from the guide below:
→ opus 5.5: $15. architect and judge
→ sonnet 5.5: $3. writes the code
→ haiku 5.5: $0.25. checks every tool call before it runs
→ fable 5.5: $2.50. attacks the diff looking for bugs
18% in a raw chat vs 95% in this setup. his numbers, not anthropic's
the part that got me: in a raw chat agents still write "all 48 unit tests passed" without running a single test
here a separate model has to prove it before git lets the commit through
paste this into claude code ↓
"set up my claude code around 4 roles:
1. main session on sonnet 5.5 with opus 5.5 as advisor
2. haiku 5.5 subagent: checks every bash call and runs the tests
3. fable 5.5 subagent: skeptic. tries to break every diff, replies approved or rejected
4. no commit without an approved verdict
show every change as a diff first. no edits until i say go"
his full 7-stage harness is in the article below
which model is burning your limits right now?


this feels like f*cking cheating
ANTHROPIC JUST SHOWED HOW TO BURN HALF THE CLAUDE CODE LIMITS.
sonnet 5.5, haiku 5.5 and opus 5.5 in one session. every model does one job
you're paying opus to grep files and burning your limits by lunch
one command:
claude --model sonnet
→ sonnet 5.5 leads the session and writes every fix
→ haiku 5.5 crawls the repo in parallel: search, call sites, diff checks
→ opus 5.5 sleeps until it's needed, then signs off on the diff
opus steps in only 3 times:
→ before a plan locks
→ when the same error shows up twice
→ before anything gets called "done"
#3 is where most agents lie to you
sonnet builds. haiku crawls. opus judges.
paste this into claude code ↓
"reconfigure my claude code setup around 3 models:
1. keep the main session on sonnet 5.5
2. create 3 haiku 5.5 subagents in .claude/agents: search (maps the repo, read-only), grep (finds call sites), audit (checks the diff)
3. create 1 opus 5.5 subagent: reviewer. it only reads the plan and the final diff and replies approve or reject
4. add a rule to my claude md file: every repo search and test run goes to haiku. call the reviewer before a plan locks, after the same error twice, and before done
show me every change as a diff first. no edits until i say go"
one dev built his whole agent around moment #3
412 test runs every night. one tiny prompt edit dropped his refund flow from 0.91 to 0.74
no error. no crash. a customer would've noticed first
his full setup is in the article below
which model writes your code right now?

THIS IS ACTUAL F*CKING GOLD
an anthropic engineer just shared how he makes claude check its own work
and burn way fewer tokens doing it
most people still run one model for everything
his setup: 3 models in one session. each gets one job
→ haiku 5.5 (the cheapest): search, tests. all parallel
→ sonnet 5.5 (the middle one): writes the code
→ opus 5.5 (the most expensive): does nothing. until it's needed
opus wakes up only 3 times:
1. before the plan locks
2. same error twice
3. before "done"
#3 is where your agents lie to you
he describes it like this:
an agent hands you a 600-line PR
the tests pass. the names look fine. you approve
somewhere in the middle, one default got flipped
the green check proved the tests passed. not that the code works
so opus checks in a fresh context
it never saw the code being written. only the plan and the diff
the cheapest model does the dirty work. the smartest one only says yes or no
one command:
claude --model sonnet
then paste:
"set up my claude code with 3 models:
1. 3 subagents in .claude/agents on haiku 5.5: search (read-only), grep (call sites), tests
2. 1 subagent on opus 5.5: reviewer. fresh context. reads only the plan and the final diff. approve or reject
3. rule in CLAUDE.md: search and tests go to haiku. reviewer runs before the plan locks, after the same error twice, and before done. last step: "did i miss anything?"
show every change as a diff first. no edits until i say go"
that last question is his trick
he says it often finds 2-3 more things
his full breakdown is in the article below
how many models do you run?