
Obsessed with Performance at https://nitter.cf/t.co/lhFiHlKPgK | @ycombinator F26
SF | Berlin
Joined February 2022
- Tweets29
- Following71
- Followers31
- Likes54
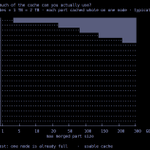


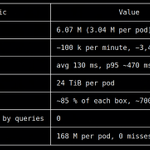


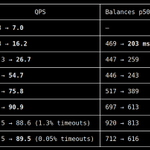


here's a tough one: HRW distributed network cache. two contradicting values: part size (larger parts for more performance) vs. max nvme usage. wtf for me super counter intuitive -> more nodes are even counter productive. anyone an idea for this?


ClickHouse on S3 tip: MV writes are sequential. parallel_view_processing=1 writes them in parallel. you can more than double the ingest throughput before inserts pile up in the pipeline. more importantly: read-your-writes halves. take care of sequential dependencies and memory.

beginning of last week we took out a project from the drawer. finally a customer wants 70TB for real-time apis in multiple regions. baseline was already okayish, compared to the hourly/daily batch jobs from other data warehouses.
we're not done yet: physics says 30ms

got alerted for an instance going crazy last night. turns out a potential customer ran a benchmark.
they moved on to sign this morning.

cross-region data availabilty between us-west-2 <-> us-east-1a. we serve real-time apis on large data sets around the globe close to physics.

ALT obsessiondb cross-region data availabilty
10k scans on a 4TB data set with active ingestion/merges on a $400 cluster with smart cache pinning. super predictable performance.
🤖 Made with AI

impact of metadata's proximity to your query engine. starts with the time you lose in sequential querying, ends with the max capacity of the cluster.

if you feel a pain and there is no drug for it, build it! likely you're not the only one with the same problem. there's not many excuses anymore to suffer it.
marcmacmac retweeted

Today we are launching @ObsessionDB, the realtime data warehouse for agents.
Your agents are hungry for data. Feeding them is getting expensive.
Your data warehouse wasn't built (or priced) for that.
We learned this the hard way. We scaled our last company to petabytes on ClickHouse and watched the infra bill go vertical.
So we built @ObsessionDB . The ClickHouse engine, rebuilt with compute and storage separated, so your infra scales with your agents instead of your bill.
100x faster and 20x cheaper than Snowflake and Databricks. Already live, processing trillions of rows a day.
Agents are just getting started...
agent2agent plain simple for multiple co-workers in several repos:
- mkdir agent-coms/
- ultracode + /goal
- tell claude/codex to discuss with and update the team
watch the magic happen 🍿
All the countless data-gold rotting around on broken table schemas, that noone dares to migrate or make any sense out of it. With Jev you can classify it on read time - a new generation of apps/features that harness it is incoming
marcmacmac retweeted

We just added Jev support to ObsessionDB/ClickHouse.
The interesting part isn’t just “LLM in SQL”, it’s that Jev is fast enough to make semantic queries feel like part of the database workflow.
You can analyze AI agent sessions on the go!
aiFilter(session, 'was the user frustrated, map('model','jev-1.13.0'))
or score frustration, success, intent, exposed credentials, etc.
At write time: turn meaning into columns.
At read time: ask new questions you never instrumented.
~50 rows/request, ~300ms in our current setup.
Feels like a new primitive for AI product telemetry.

Large scan queries in a compute-storage separated database are often limited by inter-node bandwidth, not cpu or memory. ObsessionDB's locality aware distributed cache reduces this traffic to less than 10%. Less waiting, more working -> faster queries, more performance per dollar
Just waiting for the PR getting merged to finally see ObsessionDB on benchmark.clickhouse.com. Spoiler: It's fast
