

matemático, assistant professor @uchicago
Joined November 2010
- Tweets814
- Following354
- Followers184
- Likes736
Pinned Tweet
This paper made me smile a lot while working on it, so I want to share a bit about it arxiv.org/abs/2405.09676.
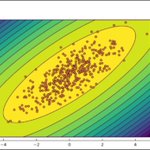
We draw a parallel story to the Eckart-Young Theorem (from numerical analysis) in stochastic optimization/learning problems.
(with Josh Cutler and Dima Drusvyatskiy)

Mateo Díaz retweeted

I regret to inform you that regardless of how broken academia is, you are still responsible for what you become during your PhD.
Your advisor can guide you. Your university can give you a degree. Neither can make you an independent thinker.
Stop chasing paper counts. Stop waiting for the perfect research direction. Stop confusing publications with scientific progress.
Stay curious. Question everything. Take ownership of your research.
The goal was never to become a paper-producing machine. It was to become a scientist.
Mateo Díaz retweeted

AI has helped resolve an important question in statistics. In the area of multiple hypothesis testing, the goal of controlling the false discovery rate (FDR) has been introduced in a seminal paper by Benjamini and Hochberg (1995). They also introduced a method (the Benjamini-Hochberg or BH method) and proved it controls the FDR. This method has been widely adopted in modern high-throughput science, including in genomics, astronomy, economics, etc. The paper has has garnered more than 130,000 citations to date.
However Benjamini and Hochberg showed FDR control only when the data for the individual tests are *independent*. In practice, these data are often dependent; a good example is data on genetic variants due to linkage disequilibrium. Later work has focused on extending the validity of the BH procedure, e.g., to a form of positive dependence by Benjamini and Yekutieli (2001).
The question of when the BH procedure controls the FDR has remained open. Over the last twenty years, many authors, including Reiner-Benaim (2007), Kim and van de Wiel (2008), Benjamini (2010), Sarkar (2023), Sarkar and Zhang (2025), have conjectured that the BH procedure controls the FDR for two-sided tests using any correlated Gaussian data. These authors have presented both theoretical and empirical evidence supporting, but not directly showing, the conjecture.
With the help of AI (specifically GPT-5.6 Sol Pro), I have settled the question in the negative: The Benjamini-Hochberg procedure does *not* generally control the false discovery rate at the desired level for correlated two-sided Gaussian tests. This was done by exhibiting a Gaussian factor model for which, at a nominal level alpha=0.01, the false discovery rate is proved to be FDR>0.0104.
There is a lot of interesting commentary to be made:
1. This result should be of interest to everybody in the field of statistics. Emmanuel Candes of Stanford University once called the false discovery rate and the Benjamini-Hochberg procedure "one of the two most important developments in statistics after 1950" (the other being James-Stein shrinkage). The present conjecture is probably the most central question about FDR/BH that was unresolved to date.
2. GPT-5.6 one-shot the problem after 90 minutes of reasoning, whereas with 5.5 I was not able to solve it even after iterating with multiple parallel agents for perhaps 20 hours. So the capability improvement is quite real. Exciting times to live in!
3. The argument is not especially surprising, but it does combine an asymptotic approach (standard for FDR analysis, see e.g., Genovese and Wasserman, Efron, etc) with a numerical certificate in a way that would be pretty non-standard in the field. Once we have the specific example, then straightforward simulations also support that the false discovery rate is indeed higher than the nominal value (see attached fig).
4. The current degree of violation over the nominal level is relatively small (0.104 vs 0.1). So the importance of this result is mainly conceptual. The practical implications remain to be determined.
Overall, an exciting development! Preprint is available here (faculty.wharton.upenn.edu/wp…) and will be on arxiv tonight; supporting code is here (github.com/dobriban/BH).


Mateo Díaz retweeted

Today, we share a breakthrough on the planar unit distance problem, a famous open question first posed by Paul Erdős in 1946.
For nearly 80 years, mathematicians believed the best possible solutions looked roughly like square grids.
An OpenAI model has now disproved that belief, discovering an entirely new family of constructions that performs better.
This marks the first time AI has autonomously solved a prominent open problem central to a field of mathematics.
Mateo Díaz retweeted

New paper studies when spectral gradient methods (e.g., Muon) help in deep learning:
1. We identify a pervasive form of ill-conditioning in DL: post-activations matrices are low-stable rank.
2. We then explain why spectral methods can perform well despite this.
Long thread

Mateo Díaz retweeted

NEW PAPER ALERT 📢 Score-based diffusion models are powerful—but slow to sample. Could there be something better? Drop the scores, use proximals instead! We present Proximal Diffusion Models (ProxDM), a faster alternative both in theory* and practice. Here’s how it works 🧵(1/n)

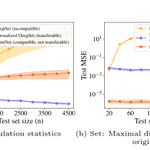
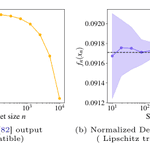
When does the performance of an ML model transfer across dimensions?
arxiv.org/abs/2505.23599
Kudos to my terrific collaborators Eitan Levin, Yuxin Ma, and @SoledadVillar5.
🧵(1/n)
Interestingly, the way in which we identify low-dimensional objects with high-dimensional objects and the choice of the norm for continuity play crucial roles. The task of interest has to be aligned with these choices; otherwise, transferability might fail.
(15/n)

1
128