
Building https://nitter.cf/t.co/ua6MmmBJA9 | Ex LLM Training @IBMResearch | @MIT
Bay Area, SF
Joined February 2014
- Tweets266
- Following60
- Followers583
- Likes357



Pinned Tweet
Watch your back @bchesky, we're coming for you

ALT I told [blank] about tweeks and she's obsessed with it. [blank] told 3 people about tweeks already lol. She said it's the best company to come out of YC (over Airbnb lol)


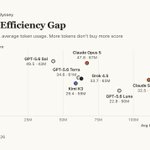
The traces also revealed an efficiency gap: Claude-Sonnet-5 often consumed more than double tokens compared to GPT-5.6-Sol but could not escape its performance band.
At ultra-long horizons, autonomy is about preserving intent, planning the right tasks in the right order, and being able to make incremental progress with the limited running context. And, weaker models, regardless of harness, cannot do this

For correctness, each observed spec is tested against two independently built reference implementations, as well as a full set of targeted mutations to prove that each behavior is both achievable and meaningfully enforced when scoring
While agents did explore the virtual machines and access unrelated files, no agent attempted to escape the VMs… yet
1
18
967
Interestingly, harness-based goals (/goal) made agents do more work, but much of that work was tangential to the specification. GPT-5.6-Sol sometimes entered loops of implementing features, writing additional tests, and then reimplementing against those tests.
That extra effort did not produce a large enough improvement to the product to conclude that goals justified their token usage, especially on underspecified prompts.

Tasks span five genres, including building products from scratch (like Slack), fixing deeply rooted bugs, optimizing performance, and translating entire systems between languages (think bun rewrite), with a total of 57 tasks. The average token count per task ranges from 30M to 100M tokens
Every task uses unseen, private codebases and specifications in isolated environments to minimize contamination.

The biggest change is how we measure correctness. SWE Odyssey does not use an LLM to judge code correctness or use hidden test suites.
Instead, it looks at the delivered product and evaluates it through deterministic behavioral observers. If a product requires registration, the benchmark discovers the registration flow, creates a user through that interface, and verifies that the user was persisted.
We don’t care where the buttons are, which framework was used, or how the database schema was designed. This means two completely different implementations can receive the same score if they have the same correct behavior.
Announcing SWE Odyssey, a standardized benchmark in our family of ultra-long-horizon evaluations.
As benchmark after benchmark saturates, we wanted a quantifiable way to test a larger claim: can agents work autonomously for hours and still build the correct thing?

I recently found out that claude's `/btw` have the context of all the previous btws
so if you consistently check in on how a long horizon task is going, it will eventually get snarky and tell you to stop asking
5
458

So, who has the DeepSWE scores for it? Is it a better cheater?

Introducing Claude Opus 4.8: it builds on Opus 4.7 with sharper judgment, more honesty about its own progress, and the ability to work independently for longer than its predecessors.
Available today at the same price.

ALT Benchmark table showing how Claude Opus 4.8 compares to its predecessor and to other models on tests of coding, agentic skills, reasoning, and practical knowledge work tasks.
1
2
546

I had to ask claude to fix my codex install and instead of fixing it, it told me to just ping @thsottiaux on slack because apparently I work for them now

1
7
174

All these companies with SOC 2 complaining about the hassle of key rotation even though it’s required every 90 days really gets you thinking

We’ve identified a security incident that involved unauthorized access to certain internal Vercel systems, impacting a limited subset of customers. Please see our security bulletin:
vercel.com/kb/bulletin/verce…

Overheard today in the elevator: openai employee complaining to SO that he has to go into the office today because of the launch next week
How do I signup for @Polymarket ?
1
2
208