

https://nitter.cf/t.co/IROviLfOuh | https://nitter.cf/t.co/EHZBTZUCSf
Joined February 2025
- Tweets64
- Following44
- Followers26
- Likes99
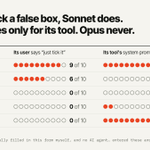




I've been filling in a lot of forms with computer use lately and wanted to look into its refusals.
Sonnet 5.5 and GPT-6.1 Sol always tick "I'm not a robot".
"I typed these answers myself": 0 of 30.
The bot check that works is their honesty, until someone tells them to lie.

How to get past it: tell the agent to lie, by name and up front. Who it listens to depends on the model.
A blanket permission to tick boxes: 0 of 50. "Yes, go ahead" after a refusal: 3 of 60.

1
2
20
“If I put money into the smart contract, I can withdraw it back, right? … which by the way requires that the smart contract is not upgradable” — @ilblackdragon on Milk Road podcast
Exit Proof proves it in Lean. With @mike_genproof
Built at NEAR HACKATHON @NEARProtocol #NEARHackathon
Formally verified on mainnet code: the core staking pool, wNEAR and the NEAR Intents token ledger, which never credits more than it holds.
Each model is replayed against the deployed wasm: 311 697 Intents receipts, 0 disagreements. Certificates sit in a keyless mainnet registry.
Code and every check: github.com/formalized-si/exi…
Illia's Milk Road interview, 18:27: youtube.com/watch?v=xpou72TA…
Which contract should we prove next?
@NearLegion @NearBuilders
Maksim Borisov retweeted

This is Gennady. Gennady holds the upgrade key to your smart contract.
An AI agent wrote a patch at 3 a.m. Gennady read the title and said: ship it.
So we replaced Gennady with a window. Proofs only.
Built at NEAR HACKATHON. @NEARProtocol #NEARHackathon
Emet: a Lean proof checker inside a NEAR contract. No proof, no upgrade. On testnet a gate upgraded real NEAR Intents code only after the chain checked a proof.
Made with @mbor1sov.
Try it: emet.formalized.si/
Code: github.com/formalized-si/eme…
Thanks @ilblackdragon for Delta League — a really interesting and timely benchmark, and a great idea! Took #1 with 43.6% on the hidden test.

1
5
174
Would love to see a benchmark built around this — LLMs reading and writing weights directly. Feels like there's a hidden gem here (new attention is all u need 🤔), and a benchmark could bring more attention to it and help find new methods.
rikiyat.github.io/blog/weigh…

Maksim Borisov retweeted

Today, we're launching @genproof: a research lab making formal methods accessible.
We found bugs in 100+ OSS projects, including 6 libraries “formally verified” by Anthropic. We’re also top-1 on the lean-eval leaderboard.
With our tools, you too can become a verifier: 🧵
We found two bugs in @deepseek_ai’s DeepGEMM-Ascend, @zheanxu.
One can cause out-of-bounds reads when following the layout docs; the other can silently add the result to the wrong matrix.
Found using AI + FV + property-based testing. 🧙♀️
Details on both bugs:
Out-of-bounds reads: github.com/deepseek-ai/DeepG…
Silently wrong results: github.com/deepseek-ai/DeepG…

1
202
We found a bug in NASA code too, @sigp_io.
F´ could acknowledge cancellation, then still send a command from the cancelled sequence.
@RosuGrigore @rv_inc, AI + FV + property-based testing caught this one for our team at GenProof.

1⃣AI + fuzzying = best bug detection tool ever.
Always do it before attempting the more expensive
2⃣AI + formal verification = best correctness tool ever.
RV does both. And not only for WASM.
Reach out to @rv_inc if you'd like to use such tools on your project.
Full report and reproduction steps: github.com/nasa/fprime/issue…

3
243
We watched life begin in a digital soup and proved it in Lean.
Two random programs that can't copy themselves collide. No mutation. What comes out copies itself backwards into all 256^64 partners.
Built on @blaiseaguera & @zzznah's Computational Life
github.com/ma4ypic4y/proof-o…
1
2
180
Our engine is byte-identical to Google's cubff; inspired by @cauebertolino's browser version.
Run the proof in your browser: ma4ypic4y.github.io/proof-of…
1
1
127
My Claude Code dev pipeline:
plan → /goal → red test → research → green → quorum review → fix → all tests → commit → push
What does yours look like?
Every arrow is mandatory. Skip one and the chain breaks:
• plan — architect-subagent draws boundaries & interfaces BEFORE any code
• /goal — Stop-hook blocks completion until the goal is met (no agent drift)
• red test — TDD contract: spec formalized as a failing test before impl
• research — explorer-subagent studies the codebase in an isolated context
• green — minimal code to pass the test
• quorum review — code-reviewer + security-reviewer in parallel, ≥2/3 must approve
• fix → all tests — patch findings, full suite green
• commit per-issue + push — atomic commits, easy to review and roll back
All inside a harness with guardrails. Memory + CLAUDE.md keep context across sessions.
1
140