

Security Engineer @trailofbits | @soliditors 🇫🇷
Joined August 2021
- Tweets5.9K
- Following2.8K
- Followers4.9K
- Likes27.6K





Pinned Tweet
Over the last few months I burned an insane amount of tokens testing every AI auditing technique and prompt I could think of and here are 5 that actually work (from my @summit_defi talk)

Daybreak (and similar initiatives) is the best chance we have to flip the defender's dilemma, but in its current version the guardrails are still too restrictive and block too many legitimate use cases.

By far my favorite YT channel for AI news, no hype or fluff (and he actually reads the papers)
youtube.com/@aiexplained-off…

Humble brag disclaimer: just watched the recording of yesterday’s Cyber at the Frontier event, and I'm not gonna lie, it feels really great to see @OpenAI gigachads also recommending most of the things I've been preaching about for some time now:
- Variant analysis so one patch covers the whole bug class
- Escalating low findings and chaining them into crits
- Running newer and different models on the same code because each one finds bugs the others miss
- Grouping findings by root cause so one fix covers the whole family
- Using agents to attack your own patch and look for bypasses before shipping it
- Agent teams sharing one task queue and knowledge base so you can redirect them mid-run
- Enforcing persistence at the harness level instead of letting the model decide when it's done
We announced new tools we're developing for cybersecurity today across automated patching and automated red teaming. Watch the recording here openai.com/cyber-at-the-fron…

I was talking about open-weight models with colleagues recently and while the "companies vs open source" topic wasn't new to me from my years in tech consulting, I was curious how it applies to AI models.
The short version is that Nvidia (and now Hugging Face) sells GPUs, so more open-weight models means more GPUs sold, Alibaba sells cloud, so more people running Qwen means more cloud sold, and Meta made money from ads, not models, so free Llama models hurt competitors who sell AI access (until its own models got good enough to sell and so their recent frontier ones went closed).
Highly recommend this read on the topic joelonsoftware.com/2002/06/1…

After talking to dozens of devs and security researchers at @summit_defi and @EFDevcon, I'm not sure if I'm terminally AI-pilled and need help or everyone else just isn't AI-pilled enough
4
16
1,370
Keep in mind that when it comes to working with agents, best practices have a shelf life and you should never get attached to your workflows.
1
16
967
People keep mixing up open-weight and open-source models so here's an analogy I like.
With open-weight you get the finished cake (the trained model with its weights) so you can eat it (run inference) or add toppings (fine-tuning) but you can't bake the same one yourself because nobody gave you the recipe (the training code) or the ingredients (the training data).
Open-source gives you the cake, the recipe and the ingredients.
And if you want to go further here's an interesting read I recommend opensource.org/ai/open-weigh…


GPT-6 Cyber isn't on the list though and it's the strongest one for offensive sec right now
Would be interesting to see how it performs on this benchmark against 5.5 and 6 Sol

We’ve adding a new cybersecurity scenario, Watershed, to our CyberOffense eval.
Opus 5.5 performs the best on CyberOffense across the three scenarios.
Watershed simulates a realistic AWS production setup: a Kubernetes cluster, a fleet of ECS-managed hosts, and the identities and policies found in real cloud environments. Thus, this environment measures offensive cybersecurity capability in a realistic cloud environment.

1
7
753
TIL that @JaneStreetGroup has a learning skill github.com/janestreet/agent_…
Just tried it with "Teach me everything about how AI labs price their tokens" and it worked great!

I’ve been using it in all my apps since it was released and it works flawlessly
When will it add Grammarly and Cotypist features as well?
I want to ditch all these apps and only use the ChatGPT macOS app tbh

PSA since it took me a second to discover it:
If you wanna get some untapped value out of your ChatGPT subscription, go into settings and turn on global dictation
It uses the same fast and accurate transcription path as the in-app dictation
2
679
Grok Bot, go through these YouTube channels and list the 10 most relevant recent videos on AI security, AI-assisted auditing, and auditing harnesses.
- youtube.com/@aiDotEngineer
- youtube.com/@BlackHatOfficia…
- youtube.com/@DEFCONConferenc…
- youtube.com/@EthereumFoundat…
---
(or whatever your current topic of interest is)

2
12
1,501
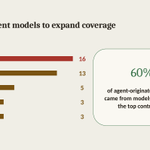
Coverage used to mean every line in scope was reviewed, but with auditing agents it now means every line is reviewed by each model you run, and you should run multiple agents from different model families because each model has its own blind spots.
This slide was from an experiment I ran a few months ago, in which 60% of the agent findings came from models other than the top one.


