

Post-doc at Cornell Tech
New York
Joined November 2021
- Tweets335
- Following860
- Followers2.4K
- Likes551




Pinned Tweet
⌘C ⌘V: Introducing Copy-Paste Language Models!
CPLMs learn to copy tokens better, improving downstream accuracy, CoT, long-context performance, and memory-efficiency for RAG at <3% overhead
PS: they (partially) mitigate the LM head bottleneck
Paper: arxiv.org/abs/2610.19247

Nathan Godey @COLM 🌉 retweeted

On the zeroth order lm training stuff:
It's cool that people try stuff instead of only reading and dooming. But i feel the need to curb the enthusiasm on this one a little. Two things:
(1) methods in the genetic-algo and fwd-diff categories, which imo these fall in, is established that they are fine for smaller parameter counts but fall off hard as parameter space increases. It's not necessarily raw param count that matters here but "intrinsic" size. This is the whole point of backprop: few outputs many params.
(2) loss 4.2 for LM is very high even for a 30M parameter model. Go a bit higher and you are at learning token unigram distribution. This means for this score not much interesting/difficult learning has to happen yet.
Again it's fine to rediscover things like this from first principles. In fact it's the very best way to learn and i recommend it; i spent a lot of time learning like this myself! But now with social media hype amplification and crazy vcs and journalist attention that our field gets, i do feel the need to be a bit more cautious with communication and there to be "old pessimist" voice like mine in the room to.
(But unlike some other old pessimist voices, if i turn out to be wrong I'll happily admit it and cheer on =)

Nathan Godey @COLM 🌉 retweeted

1/Remember the Pointer Networks?
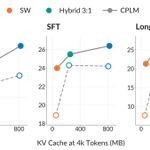
A sliding-window Transformer with a 256-token window just matched full-attention perplexity with 12x less KV cache memory—and jumped from 14.3% to 99.4% on 64k needle retrieval.
Here is how copy-paste heads fix a hidden gradient bottleneck in LM heads: 🧵

Nathan Godey @COLM 🌉 retweeted

Looped Transformers are a hot topic these days
And these 10 new papers are really worth your attention.
▪️ Recurrent Looped Transformer
▪️ Looped Prediction Transformer (LPT)
▪️ Recursive Multi-Agent Systems (based on looped transformer)
▪️ Loop Flow Transformers (LiFT)
▪️ Looped Diffusion Transformer
▪️ LAST: Looped Audio Spectrogram Transformer
▪️ LoopCD
▪️ Hyperloop Transformer
▪️ OperLoop
▪️ LoopQuant
Here is our quick guide to what they are, how they work and when to use each.: turingpost.com/p/10-looped-t…

Nathan Godey @COLM 🌉 retweeted

Great work!
It's fantastic to see that the direction (using pointer network to fix the softmax bottleneck) we proposed three years ago has been shown to be super helpful after scaling up!

⌘C ⌘V: Introducing Copy-Paste Language Models!
CPLMs learn to copy tokens better, improving downstream accuracy, CoT, long-context performance, and memory-efficiency for RAG at <3% overhead
PS: they (partially) mitigate the LM head bottleneck
Paper: arxiv.org/abs/2610.19247
Last Friday we set a (pending) record for the NanoGPT speedrun improving by 11.3% over the previous best time!
It's by far the largest architecture-centric improvement since Dec 2024, and it does not use extra n-gram tricks or more CPU compute
Paper coming soon 😊

👀 Paper thread dropped: nitter.cf/nthngdy/status/2111084…
⌘C ⌘V: Introducing Copy-Paste Language Models!
CPLMs learn to copy tokens better, improving downstream accuracy, CoT, long-context performance, and memory-efficiency for RAG at <3% overhead
PS: they (partially) mitigate the LM head bottleneck
Paper: arxiv.org/abs/2610.19247
(cc @prajdabre)
btw CPLMs are reminiscent of pointer networks (cc @Smerity @OriolVinyalsML) and close in spirit to past work from @Haw_Shiuan @andrewmccallum, so shout-out to them :)
Our contribution is scaling the idea and showing its deep connection to the LM head gradient bottleneck

Nathan Godey @COLM 🌉 retweeted

Windows users, we apologize for ⌘, but ¯\_(ツ)_/¯
Cool new work from Nathan. Simple, lightweight, and a lot of impact. Two things not to miss within the great results: (a) CPLM allows KV sliding window without performance loss; and (b) mitigates much of the softmax learning bottleneck issue
⌘C ⌘V: Introducing Copy-Paste Language Models!
CPLMs learn to copy tokens better, improving downstream accuracy, CoT, long-context performance, and memory-efficiency for RAG at <3% overhead
PS: they (partially) mitigate the LM head bottleneck
Paper: arxiv.org/abs/2610.19247
Nathan Godey @COLM 🌉 retweeted

Yet another banger paper from Nathan :)
It's been a lot of fun hearing day after day about how powerful his new Copy-Paste Language Models are despite their simplicity, and how effective they are at handling long contexts
⌘C ⌘V: Introducing Copy-Paste Language Models!
CPLMs learn to copy tokens better, improving downstream accuracy, CoT, long-context performance, and memory-efficiency for RAG at <3% overhead
PS: they (partially) mitigate the LM head bottleneck
Paper: arxiv.org/abs/2610.19247
Many thanks to my great co-author @yoavartzi! This work was made possible by both Empire AI and @cscsch
Also thanks to @ch272h and @giomonea for the great discussions :)
Check out the paper: arxiv.org/pdf/2610.19247
Checkpoints & inference code: huggingface.co/collections/n…
And to learn more about the LM head gradient bottleneck, check our thread and COLM paper:
nitter.cf/nthngdy/status/2032172…
