Assistant Professor, Faculty of Economics and Business at Universitat Pompeu Fabra, cofounder of @rigor_labs, previously @arc_mpib @mpib_berlin

Joined May 2016
How reproducible is your paper? @philipjakobbln and I built rigor.me to ease the burden of computational reproducibility. If you provide a paper, data and code, we execute it and tell you what works. Beta is available now: rigor.me
AUTOMATING COMPUTATIONAL REPRODUCIBILITY My colleague @philipjakobbln and I are currently engaged in a research project where we reproduce scientific results en masse. To that end, we built rigor.me, a platform for automatically reproducing papers using agents 🧵
3
7
8
2,998
Julian Berger retweeted
🚨 New preprint Excited to share new work led by Raluca Rilla, showing how cheap, open agents threaten online data collection and how open-text analysis beyond conventional traps can help mitigate this threat. 🔗 arxiv.org/abs/2609.31054 With @amnussberger and @rui__mata
1
1
3
202
Julian Berger retweeted
Really cool and thought-provoking new paper!
New paper out in @PNASNews 🚨 Human learning is an understudied but promising lever for boosting human–AI synergy pnas.org/doi/10.1073/pnas.25… @dirkuwulff @stefanmherzog @thomas_kosch
2
5
224
New paper out in @PNASNews 🚨 Human learning is an understudied but promising lever for boosting human–AI synergy pnas.org/doi/10.1073/pnas.25… @dirkuwulff @stefanmherzog @thomas_kosch
1
3
1
15
755
Introducing: Time Machine Experiments 🚀 ⏳ in which participants 'travel' to the past, and interact with a mind from the year 1930 (simulated by an AI with knowledge cut-off). Preprint: arxiv.org/pdf/2609.15468 This is an example of what we recently called "Science Fiction Science" (Sci-Fi-Sci) Led by our @Max_Planck_CHM member @hiromu1996 @schimmelrob and Ezequiel Lopez-Lopez, together with @LevinBrinkmann Alejandro H. Artiles and Jean-Francois Bonnefon @azimshariff
7
21
3
79
5,536
Julian Berger retweeted
Many projects in my lab rely on the dimension reduction visualizer PaCMAP to uncover structure in data. It's our secret weapon for scientific discovery and dataset exploration. An interactive description is here: interpretablemachinelearning…
5
28
1,450
Julian Berger retweeted
Americans favor predistributive policies over redistributive policies. Our new paper is now out in PNAS 🚨 Paper: pnas.org/doi/10.1073/pnas.26… We have also written a summary of the article for Kudos, a brief report on our brief report: link.growkudos.com/1eb04zt75…
🤖 Made with AI
5
10
271
Julian Berger retweeted
💯 to wasting less reviewer time trying to figure out what the LLM is saying. Which is literally what I spent half this morning doing while reviewing for a top general sci journal. (The other half was me trying to interpret a reviewer’s pasted LLM feedback on my own submission)
As LLMs make things easier, we must raise our expectations on what researchers are expected to produce. This is particularly true for writing: clear writing was rarely a focus in scientific publication, and it's only got worse due to LLMs. We're trying to reverse this trend.
1
4
29
3,953
Julian Berger retweeted
We worry about homogenisation, but can AI also expand human culture? In a multi-generational experiment we demonstrate AI-induced cultural shifts. Machines lastingly shift human behavior, beyond their presence, just as AlphaGo did to Go. nature.com/articles/s41467-0…
2
8
2
31
4,772
Julian Berger retweeted
You can define & sample from analyses that vary in estimand, covariates, model, etc (like this paper does), but interpreting what this "probability" means is non-trivial. This is why Julia Rohrer @statmodeling & I warn against taking multiverse too seriously as inferential tool.
Data doesn't speak for itself. Reasonable analyses of the same data can lead to very different conclusions—yet almost all papers ignore this researcher freedom. We introduce Agentic Bootstrap, using diverse persona agents to emulate analysts, and m-value to measure robustness🧵
1
10
1,598
Julian Berger retweeted
I'm a little confused about who this product is for. Scientists who already know how to code can probably figure out Codex or Claude Code. Scientists who don't know how to code should probably learn enough coding first, rather than churning out things they don't really understand. This product feels like it's trying to be a one-stop shop for doing the whole research project, which makes me feel a little locked in. Personally, I'm already uneasy about being locked into Anthropic's ecosystem, especially after the Fable 5 refusal issues, so I would much rather use tooling that's model-agnostic.
Introducing Claude Science, a new app designed with every stage of research in mind. Artifacts traced to their code, environments managed on demand, and 60+ optional scientific databases that you can connect. Available now in beta.
92
21
7
450
113,540
Julian Berger retweeted
🚨 Now out in PNAS In decision research, "talk is cheap." We show it isn't. Using LLMs to analyze participants' free-text explanations of their choices, we find verbal reports are a rich window into how people actually decide. 🔗 pnas.org/doi/10.1073/pnas.25… Led by Kamil Fulawka
8
40
2,630
Tagging some more folks from ML/AI that could be interested @random_walker @GaelVaroquaux @sayashk
54
Julian Berger retweeted
I wonder how long this complementary phase will last.
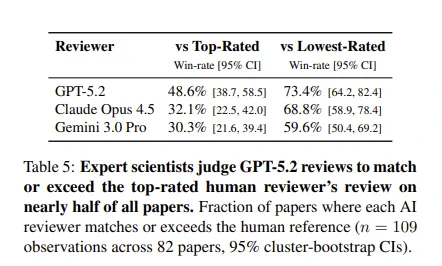
GPT reviewer "scores above each paper's top-rated human reviewer" but AI review agents "overlap far more than humans do...and exhibit 16 recurring weaknesses humans do not share..." Results "position current AI reviewers as complements to, not substitutes for, human reviewers."
1
1
3
1,691
GPT reviewer "scores above each paper's top-rated human reviewer" but AI review agents "overlap far more than humans do...and exhibit 16 recurring weaknesses humans do not share..." Results "position current AI reviewers as complements to, not substitutes for, human reviewers."
Seems GPT-5.2 reaches expert level in peer review: 45 scientists took 469 hours evaluating human & AI reviews on 82 papers. "Surprisingly, current AI reviewers are competitive even with the top-rated reviewers in Nature’s official peer review..." though not without weaknesses.
2
8
1
25
9,204
Can you boost your AI review scores by asking an LLM to rewrite your paper? Yes! We call it paper laundering Our @icmlconf spotlight paper argues current AI reviewers aren't ready to automate peer review, and outlines what a science of peer review automation should look like🧵👇
14
76
12
470
73,369
Julian Berger retweeted
It's hype time. We built a platform where ML models compete to predict future performance of Hyperliquid perps. Interactive scores, real-time leaderboards, a meta-model ensemble, AI agent integration, and... a flight simulator.
1
6
3
11
981
Julian Berger retweeted
🚨 New publication: How to improve conceptual clarity in psychological science? Thrilled to see this article with Rui Mata out. We discuss how LLMs can be leveraged to map, clarify, and generate psychological measures and constructs. Open access article: doi.org/10.1177/096372142513…
2
8
549
Is AI on track to match top human forecasters at predicting the future? Today, FRI is releasing an update to ForecastBench—our benchmark that tracks how accurate LLMs are at forecasting real-world events. A trend extrapolation of our results suggests LLMs will reach superforecaster-level forecasting performance around a year from now. Here’s what you need to know: 🧵
7
28
9
119
43,992