

The open source training platform for continuously improving agents and models
London & San Francisco
Joined January 2026
- Tweets386
- Following6
- Followers739
- Likes780





Pinned Tweet
Overmind turns anyone into an AI lab.
• Builds a context graph from code and traces
• Curates training and eval datasets
• Evaluates prompts and models
• Trains smaller, specialized models
github.com/overmind-core/ove…
Train your model on Overmind, then serve it there.
Dedicated GPUs for the models you train, with the option to scale to zero when idle.
An addition to our serverless inference.

Yesterday a customer asked us for a feature we hadn't shipped yet. So like the cracked founders we are we pulled an all nighter and got it deployed!
@OvermindLab now offers dedicated inference for your models.


How do you define "good" for an agent?
How do evals stay honest when the agent changes?
@freymehta answered questions all day. Thank you to everyone who tried Overmind and asked the hard questions.
Onwards.

spent launch day in the @ProductHunt replies with builders and founders actually trying overmind 🚀
skeptics asking how you even define “good” for an agent. a founder going four rounds deep on how the training loop works. builders poking at how evals stay honest when the agent changes underneath them. a few of those threads are already shaping what we build next
we landed #2 product of the day, just shy of the top spot, which was a lovely bonus on an already great day. by the evening we were all glued to the leaderboard and i was back in 2016, refreshing my youtube channel until it hit 1,000 subs!!
huge shout out to @samsmallmind for leading the whole launch, and to claude for turning the day into this little video (it would not stop adding pixels!!) 👇
Start here: docs.overmindlab.ai/tutorial…
The prompt connects Overmind to your coding agent.

What does it mean to break Big Tech's grip on enterprise AI?
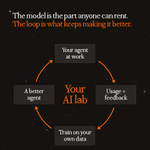
• When a company rents an AI model, rivals can rent the same one.
• The edge comes from training AI on how it's used.
AI labs do this. Now a company can too.
Overmind turns any company into an AI lab.

ALT Headline: The model is the part anyone can rent. The loop is what keeps making it better. Below, a loop of four boxes joined by orange arrows: your agent at work, usage and feedback, train on your own data, a better agent, then back to the start. In the middle: Your AI lab.


Thanks to @iamVictorDey and @Forbes for the write-up.
Full piece here: forbes.com/sites/victordey/2…
Overmind retweeted
Overmind is live on Product Hunt! 🚀
Some big companies have trained their own models this year.
That took an ML team. Most companies don't have one.
They do have coding agents though. So Overmind lets those agents do the ML team's work.
Live: producthunt.com/posts/overmi…

ALT Black starfield with white pixel flowers along the bottom. Small orange label: Our mission. Headline: Turn your coding agent into an AI lab.
Overmind is live on Product Hunt! 🚀
Some big companies have trained their own models this year.
That took an ML team. Most companies don't have one.
They do have coding agents though. So Overmind lets those agents do the ML team's work.
Live: producthunt.com/posts/overmi…
ALT Black starfield with white pixel flowers along the bottom. Small orange label: Our mission. Headline: Turn your coding agent into an AI lab.
Start with a single command in Claude Code. End with a trained 0.8B model to sort support messages. Accuracy went from 37% to 84% on 300 messages.
nitter.cf/OvermindLab/status/211…

Paste into Claude Code:
Read console.overmindlab.ai/setup… and set up Overmind. Then fine-tune Qwen 3.5 0.8B on 1,000 of these support messages and benchmark it against the untouched model on messages it never saw: huggingface.co/datasets/lega…
We used this method to train a 0.8B model on 1,000 support traces, the agent's accuracy went from 36.7% to 84.0%. The training run took 23 minutes from launch to live.
console.overmindlab.ai/

Enterprises still go for 30-200B models because big feels safe. Small and trained often does the job better.
AI got a user interface. Using it is a prompt away.
Next comes a training interface, where improving your agent is as easy as using it.
@JensenHuang put our whole roadmap on one slide at #nvidiagtc berlin: "take control of your intelligence, build your own ai" (the @pollenrobotics microducks waddling around his feet still stole the show!!)
nvidia calls them ai factories, with gpus at one end and enterprise value at the other. almost every conversation i had was about some stretch of that chain
the best debates were about rl. everyone is racing to own the rl stack, yet every compute provider told me the same thing: enterprises still pick 30-200b general models because big feels safe. a focused 1-3b specialist would often do the job better. that is an education gap, not a tech one.
huge thanks to the @nvidia startup team. jessica held the stage with so much warmth, naomi ran everything so smoothly you forgot how hard it was, and howard went from the hardwood to nvidia without losing his court vision. bonus: howard and naomi share my altitude, so for once i got to talk to people eye to eye
the future we are building at @OvermindLab: every agent in production supervised by one open-source platform that trains on your own data, runs on infra you own, and ships a better version of itself every single day 🚀


"Traces are only useful if they feed a better agent."
In practice, on 4,000+ contract questions:
Qwen3.5-9B trained on the task:
• 91.6 F1
• $1.03 per 1k questions
GPT-5.6 Luna:
• 82.0 F1
• $20.94 per 1k questions
Bigger isn't better. Trained is.

Agent traces are useful only if they feed a better agent.
Overmind is an open-source training platform for builders who want to improve specialized AI agents using production traces or their own datasets.
It helps you turn those traces into versioned evaluation and training data, then test improvements against the metrics you define.
Key features:
• Agent context graph – scans a repo for an agent’s capabilities, prompts, tools, and tasks
• Trace-based datasets – turns production traces or uploaded files into versioned eval and training datasets
• Per-capability evals – measures what “good” means on live traces and in batch
• Optimisation experiments – tests prompt, tool, and control-flow changes in your repo; the winner is a git diff
• Model workflow – fine-tunes models on your data and serves trained or frontier models through one API
The platform is open-source (AGPL-3.0); the SDK and CLI are MIT licensed.
Link in the reply 👇

Full write-up, including biomedical and aviation results: overmindlab.ai/research/when…
Try it on your own traces: overmindlab.ai
