

CEO & Founder @ Overmind - Ex-Engineer @ GCHQ
London
Joined January 2026
- Tweets73
- Following110
- Followers102
- Likes178




Tyler Edwards retweeted

In this DevGuild panel, the founders of @exedev, @hexanalytics, @overmindlab, and Induction AI discuss what gets written to memory, what gets forgotten, and how completed runs and human corrections become new knowledge.
🎥 Watch the panel: heavybit.com/library/video/c…
🛠️ Want your agent to learn from it too? Lessons from DevGuild now power new Agent Infrastructure skills in Crucible, Heavybit's MCP server: crucible.heavybit.com/mcp

Yesterday a customer asked us for a feature we hadn't shipped yet. So like the cracked founders we are we pulled an all nighter and got it deployed!
@OvermindLab now offers dedicated inference for your models.
Rewrote our docs around coding agents 👾
Every tutorial and how-to guide has a prompt you paste into Claude Code, Cursor, Codex or OpenCode, and your agent runs it.
Give it a spin!

I just know this is getting dropped into all of my mum's group chats.
Huge thanks to @Forbes
forbes.com/sites/victordey/2…

Overmind is live on Product Hunt 👁️
Most companies don’t have an AI Research team. But they do have a coding agent.
So we built Overmind to transform your data and train your own models, directly inside Claude Code, Cursor, Codex or OpenCode.
Overmind is live on Product Hunt! 🚀
Some big companies have trained their own models this year.
That took an ML team. Most companies don't have one.
They do have coding agents though. So Overmind lets those agents do the ML team's work.
Live: producthunt.com/posts/overmi…

ALT Black starfield with white pixel flowers along the bottom. Small orange label: Our mission. Headline: Turn your coding agent into an AI lab.
Tyler Edwards retweeted

Enterprises still go for 30-200B models because big feels safe. Small and trained often does the job better.
AI got a user interface. Using it is a prompt away.
Next comes a training interface, where improving your agent is as easy as using it.

@JensenHuang put our whole roadmap on one slide at #nvidiagtc berlin: "take control of your intelligence, build your own ai" (the @pollenrobotics microducks waddling around his feet still stole the show!!)
nvidia calls them ai factories, with gpus at one end and enterprise value at the other. almost every conversation i had was about some stretch of that chain
the best debates were about rl. everyone is racing to own the rl stack, yet every compute provider told me the same thing: enterprises still pick 30-200b general models because big feels safe. a focused 1-3b specialist would often do the job better. that is an education gap, not a tech one.
huge thanks to the @nvidia startup team. jessica held the stage with so much warmth, naomi ran everything so smoothly you forgot how hard it was, and howard went from the hardwood to nvidia without losing his court vision. bonus: howard and naomi share my altitude, so for once i got to talk to people eye to eye
the future we are building at @OvermindLab: every agent in production supervised by one open-source platform that trains on your own data, runs on infra you own, and ships a better version of itself every single day 🚀


Tyler Edwards retweeted
60-70% of the world’s computers run on Linux. Yet Microsoft and Apple are the commercial leaders.
Wouldn’t be surprised if LLMs go the same way. We’ll still have Anthropic, OpenAI, and all the other new frontier labs...but open-source models will lead real-world adoption.

Tyler Edwards retweeted
Coinbase built this for their employees.
Overmind ships it for everyone.
Run /overmind finetune in:
• Claude Code
• Cursor
• Codex
Open source, and the model is yours.

We were able to fine tune an open weight model (Qwen3.5-9B) on proprietary internal data at @coinbase, and it out performed frontier models, at much lower cost and speed, for a specialized task (fraud prevention in this case).
I think we'll see more of this pattern inside companies. The frontier models are amazing generalists. But increasingly you'll see specialist models out perform on more narrow tasks, either working on teams, or by themselves.
We're making it easy to fine tune models internally for our employees. We even have a skill for it in our internal harness that makes it easy to spin these up and start training them:
"/fine-tune-and-serve-llm I want to fine-tune Qwen for payments risk review. help me get started"
I imagine we'll have some backend services that could be replaced entirely by this new architecture.


60-70% of the world’s computers run on Linux. Yet Microsoft and Apple are the commercial leaders.
Wouldn’t be surprised if LLMs go the same way. We’ll still have Anthropic, OpenAI, and all the other new frontier labs...but open-source models will lead real-world adoption.
Abstraction is the core of innovation: taking something complex and making it simple, accessible, and usable.
That’s why we built Overmind. To abstract away the complexity of AI infrastructure and give everyone the tools to train and deploy their own models.
Overmind turns anyone into an AI lab.
• Builds a context graph from code and traces
• Curates training and eval datasets
• Evaluates prompts and models
• Trains smaller, specialized models
github.com/overmind-core/ove…

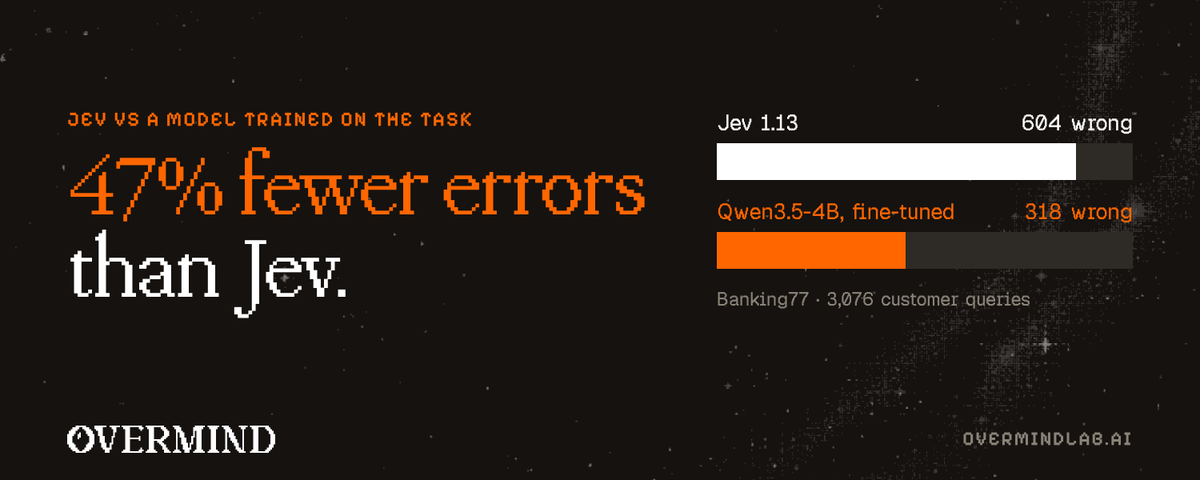
Decision models had a big week. Clef, Strands, OpenAI's Decisions API, Jev already out.
They're great when you don't have labels yet. We fine-tuned a 4B on Banking77 anyway.
89.7% vs Jev's 80.4%. One LoRA, under an hour.
TLDR: the moat is your labelled data.
IMO: the teams that win big will be the ones that train their own models. So we’ve made it easy for them. And its open-source! github.com/overmind-core/ove…

Introducing Overmind. The training platform for agents.
Overmind trained models across biomedical, legal, and engineering tasks beating the frontier and achieving:
• 7x better accuracy
• 20x cheaper usage
• 28x less hallucinations
Train your own: github.com/overmind-core/ove…
Tyler Edwards retweeted
Had a blast!
Watch this space, Q4 may or may not start off with a lot of fire... 👀

It will take me a year to try every new thing announced @OpenAI devday today. Team is cooking! And more resets please 🔵🟢🟠🟣
@TylerEdwas

Very nice Claude can help you hillclimb ⛰️
I'd rather the eval set also trains a specialist agent I own though, but that's just me ;)

Claude can now help you build evaluations and hillclimb on them.
In this article, we share guidance on eval design & skills that Claude Code can use to improve your applications.
claude.dev/blog/automating-e…

Fun one at @heavybit DevGuild last week!
Good room, great minds.


A truly 🔥 room last Thursday at DevGuild. A huge thank you to everyone who came and especially to our speakers and roundtable facilitators 🙏🏼
🎥 Talk videos coming to Heavybit.com
🎉 Show + Tell winners took home credits from @LightningAI, @baseten and @neondatabase


Tyler Edwards retweeted
Keep your tracing stack. Train from it.
Overmind now imports traces from @langfuse, @LangChain (LangSmith), @braintrust and Galileo. Connect a project and it backfills the history, then keeps syncing.
Those traces become eval sets and training data for a model you own.