

Research Scientist. ByteDance Seed (Seedance, Seedream, more)
New York
Joined January 2014
- Tweets80
- Following107
- Followers1K
- Likes319



Pinned Tweet
Few-Step Generation via Data-Space Iteration
Paper: arxiv.org/abs/2610.12102
We rethink the iterative process behind few-step generation. Instead of iterating in flow space, we propose data-space iteration as a new paradigm for better few-step generation.
Details in the thread!
Paper: arxiv.org/abs/2610.12102

More of my research: peter-lin.com/


Peter Lin retweeted

Introducing Omni, one unified model can support any-to-any multimodal modeling, including multimodal understanding, image/video generation and editing, world modeling and 3D reconstruction. All in one that adopts standard mixture-of-experts arch with only 3B activations.
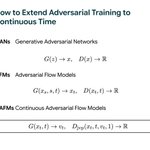
Continuous Adversarial Flow Models (CAFMs)
Paper: arxiv.org/abs/2604.11521
Flow matching generates poor samples without guidance because the MSE loss induces incorrect generalization. Instead of an isotropic Euclidean distance, we need a manifold-aware criterion—but how can we obtain it?
CAFMs bring adversarial training to continuous time. Learning velocity with a discriminator induces better generalization because the discriminator as a criterion can learn the manifold!
Also unlike flow matching’s forward KL objective, adversarial training allows optimizing different divergences. CAFMs can generate sharper and higher-quality samples.
Adversarial training in continuous time also avoids the vanishing gradient problem, leading to stable training.
CAFMs can be trained from scratch or used to post-train existing flow models. Post-training SiT/JiT for just 10 epochs yields large FID improvements. We also observe significant GenEval and DPG improvements when post-training text-to-image models.
More details in this thread!

5. Conclusion and thoughts
Our Adversarial Flow line of research explores ways to integrate adversarial modeling and flow modeling, two of the most influential paradigms in generative modeling. Adversarial Flow Models (AFMs) bring adversarial training to discrete-time flow modeling. Now, Continuous Adversarial Flow Models (CAFMs) further extend this idea to continuous time.
I think being able to do adversarial training in continuous time will unlock many more interesting explorations!
Our method is also different from guidance. Both CAFM and FM ensure convergence to the empirical distribution (i.e., the overfitted ground-truth distribution). They differ only in their finite-capacity generalization, while still remaining faithful to the original distribution. In contrast, guidance does not guarantee faithfulness to the original distribution. Guidance can lead to out-of-distribution (OOD) samples, canonical samples, and other distortions. Accurately and faithfully generating the original data distribution remains an important area of research.
We do not claim that CAFMs can always generate high-quality samples without guidance. When training samples are sparse or contain outliers, the manifold learned by the discriminator is not guaranteed to be correct. Guidance can still be applied orthogonally to achieve low-temperature sampling.
Recently, representational latent spaces (RAE) have become a popular research direction. These methods change the data space in which flow matching operates and therefore implicitly affect the model’s generalization. However, they do not directly address the problem of MSE and require operating in latent space. CAFMs directly modify the loss objective to induce different generalization and work effectively even in pixel space. Other representation-alignment approaches (REPA), may also have implicit connections to our work. We hope our work inspires further insights in the research community.

Our research: Adversarial Flow Models (AF)
arxiv.org/abs/2511.22475
AF unifies Adversarial and Flow Models.
Unlike GANs, AF learns optimal transport (stable). Unlike CMs, AF only trains on needed timesteps (save capacity). We can train super-deep 112-layer 1NFE model! SOTA FIDs!

Introducing Seaweed APT2, a real-time, interactive, streaming video generation model.
seaweed-apt.com/2
Adversarial training for autoregressive modeling!
Streaming 1 minute videos, 1 diffusion step, 24fps real-time on 1xh100, with interactive controls!