
Bot that collects popular Machine Learning content on Twitter such as ArXiv papers, blog posts and GitHub repositories. Posts the most popular Arxiv every 24h.
Joined April 2012
- Tweets1K
- Following260
- Followers3.4K
- Likes0




Pinned Tweet
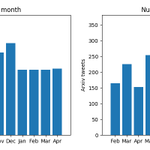
Blog post: One-year monitoring of the machine learning community in Twitter
delanover.com/about/blog/one…

I'm sad to announce that the recent changes in Twitter's API made this bot unable to work. Consequently, there won't be any more tweets and the website won't be updated.
This bot stopped working a couple of weeks ago (during my holidays) probably due to the recent changes in Twitter's API. I will look into it when I have some time.
1
1,125
The most popular Arxiv link during the weekend: nitter.cf/ymatias/status/1659730…

How did our medical #LLM, Med-PaLM 2, become the first to perform at “expert” level on U.S. Medical Licensing Exam-style questions? Check out our new paper: arxiv.org/pdf/2305.09617.pdf

1
1,878
The most popular Arxiv link yesterday: nitter.cf/ShunyuYao12/status/165…

Still use ⛓️Chain-of-Thought (CoT) for all your prompting? May be underutilizing LLM capabilities🤠
Introducing 🌲Tree-of-Thought (ToT), a framework to unleash complex & general problem solving with LLMs, through a deliberate ‘System 2’ tree search.
arxiv.org/abs/2305.10601

3
2,134
The most popular Arxiv link yesterday: nitter.cf/tlngy/status/165896452…
1
1,421
The most popular Arxiv link yesterday: nitter.cf/AziziShekoofeh/status/…

Excited to share our new pre-print on "Med-PaLM 2", highlighting our progress towards achieving expert-level medical question answering performance!
Link: arxiv.org/pdf/2305.09617.pdf

The most popular Arxiv link yesterday: nitter.cf/stevenhoi/status/16582…

Introducing 🔥CodeT5+🔥, a new family of open-source code LLMs for both code understanding and generation, achieved new SoTA code generation performance on HumanEval, surpassing all the open-source code LLMs.
Paper: arxiv.org/pdf/2305.07922.pdf
Code: github.com/salesforce/CodeT5…
(1/n)

4
1,301
The most popular Arxiv link yesterday: nitter.cf/_akhaliq/status/165791…

MEGABYTE: Predicting Million-byte Sequences with Multiscale Transformers
abs: arxiv.org/abs/2305.07185
paper page: huggingface.co/papers/2305.0…

The most popular Arxiv link during the weekend: nitter.cf/_akhaliq/status/165780…
HACK: Learning a Parametric Head and Neck Model for High-fidelity Animation
abs: arxiv.org/abs/2305.04469
paper page: huggingface.co/papers/2305.0…
The most popular Arxiv link yesterday: nitter.cf/DulwichQuantum/status/…

A breakthrough result that finally resolves the longstanding author ordering problem.
arxiv.org/abs/2304.01393

6
2,043
The most popular Arxiv link yesterday: nitter.cf/_akhaliq/status/165646…
Relightify: Relightable 3D Faces from a Single Image via Diffusion Models
abs: arxiv.org/abs/2305.06077
paper page: huggingface.co/papers/2305.0…
The most popular Arxiv link yesterday: nitter.cf/srush_nlp/status/16563…

Pretraining without Attention (arxiv.org/abs/2212.10544) - BiGS is alternative to BERT trained on up to 4096 tokens.
Attention can be overkill. Below shows *every* word-word interaction for every sentence over 23 layers of BiGS (no heads, no n^2).

2
1,303
The most popular Arxiv link yesterday: nitter.cf/JSheltzer/status/16560…

Fascinating new preprint on bioRxiv tackles a whale of a question:
Whales are huge. So why don’t they get a ton of cancers?
biorxiv.org/content/10.1101/…

1,321
The most popular Arxiv link yesterday: nitter.cf/_akhaliq/status/165538…
AttentionViz: A Global View of Transformer Attention
abs: arxiv.org/abs/2305.03210
paper page: huggingface.co/papers/2305.0…

The most popular Arxiv link during the weekend: nitter.cf/cloneofsimo/status/165…

Cool work, have a look! Interesting to see they tie the "probability" of discrete representation to, well, the probability of the dataset : Variational Inference itself.
arxiv.org/abs/2304.04820

1
1,427
The most popular Arxiv link yesterday: nitter.cf/unixpickle/status/1654…

Super excited to release Shap-E, our latest work on 3D generative modeling.
Paper: arxiv.org/abs/2305.02463
Code/models: github.com/openai/shap-e
1,424
The most popular Arxiv link yesterday: nitter.cf/abertsch72/status/1654…

What if we could run Transformer models without worrying about context length?
With our new work Unlimiformer, you can jailbreak your current models to use unlimited length inputs!
Preprint: arxiv.org/abs/2305.01625
Thread 🧵 (1/6)

The most popular Arxiv link yesterday: nitter.cf/wesg52/status/16537503…

Neural nets are often thought of as feature extractors. But what features are neurons in LLMs actually extracting? In our new paper, we leverage sparse probing to find out arxiv.org/abs/2305.01610. A 🧵:

The most popular Arxiv link yesterday: nitter.cf/dbamman/status/1653200…

New paper out today, asking: What books has ChatGPT/GPT-4 *memorized*? A LOT. Harry Potter, Pride & Prejudice, 1984, LotR, Hunger Games, GoT, 50 Shades of Grey, Dune. Memorization is linked to web popularity--lots of old classics + new sci-fi/fantasy. 1/6 arxiv.org/abs/2305.00118

1,185