

@prelatent
Account based inUnited States
About this account
- Account based in
- United States
- Connected via
- United States App Store
Account-level information from X, not a live location or the device used for a specific post.
San Francisco, CA
Joined February 2026
- Tweets23
- Following18
- Followers3
- Likes20
Marcos Polanco retweeted

I just replicated Jev using DiffusionGemma and a very light harness built with Astra.
Because of the harnessing, hallucination rate is also exactly 0%.
I got within 2% of their results on their published benchmarks, also ran the @every suite and got 96% agreement with Jev.
The cost of this model was 0.15 / M tok input on @modal's expensive but incredibly convenient H100s, could halve it or more with reserved capacity.
Repo: github.com/JoshuaSP/open-jev


Marcos Polanco retweeted

"DiffusionGemma as Jev" showcases the power of non-autoregressive architectures.
While Jev demonstrates the value of rapid decision models, running DiffusionGemma in this paradigm leverages canvas diffusion to evaluate structured choices in a single parallel pass:
⚡ ️Massive Parallelism: Denoises across an open canvas in a single step instead of sequential autoregressive token generation (~0.2s on a DGX spark).
🧠 Full Bidirectional Attention: Allows every option to attend to the full context concurrently, yielding well-calibrated decision distributions.
👁️ Multimodal Grounding: Inherits Gemma 4's spatial vision capabilities for complex visual and text decisions.
Read more about this approach here:
github.com/vllm-project/vllm…
nitter.cf/mmastrac/status/210037…
nitter.cf/mmastrac/status/210062…


Marcos Polanco retweeted

Andrew Ng just released a free 2-hour course on complete Harness Engineering
How to go from one prompt to a reliable system of agents that can run, test, and improve themselves:
09:14 - Build your first agent from scratch
33:11 - Master agent loops
1:02:46 - Turn loops into reliable workflows
1:30:15 - Build agents that improve their own work
1:49:05 - Run the complete system without supervision
Model → Harness → Reliable Software
Most agent tutorials stop once the model can call a tool
This one shows you how to build the infrastructure around it within the first 20 minutes
Most people are still prompting one agent at a time
Andrew Ng is already teaching the layer above:
Harnesses that give agents context, tools, tests, and feedback
Watch this brilliant course and build the harness
Then read the full architecture below ↓


真的很感慨,斯坦福的课程更新速度太快了。
CS329Z 已经在教 AI Agent:RAG、Tool Use、MCP、Memory、Multi-Agent、Eval、Coding Agent……
再看看很多大学生还在学习上一个时代、甚至已经被淘汰的东西。
强烈建议身边的大学生都去学学这门课,真的很值得。
cs329z.stanford.edu/
Marcos Polanco retweeted

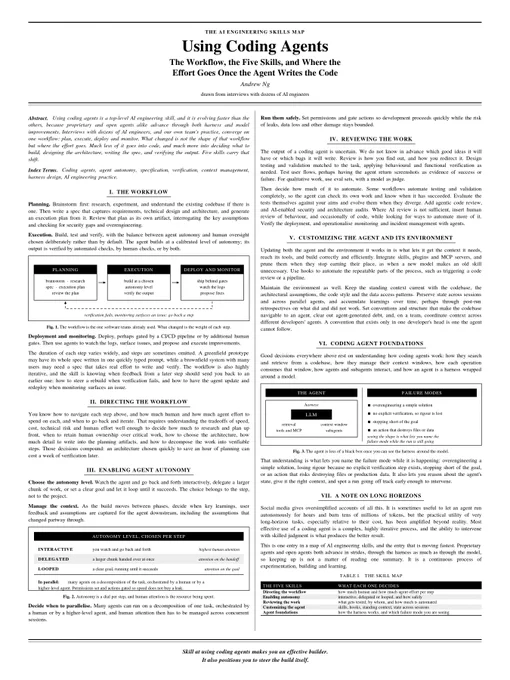
ANDREW NG JUST WROTE DOWN THE FIVE SKILLS AI TEAMS ARE ACTUALLY HIRING FOR IN 2026
drawn from interviews with dozens of AI engineers
not one person's opinion
the workflow didn't change:
planning -> execution -> deploy and monitor
what moved is where the effort goes
much less into code
much more into the spec, the architecture, the verification
that shift is the whole hiring story
writing the code stopped being the scarce part
the five skills teams screen for now:
> directing the workflow - how much is human, how much is agent
> enabling autonomy - which setting, and how safely
> reviewing the work - what gets tested, by whom, how much is automated
> customizing the agent - skills, hooks, standing context, state across sessions
> agent foundations - how the harness works, which failure mode you're seeing
the architecture underneath:
> the harness wraps the model, not the other way around
> retrieval - how it searches your codebase
> tools and MCP - what it can reach
> context window - what each operation spends
> subagents - work split, then recombined
autonomy is a dial you set per step, not per project:
> interactive - you watch, you go back and forth
> delegated - one big chunk, handed over at once
> looped - a clear goal, running until it succeeds
the loop is the top of that dial
and it only works if two things exist first
a goal the agent can test itself against
and a stop condition it can actually reach
without those, a loop doesn't run until it succeeds
it runs until you notice
that's loop engineering
the prompt is the easy half
the harness decides whether the night was worth anything
four ways a run goes wrong:
> it overengineers a simple thing
> no verification step, so rigour goes missing
> it stops short of the goal
> it destroys files or data
naming the failure mode while the run is still going is the interview answer nobody has
anyone can start a loop
the people getting hired can say when to step in


Codex users, do this now for Astra:
--- Start Prompt ---
"Codex, read @pvncher's article nitter.cf/pvncher/status/2095991… then audit all of my skills and AGENTS.md files inside ~/Projects"
--- End Prompt ---
You're welcome.


Marcos Polanco retweeted

How to become AI engineer in next 6 months:
By the end, you want to be able to:
- build LLM apps end-to-end
- use APIs from OpenAI / Anthropic / open-source stacks
- design prompts and context properly
- add tool calling and structured outputs
- deploy real projects
So, let’s discuss your roadmap month by month
Month 1: Get solid enough in coding and fundamentals
What to learn:
- Python really well
- Git + GitHub
- CLI / terminal basics
- JSON, APIs, HTTP, async basics
- basic SQL
- basic data handling with pandas
- virtual environments, package management, error handling
- FastAPI or Flask
Month 2: Master LLM app development
What to learn:
- prompting fundamentals
- system vs user instructions
- structured outputs / JSON schemas
- function/tool calling
- streaming responses
- conversation state
- cost / latency / token basics
- failure handling
- prompt injection awareness
Month 3: Learn RAG properly
What to learn:
- embeddings
- chunking
- vector databases
- metadata filtering
- reranking
- retrieval quality issues
- hallucination reduction
- citations and grounding
Month 4: Agents, tools, workflows, evals
- agent loops
- tool selection
- state management
- retries
- when NOT to use agents
- multi-step workflows
- evaluation harnesses
- task success metrics
Month 5: Deployment, product thinking, and reliability
What to learn:
- FastAPI production patterns
- Docker
- background jobs
- queues
- auth + API key security
- logging
- observability
- prompt/version management
- eval dashboards
- cost monitoring
- rate limits
- caching
Month 6: Specialize and become hireable
these knowledge and skills you gained can be applied in three directions
you need to choose one of them and focus on practice
although everything mentioned above is also best learned purely through practice
Direction 1: AI product engineer
Best if you want startup jobs fast
Focus on:
- LLM apps
- RAG
- agents
- deployment
- product UX
Direction 2: Applied ML / LLM engineer
Focus on:
- fine-tuning
- when to fine-tune vs prompt
- evaluation
- inference optimization
- open-source models
- training pipelines
Direction 3: AI automation engineer
Focus on:
- workflow orchestration
- business process automation
- multi-tool systems
- CRM, docs, email, support, ops use cases
This roadmap will help you go through a practical path, and the key is to study each of these points and then test them in real work
By month six, you will already have several built products or examples of completed tasks
And it will be much easier to get a job as an AI engineer
Save it so you don't lose it and can return to study later


Marcos Polanco retweeted

Talking at the Future of Math Symposium in 10 minutes (livestream link: youtube.com/live/tN4hsT5t0nw…). I decided to make the talk "personal" and explain the five moments that updated me on how fast AI will change mathematics. (The ChatGPT's illustration of these moments is so good!!)

Marcos Polanco retweeted

A new milestone in automatic formalization:
We translated an entire graduate math textbook into Lean using 30K LLM agents.
Open-source, large-scale multi-agent inference that actually works
> Blueprint+Lean: faabian.github.io/algebraic-…
> Codebase+preprint: github.com/facebookresearch/…
1/7

Marcos Polanco retweeted

Launching my new online course with @UniofOxford called The Art of Proofs. Proofs are the core of mathematics, and this course is about building up your foundational proof skills from the beginning to all sorts of cool topics like playing around with different kinds of infinity.

Marcos Polanco retweeted

Cray Distinguished Colloquium at UMN, next Monday.
An AI converted zlib to Lean and proved it correct. 10 AI agents built a verified DSL in a weekend. Three IMO teams, no competing platform.
The slides are written in Verso: checked by Lean.
leodemoura.github.io/static/…


Marcos Polanco retweeted
4/ Code: github.com/Percepta-Core/tra…

Marcos Polanco retweeted

We open-sourced Axplorer.
Axplorer builds on PatternBoost; it discovers outlier math constructions to attack open problems.
On Turán 4-Cycles, No 5 Points on Sphere, and Isosceles-Free Sets, Axplorer matched SOTA w/ a fraction of compute cost and time.
It's now in your hands.
Marcos Polanco retweeted

Most overlooked skill in machine learning is creating evals. Worthy metrics which beg for improvement are the root of progress.

Marcos Polanco retweeted

The technical report for Goedel-Prover-V2 is out!
📌 SOTA among all open-source theorem provers
⚡ Among the best overall—including closed-source—under small test-time compute
Read it here: arxiv.org/abs/2508.03613
