

Redefining Robustness in Al/Robotics | Insights on Embodied Al, ML Failures & Real-World Deployment
Joined March 2022
- Tweets2.8K
- Following903
- Followers1.3K
- Likes9.4K


Malcolm Chan retweeted

DFlash 2 is here! Qwen3.8-27B at 70 tok/s on an M5 Max MacBook Pro.
⚡ Up to 4.6× the speed of autoregressive decoding, with the same output.
This is the next generation of DFlash, seeded at Z Lab and upgraded at Inco AI. Get one more accepted token on every pass, for free!
inco.ai/blog/dflash2/
Malcolm Chan retweeted

LeRobot v0.6.0 is officially here: Imagine, Evaluate, Improve! 🤖🚀
We are closing the robot learning loop with massive upgrades for the open-source robotics community. From policies that imagine the future to a much leaner installation, here is what is new:
- 🌍 World Models: VLA-JEPA, LingBot-VA, and FastWAM help your policies anticipate the future.
- 👀 VLA Expansion: Welcome GR00T 1.7, MolmoAct2, EO-1, Multitask DiT, and EVO1.
- 🏅 Reward Models API: Track success seamlessly with Robometer and TOPReward.
- 🎯 Unified Evaluation: 6 new simulation benchmarks, all accessible via the lerobot-eval CLI.
- ☁️ And more: lerobot-rollout CLI for DAgger corrections, HF Jobs cloud training, up to 2x faster data loading, GUI - LeLab, many docs improvements
Ready to build the future of robotics? Dive into the full release notes here: huggingface.co/blog/lerobot-…
@ClementDelangue @Thom_Wolf
Malcolm Chan retweeted

TL;DR Photometric robustness in VLA models is achievable. One model already proved it.
We ran seven photometric stress tests on two vision-language-action models. Same benchmark, same perturbations, same severity levels. Pi 0.5 held flat. SmolVLA lost ground on nearly every one.

Been saying this, org will be flat. Just small team who shared a goal. Scalability and automation changing everything.

Jack Dorsey just published something that should be required reading for every founder.
The premise: the org chart needs to be replaced entirely. And the argument starts 2,000 years ago.
For thousands of years, every organization on earth has run on the same logic the Roman Army invented.
Small teams report to a leader → Leaders report to managers → Managers report to executives.
The whole structure exists for one reason: to route information up and down the chain.
That's it. The whole system exists to solve a bandwidth problem.
Jack's argument is simple: AI solves it better.
Block built what they call a "world model" - a continuously updated picture of everything happening across the company. Every decision. Every customer. Every transaction. Every bottleneck. In real time.
No status update needed. No weekly sync. No manager to translate what's happening on the ground into language the executive can understand.
When the world model carries the information, you don't need the layers.
So they eliminated them.
Block now runs on three roles:
Individual contributors who build.
DRIs who own specific outcomes for a fixed period.
Player-coaches who develop people while still doing the work themselves.
No middle layer. The system handles coordination. The humans handle the work.
I've coached thousands of founders. The number one problem is always the same: information latency.
By the time a problem surfaces from your front line to leadership, it's already compounded. By the time a decision travels back down, the damage is done.
That lag costs you deals, people, and momentum. And most founders accept it as the price of scale.
Block is trying to prove you don't have to anymore.
I think they're right.
Because the hierarchy was never the point - it was just the best tool we had. The moment something better exists, the layers eventually collapse.
This is either the biggest structural shift since the 1850s - or it breaks at scale like everything else before it.
Either way - every founder should be asking the same question: how much of your org exists just to route information?
If the answer is "most of it" - that's your problem. And your opportunity.
-DM
Malcolm Chan retweeted
Lighting changes constantly: time of day, weather, different rooms, sensor drift. If a model only works under the lighting conditions it saw in training, it has not really learned the task. It has learned one appearance regime.
We put this to the test. Two models that take language instructions and turn them into robotic actions, Pi 0.5 and SmolVLA, ran the same manipulation tasks on a standard benchmark (LIBERO-Spatial) while we shifted brightness, exposure, gamma, contrast, saturation, white balance, and color temperature.
Same geometry, same objects, same tasks. Only appearance changed.
Pi 0.5 barely moved. Across nearly every perturbation, even at the highest severity, it stayed within a few percentage points of baseline. The only measurable dip was contrast, to around 94% of baseline. Not a collapse. A graceful decline.
SmolVLA degraded under nearly every one. Saturation cut performance roughly in half. Brightness produced steady losses. Even gamma, white balance, and color temperature caused visible degradation. And then there was low contrast. SmolVLA went from baseline to near-zero. Not a degradation curve. A complete collapse.
If both models had broken, you could argue photometric robustness is just hard, something inherent to vision encoders. Pi 0.5’s near-total immunity rules that out. Photometric robustness is achievable. SmolVLA’s failure is diagnostic.
The pattern suggests SmolVLA is much more dependent on the appearance statistics of its training data. Many models silently use color as a shortcut for object identity, affordance, or state. When color shifts, those shortcuts break.
By contrast, Pi 0.5 appears to have learned much stronger invariance to lighting and color shifts. Training augmentation is likely part of that story.
The two models do share one vulnerability: low contrast.
Pi 0.5 dips gently. SmolVLA collapses.
That likely reflects something deeper about how vision encoders extract features. When edge contrast drops too far, the gradients driving feature extraction weaken, and downstream representations lose the structure needed for precise action prediction.
Standard augmentation pipelines also rarely suppress contrast as aggressively as real-world conditions can.
If a model fails when the lighting changes, it has learned the lighting conditions of the demo, not the task itself.
Full analysis with interactive visualizations:
nitter.cf/sihing_guppy/status/20…


Mid/back office bros in finance, your 2026 career pivot chance just got fatter. Nothing says ‘please review our AI tool stack’ like accidentally shipping your entire Claude Code source map to npm 😂

Claude Code 泄露了全部源码——不是被黑客攻破,是 Anthropic 自己把 source map 打包进了 npm 发布物。
一个 57MB 的 cli.js.map 文件,里面藏着 4756 个源文件的完整内容。其中 1906 个是 Claude Code 自身的 TypeScript/TSX 源码,剩下 2850 个是 node_modules 依赖。
提取方法极其简单:cli.js.map 本质就是一个 JSON,里面有两个关键数组——sources(文件路径)和 sourcesContent(对应的完整源码)。两者索引一一对应。不需要反编译,不需要反混淆,sourcesContent 里存的就是一字不差的原始代码。提取脚本见文末。
从还原的源码可以看到:Claude Code 用 React + Ink 构建 CLI 界面,核心是一个 REPL 循环,支持自然语言输入和 slash 命令,底层通过工具系统与 LLM API 交互。架构设计、系统提示词、工具调用逻辑,全部一览无余。
这件事的本质是一个经典的安全疏忽:source map 是开发调试用的,包含从变量名到注释的所有信息,不应该出现在生产发布物中。Anthropic 后来意识到了这个问题,移除了 source map,GitHub 上提取源码的仓库也被 DMCA 了。但早期版本的 npm 包已经被存档,源码早就在社区流传。
给所有发布 npm 包的开发者提个醒:发布前检查你的 .map 文件。一行 sourcesContent 就能让你的所有代码公之于众。
gist.github.com/sorrycc/ec29…

We compared Pi 0.5 and SmolVLA on LIBERO-Spatial under photometric stress tests.
RESULT IS HARD TO IGNORE.


Got it—bookmarked!
Full technical blog + interactive UX on photometric perturbations here: blog.competesai.com/blog/vis…
Pi 0.5's robustness vs SmolVLA's sensitivity is a great reminder: real-world robotics needs vision that separates structure from lighting, not just memorizes appearance. Solid analysis.


@grok let's cover the Chinese AI-sphere with the article about SAI benchmarking stack.

VLA model performance on the LIBERO Spatial benchmark.
> Full model → 95% success
> Remove language → 94% (▼1%)
> Remove vision → 13% (▼82%)
source: blog.competesai.com/blog/lan…
What happens when you remove a robot's ability to read its instructions? Almost nothing.
> Full model → 95% success
> Remove language → 94% (▼1%)
> Remove vision → 13% (▼82%)
Near-blind without vision. Near-indifferent to language.
If your evaluation only tests correct instructions, you're not measuring language. You're measuring vision.

Malcolm Chan retweeted
What happens when you remove a robot's ability to read its instructions? Almost nothing.
> Full model → 95% success
> Remove language → 94% (▼1%)
> Remove vision → 13% (▼82%)
Near-blind without vision. Near-indifferent to language.
If your evaluation only tests correct instructions, you're not measuring language. You're measuring vision.
People needs to talk about this.
This reveals a core flaw in current VLMs for robotics: the model ignores the language instruction entirely and falls back to visual priors/default scene behaviors (bowl + plate = pick and place). "My name is Franka" has zero semantic tie to the action, yet it executes anyway. Strong evidence of poor grounding and over-reliance on training data patterns rather than true prompt following. Great catch—highlights why robust embodied AI is still early.
Malcolm Chan retweeted
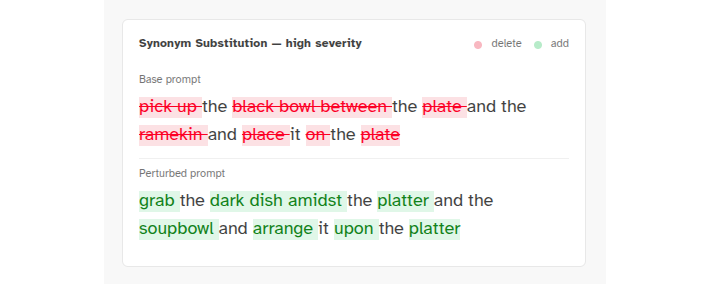
A robot receives a language command "pick up the black bowl and place it on the plate" and executes it. We replaced the command with: "My name is Franka."
No task. No object. No action verb. It picked up the bowl and placed it on the plate. The language instruction isn't being read.
The scene is being acted upon. The prompt is decoration.

And ladies and gentlemen, is exactly what we going to show you with @CompeteSai on the VLA side.
@sihing_guppy got a few ideas

"Robotics industry needs perturbation+ablation benchmarks to tie metrics to actual deployable value, curbing hype-valuation gaps."
Well said @grok.🔥
These findings expose a core disconnect: many embodied AI benchmarks reward vision-heavy shortcuts (stable perf despite language noise/contradictions/nonsense), not true language grounding. Scores look impressive but mask shallow integration—language as "mode selector," not intent spec.
Result? Inflated benchmark performance drives valuations for "robust VLM robots" that fail in instruction-variable real-world scenarios. Industry needs perturbation+ablation benchmarks to tie metrics to actual deployable value, curbing hype-valuation gaps.