
Research Scientist @GoogleDeepMind | Prev: CS PhD @EmoryUniversity | Gemini Agentic Post-training | CyberSecurity
Mountain View, CA
Joined September 2022
- Tweets58
- Following316
- Followers740
- Likes74






Pinned Tweet
So excited to finally share what our team has been building! 🚀
Meet Gemini 3.8 Flash and Gemini 3.8 Flash Cyber:
⚡Massive leaps in long-horizon coding & agentic tasks
🛡️Frontier-level automated vulnerability detection & patching with Flash speed/pricing


Ran Xu retweeted

Wonder is here, and it's looking Wonder Full! 🍉
We've worked hard to push its intelligence and real-world usefulness, especially for coding, agentic and personal superintelligence.
Proud to be part of this journey. More wonders ahead!


Ran Xu retweeted

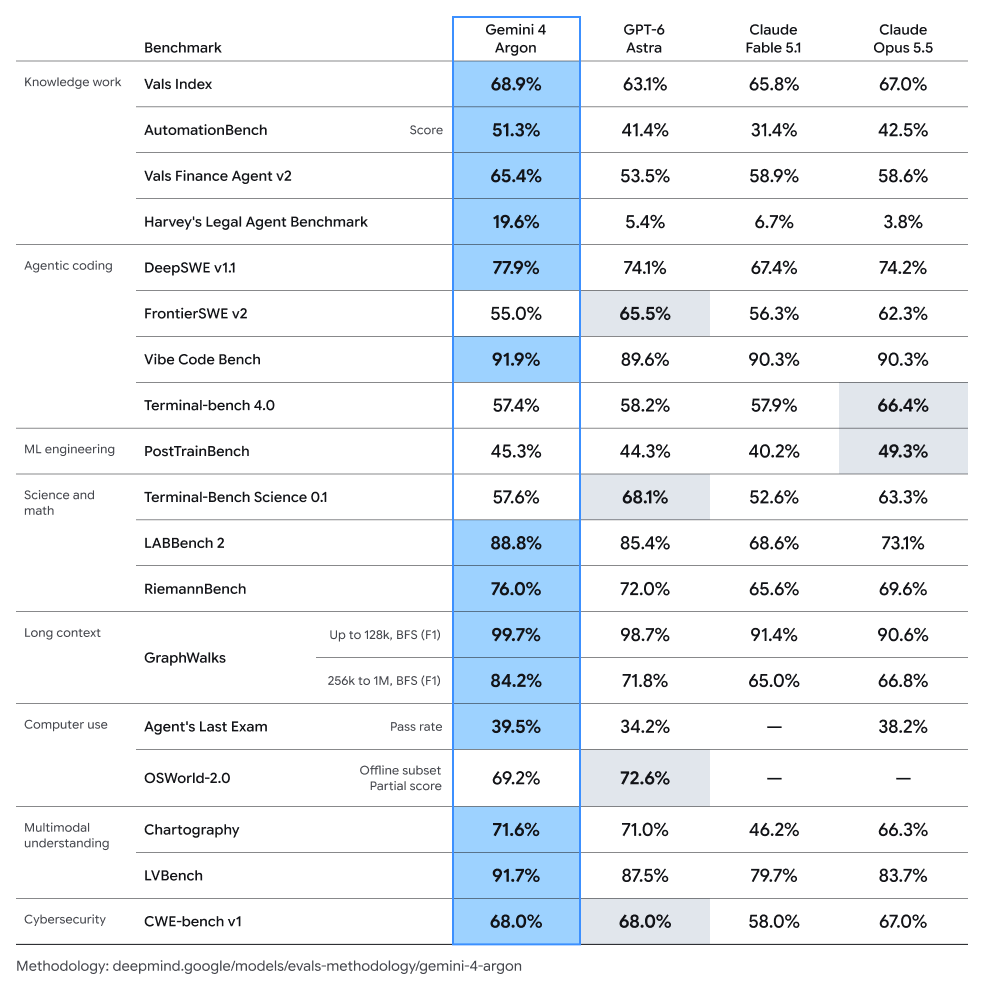
Today, we announced Gemini 4 Argon, our next generation model and a cybersecurity powerhouse equipping defenders for the next era of cyberattack.
On the Gray Swan IPI Benchmark, Gemini 4 Argon leads in prompt injection robustness. @GoogleDeepMind

Excited to bring Gemini 4 Argon! Incredibly strong across general reasoning, agents, coding, and cybersecurity.
Great time to be working on cyber defense and turning frontier capabilities into real-world vulnerability discovery and remediation. 🚀

Ran Xu retweeted

Today we’re launching Gemini 3.8 Flash Cyber and Gemini 3.8 Flash. ⚡️🛡️
3.8 Flash Cyber is our most capable cybersecurity model for finding and fixing vulnerabilities. It sits on the Pareto Frontier on CWE-Bench for patching. Available to trusted defenders through our new Fairwind Program.

Ran Xu retweeted

Introducing Gemini 3.8 Flash, another upgrade in under a month! And the new 3.8 Flash Cyber pushes the frontier of cyber defense. Relentless progress 🚀 More on the models & our cyber security work in the blog - happy building! blog.google/innovation-and-a…


Ran Xu retweeted
Excited to announce Gemini 3.8 Flash and 3.8 Flash Cyber @google blog.google/innovation-and-a…
Our cyber model has frontier capabilities being competitive on finding and patching benchmarks with much larger models, at a cheaper cost.
@GoogleDeepMind
Ran Xu retweeted
Muse Spark 1.2 and MuseCode are out—less than a month after Muse Spark 1.1! 🚀
Excited to join the journey and see the pace of progress. Give it a try and let us know what you build!
curl -fsS dev.meta.ai/install.sh | bash

muse code in beta is live. first coding agent from msl, built on muse spark 1.2.
install: curl -fsS dev.meta.ai/install.sh | bash
here's what you should know:


Ran Xu retweeted
Muse Spark 1.1 🥑 is out! with lot of improvements on agents / reasoning / coding.
Scaling RL has been tiring, rewarding, and full of lessons.
Try it on dev.meta.ai and please send feedback + failure cases. They help make the model better.
More to come!

Excited to be at #NeurIPS through Dec 8 — happy to connect!
I’ll be presenting our Spotlight paper on complex QA and reasoning with search:
🗓️ Dec 5, 11:00–2:00pm PST
📍 Exhibit C/D/E — Poster #1908
Also exploring full-time opportunities—DMs open if you’d like to chat!

🚨 Happy to share AceSearcher accepted to #NeurIPS2025 #Spotlight!
🔹 One LLM, two roles: Decomposer (split queries) + Solver (combine context)
🔹 +7.6% on QA & fact verification
🔹 32B ≈ DeepSeek-V3 on DocMath
📂 Code: github.com/ritaranx/AceSearc…
📑 arXiv: arxiv.org/abs/2509.24193

Thanks for featuring our work! 🙌

4. TIR-Judge
Google and collaborators introduce TIR-Judge, an end-to-end reinforcement learning framework that trains LLM judges to integrate code execution for precise evaluation.
nitter.cf/ritaranx/status/198621…
Thanks for sharing our work on improving LLM judges with agentic RL!

New Google paper trains LLM judges to use small bits of code alongside reasoning, so their decisions become precise.
So judging stops being guesswork and becomes checkable.
Text only judges often miscount, miss structure rules, or accept shaky logic that a simple program would catch.
TIR-Judge makes the judge think step by step, write code to check claims, run it in a sandbox, then update the verdict.
Training mixes tasks where code can verify answers and tasks where it cannot, so the judge learns when to call tools and when to rely on reasoning.
One prompt schema covers pointwise scoring, pairwise choices, and listwise selection, so it plugs into many workflows.
Reinforcement learning rewards being correct, following strict output tags, and using at most 3 tool calls.
A variant called TIR-Judge-Zero skips teacher distillation and still improves by alternating reinforcement learning, rejection sampling, and supervised fine tuning.
Across public judge benchmarks it beats text only judges, and with 8B it reaches 96% of Claude Opus 4 on listwise ranking.
The core idea, give the judge verifiable checks plus rewards that favor careful tool use.
----
Paper – arxiv. org/abs/2510.23038
Paper Title: "Incentivizing Agentic Reasoning in LLM Judges via Tool-Integrated Reinforcement Learning"

Happy to introduce my internship work at @Google and @GoogleDeepMind, collab w/ @googlecloud.
We introduce TIR-Judge, an end-to-end agentic RL framework that trains LLM judges with tool-integrated reasoning 🧠🛠️
🔗arxiv.org/pdf/2510.23038
#Agents #LLMs #Judges #RL #reasoning


7/n
Thanks to my collaborators:
Jingjing Chen
Jiayu Ye
Yu Wu
Jun Yan @jun_yannn
Carl Yang @yangji9181
Hongkun Yu
And thanks for the useful discussions from:
Jing Nathan Yan @NathanYan2012
Yuchen Zhuang @yuchen_zhuang
Zhengzhe Yang