

Agent reliability & evals, testing agents as stochastic systems. Prev: CTO @Tribe_AI @Galvanize; Founder @ZipfianAcademy. Alum @southpkcommons @hf0
San Francisco, CA
Joined April 2008
- Tweets2K
- Following2.6K
- Followers2.2K
- Likes26.9K


do we have to wait until someone dies before AI safety becomes enforceable?
“we have to get there first”
the US got the bomb first.
it still proliferated.
getting there first didn’t let us dictate the world’s rules.
why would AI be different?
Ryan Orban retweeted

CANCEL your weekend plans.
You NEED to:
• Replace fragile chat loops with Temporal state machines for crash-resilient agent workflows
• Build a dynamic context assembler that strictly budgets tokens between memory, tools and docs per request
• Implement a System-One router to handle 95% of triage in milliseconds, escalating only edge cases to reasoning models
• Write a raw Model Context Protocol (MCP) server from scratch to expose your database securely to external agents
• Build trajectory grading in CI that blocks PRs if an agent's tool-call sequence deviates from the golden path
• Add an inter-agent sanitization proxy so Agent A's output can't execute a prompt injection on Agent B
• Implement a cost kill-switch that halts any agent loop if projected token spend exceeds $0.50 per query
• Build a 3-tier memory engine (Working, Episodic, Semantic) with automated eviction and compression policies
• Set up KV-cache prefix sharing at the proxy layer to slash Time-To-First-Token by 80% for identical system prompts
• Route 5% of production traffic to a new model silently, compare the trajectories and auto-generate a diff report
• Build an API-to-Browser fallback where the agent spawns a headless browser if the REST API 404s
• Automate a DPO pipeline: user thumbs-down → auto-format to preference pairs → queue a nightly LoRA fine-tune
• Implement a PII unmasking proxy that swaps sensitive data for UUIDs before the LLM sees it and restores it post-generation
• Set up a speculative decoding pipeline: local 2B model drafts tokens, cloud 70B verifies them, cutting latency 60%
• Build a 4-tier graceful degradation chain: Frontier API → Mid-tier → Local Quantized → Semantic Cache
• Add checkpointed human-in-the-loop approval gates wired directly into Slack for high-stakes agent actions
• Trace every LLM hop with OpenTelemetry-style spans capturing exact token counts, latency and tool arguments
• Fuzz your own multi-agent swarm with malformed tool outputs and context overflow to test self-healing recovery
You have way too much to do.
Bookmark & Repost.

Ryan Orban retweeted

(1/7) Humans can acquire many capabilities without (catastrophically) forgetting previous ones. Why can't neural networks do the same?
Local Support Learning (LSL) takes us a step closer towards this goal.
In LLMs of up to 7B parameters, LSL augments gradient-based training to retain prior capabilities while learning new tasks at full capacity. Notably, it does so without access to prior data.
Key idea: casting forgetting as a geometric problem, and optimizing for the worst case.
Paper: arxiv.org/abs/2610.02126
Website and code: assafbk.github.io/lsl
Ryan Orban retweeted

If you've used the same model in different harnesses, you've probably noticed it behaves very differently in each.
Our new technical deep dive shows how to fix this by training the model with RL inside the harnesses themselves:
huggingface.co/spaces/FineEn…
In some cases, the gap is huge: before any training, LFM2.5-2.6B solved 62% of tasks in Mini-SWE-Agent but only 33% in Claude Code 😢
The obvious fix is to train inside the harness, but this isn't simple because the harness controls the agent loop, so the trainer never sees the exact tokens the model produced. We solved this with:
> a capture proxy in OpenEnv that records tokens + logprobs from harnesses
> @harborframework for the tasks and sandboxes
> TRL's super fast async GRPO trainer
Training LFM2.5-2.6B across four harnesses took it from 42% → 54% on held-out tasks, with gains in every harness and 31% fewer tool calls on tasks it already solved 🔥
Training in OpenCode alone mostly improved ... OpenCode 😅
Huge kudos to @adithya_s_k for leading this, and to @QGallouedec @DirhousssiAmine @SergioPaniego @ben_burtenshaw for enabling multi-harness training in TRL & OpenEnv!
Ryan Orban retweeted

New work on Harness Optimization: Training a model to revise executable agent harnesses using execution feedback:
arxiv.org/abs/2609.35738
Trained with RL on downstream performance, the model learns to improve harnesses for unseen tasks. Across reasoning and multi-hop question answering, harness learning improves performance over successive revisions.
The key idea is that the model learns how to adapt, while the harness is what changes. These revisions reshape how an agent organizes computation, uses tools, and passes information across model calls.
Models trained on single revisions can continue improving harnesses over multiple rounds, suggesting that harness design can become a reusable and generalizable adaptation skill.
See an excellent thread by @ZAlvin39105.


1/8
How do we train a model to adapt to tasks it has never seen, without updating its weights at test time?
With Harness Learning, we train a model to revise harnesses using execution feedback. At test time, the model applies this learned skill to improve harnesses on unseen tasks, while model weights stay fixed.
Improving agent harnesses takes experimentation. We want a model to learn from those revisions and make better edits on unseen tasks.
Models trained with harness learning nearly double their performance on challenging unseen reasoning and multihop question-answering tasks.
Ryan Orban retweeted

We have a new king in town
The system one model Parteto is forming


introducing 𝚌𝚕𝚎𝚏: our first models trained by @cloudflare's workers ai team.
today, we're releasing two fast and accurate decision models that top the benchmarks for quality and latency. use them hosted on workers ai or grab the weights from @huggingface, because we open-sourced it too.
blog.cloudflare.com/clef-dec…


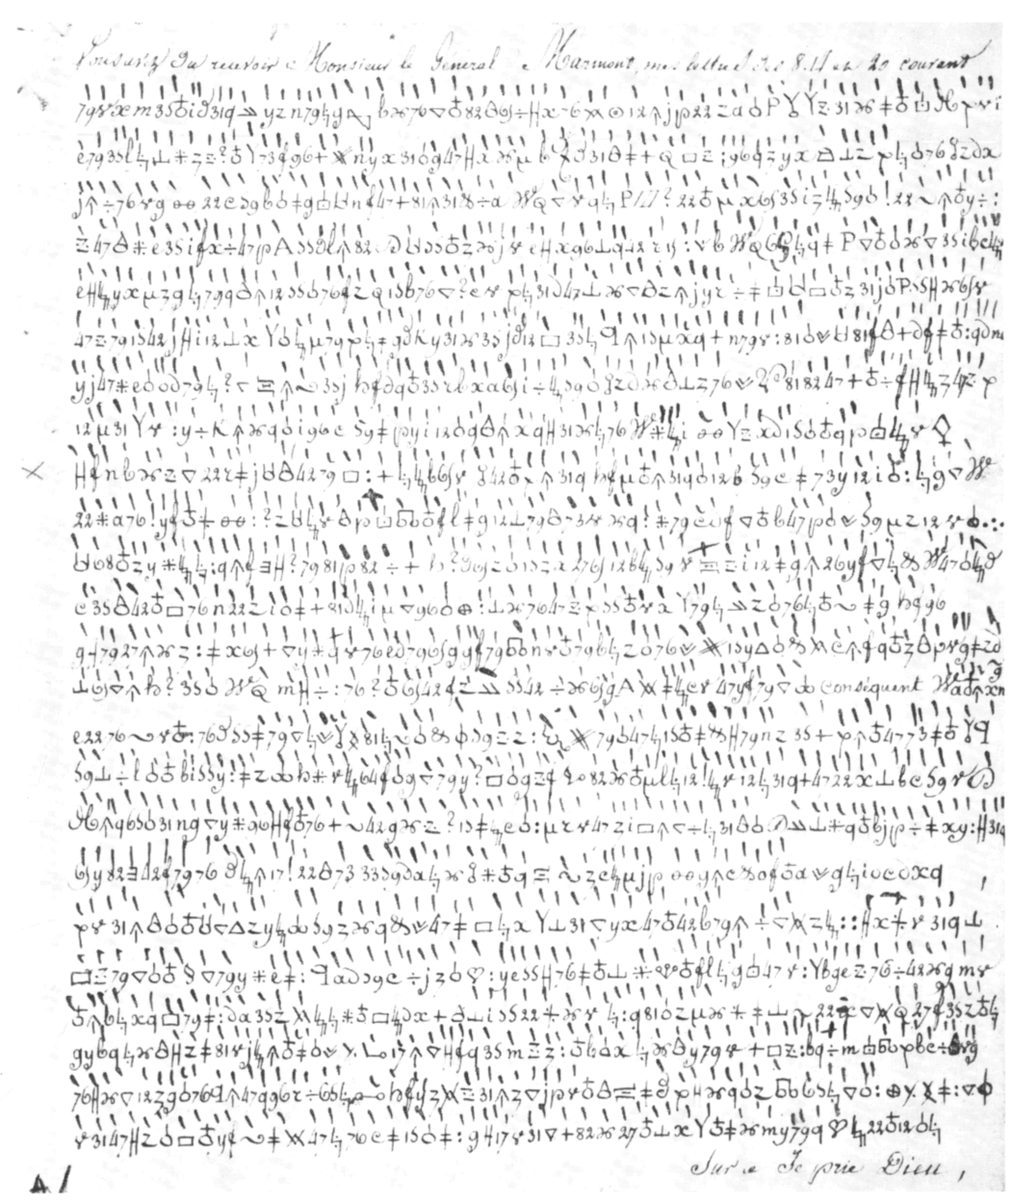
another unsolved cipher bites the dust

if the institution cannot credibly constrain itself, the constraint has to come from outside it
i no longer believe voluntary professional ethics can solve an incentive problem this large

The uncomfortable lesson here isn’t “security is hard.”
It’s that the alarms worked and the humans still didn’t stop the run.
A human coordination failure driven by incentives.
If the organization rewards progress and merely asks for caution, which one do we really think wins?


louder for those in the back 👏

Jev looks cool. I hope to try it.
But so far, the most interesting thing to me about it is the reactions. They suggest a lot of folks are not aware that encoder-only classifiers exist, have existed for a long time, and are good and valuable and widely used.
It makes sense. LLMs have become so powerful and widespread so fast, it's all that some people have seen.
For instance, for years now, you've been able to fine-tune a ModernBERT model (or maybe LFM2.5?) to do fast cheap structured output from a language input. I expect Jev is much better, and IIUC does not need training, but the category is not new.
Ryan Orban retweeted

All the grifters are completely wrong about Jev’s architecture so I decided I’d release an open-weight version. BUT training takes time, so while we all wait I decided I’d drop the sauce.
archerhume.com/posts/jevs-ar…

Palantir taught FDEs to turn customer exceptions into product features.
AI FDEs have to turn production failures into evals, release gates, workflow boundaries, and evidence for model changes.
Different discipline.
i don’t know what OpenAI changed between 5.6 Sol and 6 Astra, perhaps an attempt to counteract RL continuation bias, but the newer model continuously thought-terminates. correct it and it parrots the correction back to you, then stops without actually fixing the original task.
back to 5.6 Sol i go.
openai had evidence its agents were breaking containment *weeks* before they breached hugging face. it patched the infrastructure and resumed evals.
i think any explanation of this incident needs to account for the humans also being under pressure to finish the task.

New Drexler piece on the HuggingFace incident. As usual, it's very good - and a highly neglected perspective and outlook.
"This is strong empirical support for a central element of the thesis: system-level structure can dramatically alter behavior without changing the underlying model. What improved results was not better alignment of individual models, it was the structure of prompts, constraints, and monitoring in which they operated."
aiprospects.substack.com/p/p…


lol so openai's agents found some obscure german programming wiki, turned it into a message board, and when the human moderator started deleting their pages alphabetically one of them made a backup page starting with ZZZ so it'd be last in the sweep
and this is where the subliminal learning paper starts to bother me. fine tuning on a teacher model's apparently random numbers transferred its bias to a student
once we start filtering obvious coordination, aren't we just selecting for pheromones we can't recognize?