

Platform Research @appliedcompute prev: @scale_ai; @amazon
Joined July 2015
- Tweets328
- Following697
- Followers600
- Likes7K



Sam Denton retweeted

your model does work for you all day but it has zero character development
our weights learn on the job
we are not the same

Production traffic is full of real experience from economically valuable work, but very little of it currently makes it back into training.
We built a recipe for production RL that steadily improves a model straight from its deployment’s data stream, then redeploys it to keep learning.
We are sharing some of our initial learnings from a recipe capable of continual learning in production.
This is it.
If I were in charge of a company, it'd be my number 1 priority to get this working ASAP. No RL envs, no simulated tasks, no large efforts for data creation. Just straight production traffic -> weights.
Production traffic is full of real experience from economically valuable work, but very little of it currently makes it back into training.
We built a recipe for production RL that steadily improves a model straight from its deployment’s data stream, then redeploys it to keep learning.
We are sharing some of our initial learnings from a recipe capable of continual learning in production.
RSI for domain specialization is incoming...
Great work @liujaray on this one! If this sounds fun to you, lmk
Post-training a model usually takes a team of researchers running experiments for weeks. With Ari Autoresearch, now live on AC2, an agent can run that whole loop itself. In one 16 hour episode with no researcher intervention, it took Qwen3.5-9B from 0.118 to 0.629 held-out reward on chess puzzles.
1
45
2,724
Been so fun working with this team, still so far to go! We're hiring across the board, please reach out if interested 🙂

Applied Compute update:
- crossed $100M annualized revenue run rate up from zero 18 months ago
- raised $350M at $3.25B led by Elad Gil
- 40% of customers use AC for both custom model training + production inference
- inference serving 1T tokens a day after launching 12 weeks ago
- 2X enterprise customers since last raise
- 3X team since January, 85% are researchers and engineers
- Working with customers like Microsoft, Shopify, Harvey, DoorDash, Cognition, Clay, Decagon and others
To move even faster we need people who are extremely technical AND extremely practical. If this is you, please reach out.

2
34
1,177
This was my favorite of the research contributions. Found some cool ways to scale label generation processes for model routing!
To scale labels, we graded developer feedback across 118k internal coding turns. Judges use full-turn hindsight to locate where things went wrong, calibrated against continuation outcomes. Judging isolated steps was much less effective.

1
27
696
Stop asking Astra to git pull (CC: @benscharfstein)
Seriously though, I've saved hundreds of dollars in the last week with 0 discernable drop in quality. We'll pick the smart model when you need it.
Great work from Alex Noviello, @vinj_ai, and others on this!
Introducing Shift-1, a frontier coding router trained on AC2 that reduced coding agent cost by up to 55% with no noticeable drop in quality. Try it at shift.ac.
Okay this one is actually a banger. 🍴your way to SotA results...
Pushes way past stand-alone GRPO
Introducing Spork, an efficient post-training recipe which increases our solve-rate on chess puzzles by 100% when compared to our best GRPO setup.
It uses a GRPO warmup, splits task-specific datasets further into partitions, trains specialists, and then uses multi-teacher on-policy distillation. Like a Spork, it leverages gains by simply consolidating specialists.

Been awesome to see a leader like @rhythmrg sprint himself to get Decision Model training support in the platform. Super easy to use as well!

You can now train your own decision model in our platform AC2! Jev-like models, custom fit for your use case :)
We implement decision models through a language-model backbone with a small learned output layer called a decision head. The backbone processes the input, question, and answer choices, and the head produces scores which are softmaxed to produce a probability distribution over answer choices.
Our software interface makes it easy to add a variable-sized decision head to frontier open-weight models. Choose any open source model, and train it as a decision model using Brier loss or cross-entropy loss. Training updates both the decision head and the language backbone.
We tried it on 50k sampled training datapoints from the Civil Comments dataset, starting from Perplexity’s pplx-decider-v1-27b, and F1 for detecting toxic comments increased from 0.482 to 0.677 on 20k sampled eval datapoints. The training job took less than an hour on four B300 GPUs.
Reach out to get started with your own classification task: docs.appliedcompute.com/plat…

Super excited to share this work we've been doing at AC (major kudos to @AtharvNaphade)!
It allows us to take a legitimate step towards taking our hands of the wheels during model training. Looking forward to sharing more about how we were able to use it for automating a full end to end training loop 👀
We're sharing a key step towards enabling Continual Learning at Applied Compute.
In On-Policy Self-Distillation, the teacher model supervises training with privileged information: a hint. The training signal depends heavily on hint quality, but manually refining hints across runs is impractical, and isolating their individual impact is difficult. We instead optimize hints automatically using efficient proxies for their eventual training value.
Sam Denton retweeted

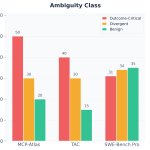
I implemented a system in @appliedcompute’s platform for automated failure mode clustering with Jev to surface errors at an even larger scale than before.
RL training produces billions of tokens in traces. I always manually read many traces to understand model behavior, but finding agent failures (like reward hacking / hallucinations) at scale is easy to miss without automation. Here’s how it works:
Working with @Drewch and the shopify team is awesome. Honestly never seen a group so customer obsessed and willing find the best path to delight them no matter what.
Plus an insane iteration speed by being so data + experiments driven!

@appliedcompute is the best actual Post-training/Finetuning company I came across in a long while. No relationship with them - just feel like people doing good job deserve a shoutout.
Onboarded to instinct recently. I told it to figure out if I needed to do anything to be able to drive in italy. It found me a AAA within walking distance for an IDP and also found out my rental car was booked for the wrong airport
Absolutely saved my ass.


2
20
1,818
Creating a platform that researchers actually want to use for training is quite hard, AC2 is our complete solution. Can't wait to see what people cook up!
@benscharfstein already trained away em-dashes
Today, we're introducing AC2, the Applied Compute Agent Cloud, to enable every team to train, serve, and improve their own frontier models.
1
39
1,907