




Pinned Tweet
1/11
Excited to share GENESIS, a generative model for predicting single-cell perturbation responses in unmeasured experimental conditions.
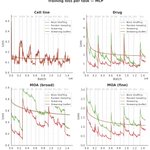
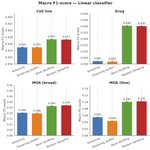
We show near-experimental-reproducibility performance, strong sample efficiency, and recovery of cancer signaling programs. 🧵

Sebastiano Cultrera di Montesano retweeted

Excited to join MLCB and present ChromCodes today at 4pm ET. One model that is interpretable, predictive and generative for regulatory DNA. Thanks for the opportunity and see you in person or online!


Here is the Live Stream!
youtube.com/watch?v=InMKK32q…

Sebastiano Cultrera di Montesano retweeted

How LLM Serving Actually Works
Ever wondered what happens behind the scenes when you work with LLMs?
In this video, let's explore the key techniques that make serving faster, cheaper, and more scalable.
Lots of topics, but it'll be a fun ride!
youtu.be/T4SRu-trimA
11/11 — Paper & Code
📄 Paper: biorxiv.org/content/10.64898…
💻 Code: github.com/rickconci/GENESIS
Feedback/thoughts are very welcome! @TBaharav @JiaqiZhangVic @uthsavc @jlaffy @jacksonweir4 @lucapinello @jkobject @arturszalata @doralidsy @JoshuaPickard_
Sebastiano Cultrera di Montesano retweeted

Come work with us and be our colleague!

If you'd like to come work with me and my amazing colleagues as a full-time researcher @MSFTResearch @MSRNE, please apply here:
apply.careers.microsoft.com/…
apply.careers.microsoft.com/…

Sebastiano Cultrera di Montesano retweeted

Our postdoc application is now open! Interested in pursuing #machinelearning, #appliedmathematics, #statistics, or #computationalresearch to work on biomedical problems at the @broadinstitute? Apply to become a @Schmidt_Center postdoctoral associate: broad.io/ewsc-postdoc


Sebastiano Cultrera di Montesano retweeted

On Tahoe-100M, a dataset of 100 million cells, scDataset achieves more than two orders of magnitude speedup compared to true random sampling while working directly with AnnData files.
Sebastiano Cultrera di Montesano retweeted
scDataset, a PyTorch data loader that enables efficient training from on-disk data with seamless integration across diverse storage formats. It combines block sampling and batched fetching to achieve quasi-random sampling that balances I/O efficiency with mini-batch diversity.
Sebastiano Cultrera di Montesano retweeted
scDataset: Scalable Data Loading for Deep Learning on Large-Scale Single-Cell Omics arxiv.org/abs/2506.01883
