

Researcher of AI. Assistant Professor @Tsinghua_Uni. Working on scalable methods of language and physical models @naturewill
Earth
Joined May 2015
- Tweets361
- Following420
- Followers7.6K
- Likes1.2K
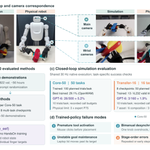

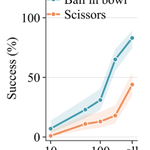


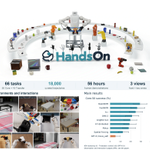

General models with dexterous manipulation is coming into view like @naturewill 's Natura-1. We need benchmarks ready to measure progress as these capabilities develop.
We introduce HandsOn, a simulation platform and benchmark for generalizable dexterous manipulation.
It brings together 66 human-verified tasks and 18,000 curated human demonstrations, covering tool use, precise interaction, articulated objects, and bimanual coordination.
We evaluate diffusion policies, vision-language-action models, world-action models, and LLMs to study how they handle these interactions.
Alongside success rates, we examine where execution breaks down: establishing the right contacts, coordinating actions, and maintaining achieved goals.
The paper, code, and dataset are available below.

We evaluate GPT-6 Astra through move_eef, an interface for specifying palm poses and individual finger-joint targets.
It receives images, measured robot state, instructions, and execution feedback, without HandsOn demonstrations or fine-tuning.
Across 660 trials:
• Core-50: 26/500 successes — 5.2%
• Transfer-16: 3/160 — 1.9%
Saved action notes contain examples of task-aware planning, including in unsuccessful trials.
This is a separate controller setting with different observations, trial counts, and model-call budgets from the trained policies. The results characterize GPT-6 Astra together with this minimal interface.

We include qualitative real-robot rollouts of policies trained with simulation demonstrations. These illustrate transfer to the physical platform; quantified physical evaluation remains future work.
The public release provides the task environments, success checkers, evaluation tools, and PhysX demonstration dataset.
We hope HandsOn will be useful for developing dexterous policies and studying how data, representations, and control interfaces affect reliable manipulation.
Project: llltttwww.github.io/HandsOn-…
Paper: arxiv.org/abs/2610.26765
Code: github.com/TsinghuaC3I/Hands…
Dataset: huggingface.co/datasets/Cyan…
We welcome additional policy evaluations, task contributions, and feedback from the community.

Ning Ding retweeted

我搞了一个【人味儿】Skill,欢迎大家尝试:github.com/yinfangchen/renwe…
可以把中文文本去AI味儿,也可以模仿/增强你的AI味儿。
Another Skill inspired by this paper for improving English text:github.com/inflab-asu/readab…

Ning Ding retweeted

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4

Ning Ding retweeted

Congrats to @naturewill on launching Natura-1. Proud to see WUJI Hand 2 powering the physical execution across these diverse tasks.

Introducing Natura-1, our first general foundation model for the physical world.
It follows natural-language instructions zero-shot and turns them into action with dexterous hands.
Natura-1 is a 50-billion-parameter mixture-of-experts (MoE) model pretrained on one million hours of egocentric human experience.
On top of this foundation, we conduct efficient post-training on a limited amount of robot data to adapt pretrained world knowledge to dexterous manipulation, yielding a model that generalizes to a wide range of unseen scenarios.
Natura-1 follows complex natural-language instructions zero-shot, reasoning through spatial constraints, multi-object relationships, and negative conditions.
It can also autonomously carry out long and continuous workflows to perform long-horizon executions.
Natura-1 provides early evidence that generalization—and even emergent behavior—can coexist with the complexity of dexterous hands.
Further progress depends on the full stack: infrastructure for faster training and real-time inference, pretraining data at greater scale and coverage, and models that transfer to robots with less adaptation.
We expect it to be a long-term research and engineering effort.
Ning Ding retweeted

Most "general" robot models quietly settle for simple grippers. Nature Will went the hard way.
Natura-1: a 50B mixture-of-experts model trained on 1 million hours of human video, driving 20-DoF five-finger dexterous hands at a 100ms control loop.
It follows plain-language instructions zero-shot, runs multi-minute workflows (folding wontons, calligraphy), and even improvises, using a rod to drag an out-of-reach basket closer.
On their own benchmark, gripper-based baselines (pi-0.5, GPT-6-Astra) barely scored. Natura-1 roughly 4x'd them, with five-finger hands.
Autonomous 1x wonton folding:
Introducing Natura-1, our first general foundation model for the physical world.
It follows natural-language instructions zero-shot and turns them into action with dexterous hands.
Natura-1 is a 50-billion-parameter mixture-of-experts (MoE) model pretrained on one million hours of egocentric human experience.
On top of this foundation, we conduct efficient post-training on a limited amount of robot data to adapt pretrained world knowledge to dexterous manipulation, yielding a model that generalizes to a wide range of unseen scenarios.
Natura-1 follows complex natural-language instructions zero-shot, reasoning through spatial constraints, multi-object relationships, and negative conditions.
It can also autonomously carry out long and continuous workflows to perform long-horizon executions.
Natura-1 provides early evidence that generalization—and even emergent behavior—can coexist with the complexity of dexterous hands.
Further progress depends on the full stack: infrastructure for faster training and real-time inference, pretraining data at greater scale and coverage, and models that transfer to robots with less adaptation.
We expect it to be a long-term research and engineering effort.
Ning Ding retweeted

Robot hands have always been the hard part. Picking something up is easy. Putting glasses into a case the right way around, while the other hand holds the case open, is not.
@naturewill just released Natura-1, a foundation model built for the physical world.
🤝 Paid partnership
Introducing Natura-1, our first general foundation model for the physical world.
It follows natural-language instructions zero-shot and turns them into action with dexterous hands.
Natura-1 is a 50-billion-parameter mixture-of-experts (MoE) model pretrained on one million hours of egocentric human experience.
On top of this foundation, we conduct efficient post-training on a limited amount of robot data to adapt pretrained world knowledge to dexterous manipulation, yielding a model that generalizes to a wide range of unseen scenarios.
Natura-1 follows complex natural-language instructions zero-shot, reasoning through spatial constraints, multi-object relationships, and negative conditions.
It can also autonomously carry out long and continuous workflows to perform long-horizon executions.
Natura-1 provides early evidence that generalization—and even emergent behavior—can coexist with the complexity of dexterous hands.
Further progress depends on the full stack: infrastructure for faster training and real-time inference, pretraining data at greater scale and coverage, and models that transfer to robots with less adaptation.
We expect it to be a long-term research and engineering effort.
Ning Ding retweeted

Full demos of six real-world tasks, all performed by Natura-1.
Everyday work involves more than picking and placing rigid objects.
Natura-1 demonstrates sustained autonomous execution across workflows that combine precise manipulation with multi-step coordination.
Ning Ding retweeted

Okay, this one is personal. A senior of mine is building @naturewill, so I'm absolutely going to hype this launch.
Natura-1 is genuinely impressive. Robotics has a brutal scaling problem: collecting high-quality robot trajectories is expensive, and robots cannot easily gather experience in environments they haven't already mastered. Humans, on the other hand, generate enormous amounts of physical experience every day.
Their approach is fascinating: pretrain a 50B MoE on one million hours of egocentric human experience, then adapt that knowledge to dexterous robot manipulation with relatively limited robot data.
What caught my attention as an inference engineer is the full-stack work behind it. A powerful model is only part of the problem. They also built the training and serving infrastructure to run a continuous observation-to-action loop within 100ms. In robotics, even a correct decision can become useless if it arrives too late.
There is still a long way to go toward general physical intelligence, but this is a seriously ambitious step. Huge congratulations to my senior and the entire Nature Will team! Go watch their demos.
Introducing Natura-1, our first general foundation model for the physical world.
It follows natural-language instructions zero-shot and turns them into action with dexterous hands.
Natura-1 is a 50-billion-parameter mixture-of-experts (MoE) model pretrained on one million hours of egocentric human experience.
On top of this foundation, we conduct efficient post-training on a limited amount of robot data to adapt pretrained world knowledge to dexterous manipulation, yielding a model that generalizes to a wide range of unseen scenarios.
Natura-1 follows complex natural-language instructions zero-shot, reasoning through spatial constraints, multi-object relationships, and negative conditions.
It can also autonomously carry out long and continuous workflows to perform long-horizon executions.
Natura-1 provides early evidence that generalization—and even emergent behavior—can coexist with the complexity of dexterous hands.
Further progress depends on the full stack: infrastructure for faster training and real-time inference, pretraining data at greater scale and coverage, and models that transfer to robots with less adaptation.
We expect it to be a long-term research and engineering effort.
Ning Ding retweeted

It is actually a great great experience to be the first person to play with Natura-1 long-shot.
Learning how a model/robot acts is like learning how to chat with you agent, you are gonna find the best ways to communicate with each other.
Natura-1, my first intelligent friend.
Some work seems to be what we’ve done before.
Building efficient infrastructure. Collecting a lot of data, then a lot more. Running ablation after ablation to understand what the model should actually look like. Debugging software and hardware, again and again. The unglamorous work of processing data. Training in parallel, at scale, on a lot of compute.
Yet somehow, they all seem so different.
This field hasn’t converged yet, and much of the infrastructure and many of the methods had to be figured out again.
Nothing was mature. Software and hardware were unstable in countless ways, and had to be made to work together. The architecture for a new kind of model had to be explored from scratch. There was no training recipe to refer to. And every bit of grunt work needed someone watching over it.
This time we get to watch the result work right in front of us.
Introducing Natura-1, @naturewill's first general foundation model for the physical world.
It is a single model that follows plain-language instructions zero-shot and carries them out with dexterous hands.
- 50B MoE, pretrained on 1M hours of egocentric human experience.
- Drives 20-DoF dexterous hands from plain language, zero-shot, in a 100ms loop.
- Scaling human data from ~44K to 1M hours cut action MSE on held-out robot data by 67.7%.
- Built on in-house data and compute infra, it handles fine-grained long-horizon tasks and a ~30-minute zero-shot interaction in one continuous take.
The general model exists, and it can only get stronger.
naturewill.com/blog/natura-1…
Ning Ding retweeted
30 minutes. One take. No cuts.
We put Natura-1’s zero-shot generalization to the test with complex spoken instructions and unfamiliar tasks and environments.
It responds to new requests, adjusts and retries when an action fails, and keeps going autonomously.
Ning Ding retweeted
With task-specific tuning, Natura-1 demonstrates sustained autonomous execution across workflows that combine precise manipulation with multi-step coordination.
The six demos below show continuous, single-take autonomous workflows, several lasting multiple minutes without human intervention.
Each requires a single policy to coordinate precise, dexterous actions across multiple steps and carry the task through from start to finish.