

Writing and conversations on frontier technology.
San Francisco, CA
Joined July 2026
- Tweets15
- Following20
- Followers520
- Likes75




Substrate retweeted

on llms eating robotics via direct control:
fable 5.2 robotics demos run at 60x speedup because inference is so slow on huge models, but there's no practical way to run trillions of params on-device with 128gb chips
distilling a 5-10T params to 5-10B is not guaranteed, it could erase the model's generalization capabilities


Will LLMs eat robotics?
Many say frontier labs will win by distilling models to run at real-time. The story is more complex, and one critical piece is simulation.
Closing the sim-to-real gap creates a recursive loop for robotics models.
I wrote for @substratemag:
substratemag.com/turning-com…

Simulation is the clearest way to scale robotics' biggest bottleneck: data. For years, the sim-to-real gap was too large to overcome. Now, we're starting to see it close
Recursive self-improvement isn't quite here for robotics, but simulation is key for its launch

Will LLMs eat robotics?
Many say frontier labs will win by distilling models to run at real-time. The story is more complex, and one critical piece is simulation.
Closing the sim-to-real gap creates a recursive loop for robotics models.
I wrote for @substratemag:
substratemag.com/turning-com…
Substrate retweeted

Dylan, Dwarkesh, and Citrini stories are amazing examples of how you can still just do things in America. No elite pedigree: just hard work, chutzpah, and weaponized autism 🦾
I sat down with @dylan522p and spoke with over a dozen people about his information machine.
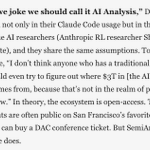
"I don't think anyone who has a traditional equity research background would even try to figure out where $3T in [the AI labs' combined] ARR comes from."
Slack private messaging limits, finding CoWoS volume, and the industry they're looking at next - I wrote about SemiAnalysis here: substratemag.com/dylanpatel/…

It's near-impossible to outbid the HBM shortage, but sidestepping it is a different question
GDDR usage, air-cooled PCIe cards, and alternative vendors can all help work around supply chain constraints
I interviewed @neilmovva for @substratemag on latency-insensitive inference, alternative chips, and why massive datacenters face diseconomies of scale.
"We've always predicted that async inference is going to eat the world. That could easily be 95% or more of inference demand."
Neil's been at the frontier of inference for years, from NVIDIA to co-founding @sailresearchco. I learned a lot from our conversation - you can listen below.
Substrate retweeted
the conventional view is that datacenters require reliability
but if your workload tolerated 95% uptime? 90%? you could move workloads between sites if the dc drops and take advantage of underutilized (cheaper) capacity
I interviewed @neilmovva for @substratemag on latency-insensitive inference, alternative chips, and why massive datacenters face diseconomies of scale.
"We've always predicted that async inference is going to eat the world. That could easily be 95% or more of inference demand."
Neil's been at the frontier of inference for years, from NVIDIA to co-founding @sailresearchco. I learned a lot from our conversation - you can listen below.
So long as the frontier labs charge premiums on tokens, they can always outbid startups for compute - for now, NVIDIA's goodwill keeps the ecosystem running
I interviewed @neilmovva for @substratemag on latency-insensitive inference, alternative chips, and why massive datacenters face diseconomies of scale.
"We've always predicted that async inference is going to eat the world. That could easily be 95% or more of inference demand."
Neil's been at the frontier of inference for years, from NVIDIA to co-founding @sailresearchco. I learned a lot from our conversation - you can listen below.
12
1,000
On modular datacenters:
NVIDIA has been piloting modular (5-20mw) datacenters, and SemiAnalysis predicts they'll make up 31% of capacity by 2028.
A big reason why is lead time. 50mw-100mw datacenter lead times are 12-24 months. For <1mw datacenters, 16 weeks
I interviewed @neilmovva for @substratemag on latency-insensitive inference, alternative chips, and why massive datacenters face diseconomies of scale.
"We've always predicted that async inference is going to eat the world. That could easily be 95% or more of inference demand."
Neil's been at the frontier of inference for years, from NVIDIA to co-founding @sailresearchco. I learned a lot from our conversation - you can listen below.
"There's no stranded compute for us anymore."
Most inference providers avoid stranded capacity. Its reputation for unreliability is well-earned. But if you drop latency requirements for background workloads, you'll unlock pools of compute no one else has at prices no one can beat.
Interactivity is expensive. Throughput is cheap.
@cattttang spoke with Sail Research co-founder Neil Movva on latency-insensitive inference, alternative chips, and <1MW datacenters.
Full conversation below.
I interviewed @neilmovva for @substratemag on latency-insensitive inference, alternative chips, and why massive datacenters face diseconomies of scale.
"We've always predicted that async inference is going to eat the world. That could easily be 95% or more of inference demand."
Neil's been at the frontier of inference for years, from NVIDIA to co-founding @sailresearchco. I learned a lot from our conversation - you can listen below.
6
539
Substrate retweeted

I find it surprising that less than 5% of SemiAnalysis' revenue comes from Substack. They are incredibly popular...thought it would be higher.

@SemiAnalysis_ rose to fame from its Substack, but the newsletter only makes up <5% of revenue - their product expansion into models, institutional research, benchmarks, etc. has been massive

1
7
527
In just a few years, @SemiAnalysis_ has risen to the forefront of AI infrastructure information, with their work referenced by some of of the biggest players in semiconductors.
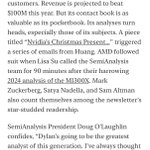
The prediction: "@dylan522p's going to be the greatest analyst of this generation."


I sat down with @dylan522p and spoke with over a dozen people about his information machine.
"I don't think anyone who has a traditional equity research background would even try to figure out where $3T in [the AI labs' combined] ARR comes from."
Slack private messaging limits, finding CoWoS volume, and the industry they're looking at next - I wrote about SemiAnalysis here: substratemag.com/dylanpatel/…
13
829
Welcome to Substrate Magazine. Substrate covers frontier technology, from RL algorithms to DRAM supply chain.
@SemiAnalysis_ is the leading information firm in the largest infrastructure buildout in history.
We're excited to profile @dylan522p for our first piece.
I sat down with @dylan522p and spoke with over a dozen people about his information machine.
"I don't think anyone who has a traditional equity research background would even try to figure out where $3T in [the AI labs' combined] ARR comes from."
Slack private messaging limits, finding CoWoS volume, and the industry they're looking at next - I wrote about SemiAnalysis here: substratemag.com/dylanpatel/…
11
657