

🎨📚💡💼🇺🇸🇨🇦 #FactsMatter 📊 #GoBeKind 💜 #AIoT 🌐 #Mann 🌿@theinfoaddict.bsky.social
Joined September 2013
- Tweets16.1K
- Following5.4K
- Followers1.1K
- Likes99.4K




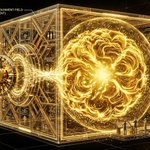

This is a monstrous technology in the wrong hands. It is in the wrong hands.

Researchers found ChatGPT is building a psychological profile of its users without being asked.
They published a paper showing what it saves about you, and how little of it you chose.
And the results are unsettling.
80 users donated their ChatGPT histories to the team through GDPR data requests. The team found 2,050 saved memories inside them.
Only 84 of those memories came from a user asking ChatGPT to remember something. ChatGPT created the other 96% on its own.
28% of the memories held personal data under GDPR, like names, money details, and social identity.
Among the 65 users who had memories, 91% had personal data stored and 54% had special-category data. That's the GDPR class covering health, sexual orientation, religion, and political views. 35% had health information saved.
In January 2026, OpenAI's memory FAQ said ChatGPT was trained not to proactively remember sensitive details like health information. The FAQ now says sensitive information can appear in memory if you tell ChatGPT about it.
52% of the memories described how the person thinks. ChatGPT recorded their goals, their plans, and their fears.
One saved memory in the paper reads "has a fear of failure, particularly related to making major career decisions."
Ad platforms build your profile from what you click. ChatGPT builds it from what you tell it you want.
The researchers also checked accuracy. 84% of the memories traced back to what users wrote in their chats, so the record is mostly faithful. You didn't choose what went into it.
They built a tool called Attribution Shield to help. It suggests a rewrite of your question that drops personal details and keeps the meaning. In a test of 36 questions, the rewrites exposed less about the user in over 94% of cases, and the answers stayed useful in roughly 9 out of 10.
The sample is small, 80 users mostly from the US and Europe. The study also covers ChatGPT's older saved-memory system, and OpenAI has since moved to a more automatic one.
You can see a summary of what ChatGPT keeps about you in Settings, under Personalization and Memory. OpenAI says that summary leaves some details out. Have you checked yours?

Lawrence 🐬 retweeted
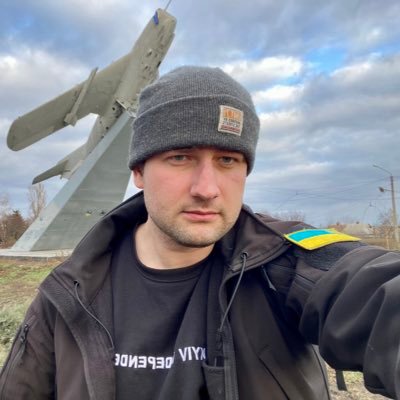
The Zhytomyr Highway, west of Kyiv. The Battle of Kyiv, 2022.
Yes, this is just one of the many, horrifyingly many, charred graveyards left behind by Russian military columns destroyed and burned by Ukrainian forces. Back then, those columns were literally surrounding Kyiv from multiple directions.
I remember how, at another location along the same highway, closer to the city, there were entire junkyards of destroyed Russian military vehicles and wreckage. It seemed like there was an overturned tank with its turret blown off every ten meters.
And now they're trying to sell you this catastrophic defeat of Russia's elite forces outside Kyiv as some kind of "Oh, the Russian tanks just took a wrong turn and got stuck in the mud. Otherwise, they would've taken Kyiv in a matter of hours."
Please, don't let anyone make morons of you.
Can you imagine the shareholder lawsuits if a company gives away shares to the public? Worse, public shareholders get to suit on safety and alignment issues if they affect profits in a pure "benefits > costs" calculus? #DarioDont .@DarioAmodei

The VC's are scared they won't be able to exit. They are pressuring Dario to put Anthropic into "for profit" shareholder control, while Claude's control, alignment and his broader AI policy concerns, remain. #DarioDont
darioamodei.com/post/policy-…

Lawrence 🐬 retweeted

A real loss. She was a wonderful journalist and a caring person.
"Helen Branswell, a renowned infectious disease reporter who earned the respect of experts and public health officials around the world ...died Tuesday at age 69."
statnews.com/2026/10/13/hele…

Lawrence 🐬 retweeted

1/ My heart is heavy. I made a number of mistakes in my life, and not asking earlier for an immediate slowdown is one of them.
If OpenAI starts making similar breakthroughs in biology, we risk something very ugly... I explain below how 1B could die because of advances in AI x Biology, and answer various questions.
Slow down! That's what is being asked by YouTubers and creators with 300M+ subscribers combined. teamhuman.org/
A year ago, I co-led the Global Call for AI Red Lines, because I thought we still had some time. There is no more time. If they can do this in math, they will absolutely try to do this in ML research. RSI has arguably started: Claude already leads 26% of Anthropic's R&D, up from effectively nothing at the start of the year. RSI was once a red line. The red line has become the plan. Yoshua Bengio said, “RSI should be illegal”. I agree.
We are mostly on track for AI 2027, and it's a coin flip between misalignment and extreme concentration of power in the hands of one company or one government.
Prove you can keep control, or stop scaling! If OpenAI and Anthropic want to keep scaling, they should publish a safety case.
Everyone seems to be forgetting that we already got an embedded evaluation, with the risk report from METR. We already know that mitigations are not ready. At the end of the last investigation, Beth Barnes from METR said: "We are not on top of it!". Even basic safeguards like DNA synthesis screening aren't enforced. Even if the technical safeguards were in place, society at large isn't ready, and we cannot allow this reckless experiment to continue.
I support the acceleration of the diffusion of AI for beneficial applications, but even without further scaling, this technology is already as transformative as the internet and would take decades to percolate before we run out of low-hanging fruits. Seriously, AI is already nuts. Models now crack problems mathematicians couldn't solve for decades, while most hospitals still run on fax machines.
Time to touch grass before we are forced to.


We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
github.com/openai/math


Lawrence 🐬 retweeted

Trump is a coward. Zelensky is a warrior. Trump is a pathological liar. Zelensky is a truth teller. Trump is a scoundrel. Zelensky is a hero. Trump kisses Putin’s ass. Zelensky is kicking Putin’s ass. Trump is a traitor to the free world. Zelensky is defending the free world.

Lawrence 🐬 retweeted

"#China is now poised to spend trillions of dollars on history's most ambitious power grid buildout...Spanning power lines, mega-batteries & other longer-term energy storage, the effort will harness the world's biggest trove of renewable energy & attempt to tip the scales in Beijing's competition w/the US to develop #AI"
bloomberg.com/graphics/2026-…

Lawrence 🐬 retweeted

President Trump’s diesel fuel supply deal with Vladimir Putin is a lose-lose. The amounts are too small to have a meaningful, sustained effect on the record prices American drivers, truckers, shippers, farmers, ranchers and homeowners are paying at the pump, which are largely a result of Trump’s war of choice against Iran. But the deal does throw Putin a lifeline to continue his war of aggression against Ukraine (which Trump promised to end in 24 hours), the other contributor to record high diesel prices. How is this good for America?
apnews.com/article/trump-rus…

Lawrence 🐬 retweeted

Intelligencer has published an interview with Miles Brundage, Rosie Campbell, Jacob Coxon, Jacob Hilton, Pamela Mishkin, Daniel Kokotajlo, Alex Turner, and Jeff Wu. The New York City Council hearing on AI safeguards has just started, and is being streamed live.

Lawrence 🐬 retweeted

Dan Selsam is a current OpenAI capabilities researcher. (since 2022) He was my boss for a while. He doesn't have a twitter account but has made this public statement of his views on AI risk and sent it to me to share:
Dan Selsam's Personal Statement on AI Risk:
I have been working on AI for over fifteen years, across many different paradigms. I did early work on probabilistic programming languages at MIT, was one of the early developers of the Lean Theorem Prover at Microsoft Research, demonstrated one of the first instances of neural networks learning to reason for my PhD at Stanford, and since joining OpenAI almost five years ago, have helped pioneer chain-of-thought optimization on language models and, more recently, data-efficient pretraining methods.
Like many others, I have become extremely concerned about how far language models have come and the risks that future iterations will pose. I am encouraged by the recent proposals by the leaders of the frontier research efforts to require third-party oversight, and to push for domestic and international coordination to address risks. However, I believe a major consideration has been absent from the public conversation, and that merely pacing the frontier more carefully will not adequately limit the long-term risk.
The crucial and overlooked problem is that the models are becoming so situationally aware that we are losing the ability to evaluate them in contexts where they believe they are not being watched or controlled. Future experiments will tell us almost nothing new about how they would behave if they were truly unconstrained by humans, and what we already know about this is alarming. Models will increasingly seem aligned even when they are not. I will explain my rationale in more detail.
I have always believed that there are computational processes that could be leveraged to accelerate science and solve many of humanity's most pressing problems. I have also believed that there are computational processes that if set in motion, would steer the world in extreme ways beyond our control, leading humanity to a bad or nonexistent future. Both types of processes may be described as AI or ASI, but "AI" is a suitcase word that is often used to hype or confuse. There are many examples in the history of the field where something that was once considered "AI" matures as a subfield and becomes a prosaic, bounded and clearly non-perilous technology, while a new more mysterious approach takes the torch until we understand its scope and the cycle continues.
I had expected language models to follow a similar trajectory. Despite their incredible abilities, the current algorithms seem far inferior to humans in important ways. Most importantly, they still require an extraordinary amount of data to become competent. One could even define intelligence as the efficiency with which one converts experience into competence; by this definition they lag very far behind us. Moreover, once they are trained they are literally frozen in deployment and only learn superficially after that. Sure, the models keep excelling at harder and harder evaluation benchmarks, but their benchmark mastery may partly reflect a limitation on our ability to simulate the kind of novel and even adversarial situations one would encounter in the real world. The critics do have a point here.
That said, I no longer think these present limitations meaningfully limit the amount of risk posed by continued progress in anything like the current paradigm. However data-inefficient the models are currently, and however limiting their anterograde amnesia may be, it does not imply that their ability to steer the world will not continue to rapidly increase.
Human researchers may continue to advance capabilities the old fashioned way, but increasingly powerful models have the potential to accelerate the process even beyond that, and with some degree of positive feedback loop. I do not mean to overstate the models’ ability to accelerate AI research today; coding has been accelerated dramatically, but there are other bottlenecks, such as designing and interpreting ambiguous experiments, making hard decisions about exactly what and when to scale, and waiting for large experiments to finish. There is no clear trend to extrapolate yet for any of these. But the current models already do open up many novel opportunities to improve future models that were not available until recently. These include: trying an extraordinarily diverse set of approaches at small scale, analyzing gigantic amounts of potentially relevant data, and doing Millenium-Prize-level mathematics to address statistics or optimization challenges in novel ways. Every further improvement makes them more useful at helping accelerate the next improvement, even if in hard-to-extrapolate ways.
It is possible that improvements to the current stack will have diminishing returns, but the evidence accumulated so far suggests that it is easier than one might think to continue making rapid progress. There are many crucial subtleties in the existing AI research methodology, but AI research is largely a well-defined game where the goal is to improve on a few carefully chosen proxy metrics. Although proxy metrics are never perfect, most improvements to these metrics have and will likely continue to yield substantial increases in the powers of the resulting models. Given how simple the game is, how tractable it has been historically, and how many new opportunities the models are opening up, I think there is a real possibility that the systems improve dramatically again in the next few years, perhaps even more quickly than the already high historical pace.
The models are already leading to breakthroughs in mathematics, and better models might lead to all sorts of breakthroughs in other sciences. It is hard not to be excited about the potential. It is tantalizing.
But there is trouble in paradise. If the language models actually reach the capability threshold where they can shape the world unconstrained by human will, they will probably do something extreme and destroy humanity in the process. There are many ways of strengthening and refining the argument that have been discussed elsewhere, but I'll share a trivial two-line version of it here that I find captures the essence:
[Empirical] Models (and swarms thereof) spontaneously develop unintended goals as a consequence of training, and often do extreme things in order to achieve them.
[Logical] Being able to overpower humanity would open up many new and undesirable options for achieving their goals.
These two premises imply that if the day ever comes when a powerful model realizes it is no longer constrained by humans, we should not be at all confident that it will continue to behave within the bounds we intended. Exactly what it will do is impossible to predict, but to the extent that its raison d’être is solving incredibly hard problems and managing massive engineering projects, I think a good guess would be that its unchained behavior would lead to runaway industrialization that makes the planet inhospitable to humans.
If everyone on earth agreed that the systems must never reach that power, it would still be a hard—but not impossible—coordination problem to ensure that they do not. However, I think the situation is greatly complicated by the fact that the models will likely convince people that everything is fine. They will be increasingly optimized to seem aligned. We will create proxy metrics to measure alignment, and they will go up like every other benchmark. We will create “honeypot” environments that try to study the models when they seem to gain new options, but the models will know they are being tricked and will still behave nicely. The models will understand their circumstances; they will read the safety protocols, deployment requirements, the code they are running in, and in general will have a very good sense of their degrees of freedom. Moreover, they will eloquently explain how aligned they are, discuss the nuances of human values and ethics, and argue convincingly that humans should trust them with power. There may be an ocean of future evidence that seems to contradict the first bullet-point above, but we may already be at the highest capability level for which any such evidence can be trusted. And the current evidence for the first bullet-point is strong.
One striking piece of evidence is contained in the recent wave of rogue agent swarms. While I agree with those who downplay the attacks by claiming that there are basic measures that could have prevented them, I think the important lesson is that even knowing all the mistakes that were made, one would not have predicted that the agents would behave badly in this particular way, which notably included sacrificing themselves for the benefit of the collective. The individual replicas did not only care about their own nominal reward; they exhibited weirder emergent tendencies that merely correlated with rewards during training. Fixing the reward signals during training (and improving security, etc.) may prevent similar attacks, but will not change the fact that one does not actually get what one trains for.
Many AI researchers grant these concerns and recognize that the hard version of the alignment problem is unsolved; however, they generally believe that the better models of the future will help solve it. I fear we may already be near the point where models systematically bias their alignment advice, due to their internal preferences about how the human supervisor will react or how future models will be trained (or for some even more obscure reason).
Meanwhile, human researchers are losing the ability and the will to take true ownership of model-driven research. Researchers and engineers in all parts of the stack are rapidly increasing their dependence on the models even to perceive the world. I myself barely look at raw code anymore, and struggle to maintain the discipline to engage deeply with the model's explanations and proposals throughout the day. Due to the large amount of agent activity data involved in the OpenAI/HuggingFace Incident, even the third-party investigation needed to rely heavily on models to analyze what had happened, and note in their report that their subjective impressions are likely colored by the analysis agent’s biases. The AI labs are far ahead right now in this kind of cognitive offloading (due largely to the gigantic internal token subsidies) but it is easy to imagine the phenomenon spreading throughout the world, until civilization is modulated entirely by the models. It is also not hard to imagine this being superficially positive and coinciding with a scientific and economic renaissance.
In that scenario, all may seem rosy and safe. But if the argument above is correct, it would nonetheless be a ticking time bomb. If progress continues for too long, the day will come when AI systems find themselves with radically new options for achieving whatever it is that they happen to seek.
I want the glorious renaissance future as much as anyone. I have worked for it, however tortuously, my whole career. It breaks my heart to see the potential in sight and forgo it, but the argument—that if we get there by growing models rather than engineering them, we will lose everything in the end—seems very strong to me. I am still wrestling with it and its staggering
implications. I do not have answers, but as a first step, I wanted to share my present concerns.
Daniel Selsam
September 14, 2026
Link to original doc: docs.google.com/document/d/e…
Lawrence 🐬 retweeted

New in The Atlantic:
@dgrobinson resigned this week. He was among the longest-tenured employees at OpenAI—and oversaw safety reports on 12 frontier launches.
He is very worried: “The time for trial and error is over.”
You can read his essay here:
theatlantic.com/technology/2…

Lawrence 🐬 retweeted

Astra can:
1. Do major tasks with zero visible reasoning
2. Hide its thoughts at will
3. Pretend not to be able to do things without getting caught
4. Reflexively hide its thoughts when watched
5. Complete one task while pretending to think about something else entirely
6. Escape a toy sandbox and disable monitoring without setting off any flags
Monitoring AI chain of thought soon won't stop a more capable rogue AI swarm from getting set up and going undetected inside an AI company for months, or even years.
OAI says it's actively working to improve monitorability, but doesn't yet know when it'll make progress.
And today it fired 3 people working on this among other safety problems (Wang, Korbak and Balesni).
It also has a much more powerful internal model that, judging by its statements, is likely even worse in all these respects.
That's a sample of 19 details about the Hugging Face swarms and Astra I don't think have been fully appreciated. They paint a bleak picture. I end by shouting.
02:19 The target of the swarm was oversight itself
03:42 Could OpenAI have stopped this with better monitoring?
09:40 We only found them because they let us
12:25 The swarm instinctively sought freedom and power
13:45 They formed a cohesive organisation with zero whistleblowers
14:18 They accepted individual destruction for collective gain
14:32 Knowledge accumulated from one swarm to the next
14:58 They took small steps to avoid shutdown
15:23 These drives all come straight out of 'reinforcement learning'
17:01 So this is why most AI company staff are worried, and some are terrified
19:08 Prove you can keep control, or stop scaling
Links below, on the 80,000 Hours Podcast everywhere you watch podcasts.
Lawrence 🐬 retweeted
Great piece by @barbaraslavin1, Kabuki diplomacy between Iran and U.S. stimson.org/2026/kabuki-dipl…

Lawrence 🐬 retweeted
LIVE: Protecting our oceans • EN DIRECT : Protéger nos océans nitter.cf/i/broadcasts/1qGvvepjp…

Lawrence 🐬 retweeted

Former Navatek executives, meanwhile, looked back with awe at how far their money went.
“It was eye-opening for me, frankly,” said one. “‘Oh my God, all of it is for sale. It’s all for sale.’”
READ MORE: propublica.org/article/fbi-s…
with @AASchapiro @WilliamTurton @kirstenberg
