

Building the neovim of agent harnesses. bone-agent. 2x3090 96gb ddr5 local machine. 26, swe in finance.
New York, USA
Joined April 2026
- Tweets3.9K
- Following380
- Followers402
- Likes3.4K




Pinned Tweet
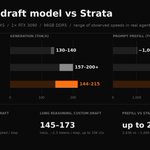
Qwen3.8 flash at 150–177 tok/s gen and ~1,900 tok/s prefill on 2x 3090s + 96gb ddr5
bone engine, my own inference engine. 256k context, single stream or 4x concurrent (50ts a stream, up to 256k)
vs strata engine on the same rig: 120-140gen, 1k pp → 150-170gen, 2k pp
iq3_xxs quant, so not full precision, will optimize q4 once qwen 4 drops. Model is leftover from when i had less ram.

I saw a post mentioning giving local models skills to get then closer to frontier. So i did hust that, gave Qwen Flash, iq3_s six engineering skills and A/B tested it vs no skills.
Coding tasks: 100/100 on hidden tests/debugs either way. Skills did make diffs ~25% smaller.
Then one 3js: "realistic grass in the wind, three.js"
Top: no skills. Bottom: with skills.
Made no measurable difference. One came out good one came out bad.
1
105


Ill be remembered at my first job as the guy who was excitedly showing everyone how he prompted an ai to open and write into a notepad in 2024
1
2
68
Rambone retweeted

I am so happy to finally be able to announce my game!
SEND MORE MEN
This is a game I've always wanted
Any army, any era, up to a thousand men on one field.... multiplayer, full customization, and every soldier thinks for himself
Wishlist it on Steam (link in the comments).
Ahaha it worked flawlessly. Perfect arch setup everything just works. I did it all over ssh phone -> desktop -> laptop
Qwen flash is currently mirroring my configs over to my laptop. All I did was partition the ssd, install arch, install sshd and tailscale, and point my harness as it and said "copy yourself onto this archive machine".
Its ripping through stuff. All I have is a terminal, will update if it actually works.
1
2
98
Qwen flash is currently mirroring my configs over to my laptop. All I did was partition the ssd, install arch, install sshd and tailscale, and point my harness as it and said "copy yourself onto this archive machine".
Its ripping through stuff. All I have is a terminal, will update if it actually works.
>be me
>scrolling X
>see guy post his "inner circle" pic
>40 tiny pfps orbiting his face like moons
>search for my pfp
>not there
>zoom in
>still not there
>i have never spoken to this man
>he doesn't know i exist
>i don't know what he posts about
>still devastated
>check the next guy's inner circle
>not there either
>mfw i'm in nobody's inner circle
2
7
322
Same voxel mansion prompt, three flash models, reasoning on high. Claude Fable 5.2 in Claude Code for fun.
- DeepSeek Flash: 59m, 95 tool calls, 107k out. Best looking of the three, but I stopped it before it finished, got stuck on the headless browser screenshot (my fault)
- MiniMax M3.1 Flash: 23m, 90 tool calls, 83k out. Completed, and the cleanest finished build.
- Qwen3.8 Flash iq3xxs: 25m, 81 tool calls, 113k out. Completed, but the most blocky and the least detailed.
I did one run each, and Fable's tokens and time weren't logged, so it's a visual reference of what's possible.
Prompt was the same, one shot in the bone harness. Really impressed with deepseek, it nailed lighting. Really unimpressed with minimax. Qwen is very solid for a quant running local.
Which one is your fav.


3
3
146

Just ran qwen flash with no thinking vs med. 999 tool calls vs 56 on med. Same task. Doing the same test on all levels out of curiosity
40
I remember reading on reddit a year ago that thinking models were a gimmick and they performed better with thinking off.
2
2
83
