
LLM Evals Engineer | Love reading, writing ✍️ | Currently building with LLMs & AI Agents Tech
Beijing
Joined August 2011
- Tweets1.3K
- Following1.4K
- Followers1.2K
- Likes2.3K




17Ge retweeted

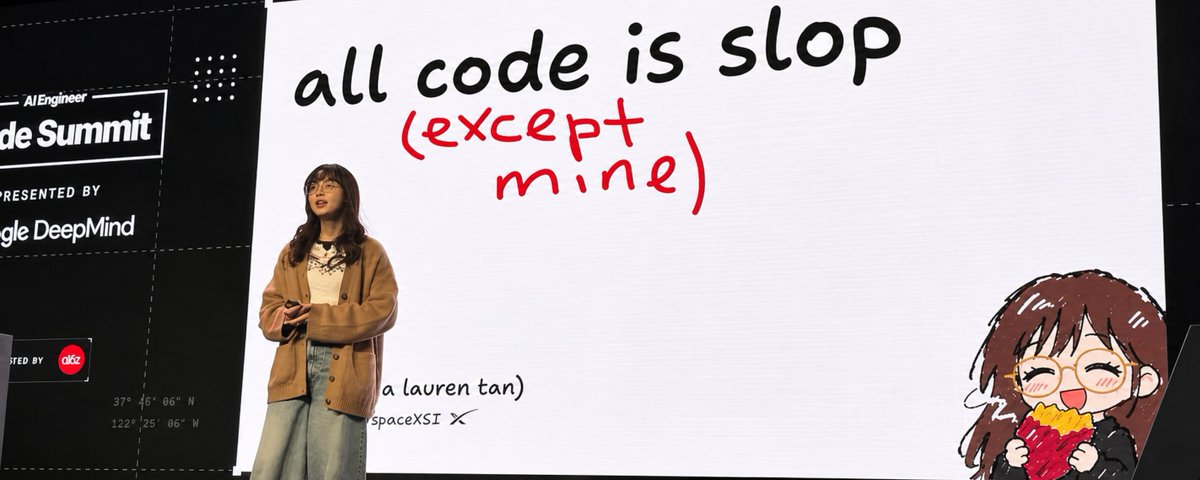
All code is slop, except mine
That’s what Lauren Tan, the engineer behind Grok Bot, said on stage
She ships 3,000+ pull requests a month, and her secret is what she does every time an agent makes a mistake
Most people just add another line to AGENTS.md
Lauren runs every mistake through 4 questions instead:
> Can I redesign the code so this mistake is impossible?
> Can a lint rule or a type catch it automatically?
> Can the agent catch it by running and checking its own work?
> Does it really need a written rule?
Each mistake gets one of 5 fixes:
Redesign / lint / verify / write a rule / human review
The useful part is that a written rule is only one option, not the default
Most of her fixes never touch AGENTS.md at all
> Sometimes the answer is to ban something entirely, like useEffect
> Sometimes it’s a lint rule: her team went from 7 to 167 of them in four months
> Sometimes it’s letting the agent prove its work with screenshots
Mistake -> cheapest permanent fix -> never catch it by hand again
Lauren’s all rules:



Built a real-time speech simultaneous interpretation app from scratch with @Google gemini-3.8-Live voice model, and the result is absolutely amazing. The continuously growing capabilities of these models open up far more room for imagination.
github.com/wangwei1237/f2ft

1
42
AI时代下,我们一直在讲AI组织提效,AI组织资产,但是如何衡量整个过程做的好不好呢?用 Agent 代码生成占比?全 AI 交付需求占比?这些数据好像都可以被刷榜,只要愿意,甚至什么都不需要改变也能达到一个比较高的水平。OpenAI 给了一个线索:进入开发阶段之后,one-shot 需求占比,也就是进入开发阶段后,用 Agent 一把梭哈、没有任何人工干预的的需求占比。
1
30
17Ge retweeted

Still driven by the same dream.
Let's make ERNIE great again!

ERNIE 5.5 Flash Preview just landed! 🔥
Built on a new architecture designed for efficient inference, the latest open-weight foundation model in the ERNIE family delivers stronger performance in coding, 3D modeling, knowledge work and content creation.
It keeps decoding fast while posting competitive scores on Terminal-Bench, AutomationBench, and other benchmarks.
Here's the rundown:
- 280B total parameters, 14B active per token
- 1M-token context window
- Generation speed above 200 tokens/sec
Model weights will be released by November 25.

17Ge retweeted
Accelerating... 🚀
Introducing ERNIE Evolve, our automated research system for improving AI training and inference. ⚙️
Given a clear research goal, it selects research directions, modifies code and runs experiments. Only improvements that pass independent evaluation and review are kept, and each round’s findings guide the next.
From public benchmarks to ERNIE 5.5 Flash inference tests, here’s what it achieved:
- SOTA on NanoChat AutoResearch and NanoGPT Speedrun
- 33.7% higher deterministic GPU inference throughput
- 14.9% faster single-request decoding on GPUs
This is a practical step toward recursive self-improvement (RSI). Next, we plan to extend this approach to training systems, model capabilities and evaluation.


17Ge retweeted
ERNIE 5.5 Flash Base just dropped! Time to open that project folder. 🚀
Our efficient sparse MoE language model draws on data spanning multiple domains and languages, achieving SOTA on multiple benchmarks among similarly sized base models. Its architecture and training system were designed together for efficient training and inference, with advances in attention mechanisms, expert routing, and training objectives:
- 280B total parameters; 14B activated per token
- Pre-trained on 33.5T tokens
- Up to 1M-token context for fine-tuning and inference
- FP8 and BF16 weights
The weights come straight from pre-training, with no mid- or post-training. Compare methods from the same checkpoint, measure what each adds, and shape the model around your own tasks.


17Ge retweeted
Apollo World, our world model for physical AI, was unveiled yesterday at Baidu AI Day in Shenzhen!
It turns complex interactions on the road and rare driving scenarios into repeatable, controllable simulations for training and testing autonomous driving systems.
- AI traffic agents that make their own decisions and react as autonomous vehicles slow down, change lanes, or yield
- Simulated camera, LiDAR, and other sensor data generated in real time, helping autonomous vehicles sense and respond to a virtual world that changes with their actions
- Complete rides between any two locations in a virtual city, from accepting a ride request to dropping off passengers
- A technology stack suited to robotics and other physical AI applications
Apollo World is already part of Apollo Go's testing and validation. What we learn from those virtual trips helps us improve how the vehicles drive on real roads.


We frequently run Agents from different frameworks in our services, e.g. Claude Code and Antigravity side by side. This heterogeneous architecture complicates trace analysis. Claude Code already supports OpenTelemetry. Will @antigravity support OpenTelemetry in the future?
1
63


17Ge retweeted
Unlimited OCR 2 is here, and it's open source. 📖 ✨
Longer documents can mean a lot more attention computation. Our new SR-SWA mechanism keeps that in check by condensing text-visual attention interactions into a fixed-size set of working references.
Here's what it delivers:
- Document parsing at virtually any length, within a finite context window
- Nearly constant per-step decoding latency and memory footprint as documents grow longer
- State-of-the-art performance on MPDocBench and MarathonDocBench, covering documents from dozens to hundreds of pages
Check out the model here ↓


17Ge retweeted

6.1 Terra is here! It is good at a lot of things, but we are especially excited for this new era of computer use.


最近这两天我一直在尝试使用 Gemini 4 Argon 完成编码任务,但是整体感知 Gemini 4 Argon 的编码效果真的非常差,非常 简单的任务也无法正常完成。
但我发现了 pele 这款 mermaid 图标渲染库后,我用下面的提示词让 Gemini 4 Argon 来优化我的博客系统:
```prompt
pele(pele.run/)是一款轻量级的开源 mermaid 图标渲染库,我的博客现在用到的渲染是mermaid方式,请按照mermaid的配置方式,为博客增加pele的渲染方式,注意不要去掉对mermaid的支持。
```
Gemini 4 Argon 运行了 20 分钟还在浏览代码,还没启动优化。我切换成 Opus 5.5 之后,2 分钟 就完成了如下的代码提交。
github.com/wangwei1237/wangw…

40
