
AI/LLM researcher. Exploring language, knowledge, and intelligent systems.
Shanghai
Joined April 2013
- Tweets110
- Following158
- Followers562
- Likes524


Xipeng Qiu retweeted

Try Nex-N2.6 for one week FREE
via MOSS API ↓ @MOSS_Global

Nex-N2.6 is open sourced - multimodal agentic LLM
With stronger computer use and more token-efficient in long-running tasks
Create a 3D keyboard model from one photo in Blender.
It builds the model, matches its materials, sets the lighting, and renders an animated product showcase.
A multimodal agentic model that can directly see and operate real computer interfaces.
Try it now.
⭐GitHub: github.com/sii-nex/Nex-N2.6
🤗HuggingFace: huggingface.co/nex-agi/Nex-N…
🔗OpenRouter API: openrouter.ai/nex-agi/nex-n2…
🔗MOSS API: platform.moss.cn/docs/models…
Xipeng Qiu retweeted

Watch Nex-N2.6 turn a single keyboard photo into an animated 3D showcase in Blender. ⌨️
Try it for free via the MOSS API 👇 nitter.cf/NexEcosystem/status/21…
Xipeng Qiu retweeted
Nex-N2.6 is open sourced - multimodal agentic LLM
With stronger computer use and more token-efficient in long-running tasks
Create a 3D keyboard model from one photo in Blender.
It builds the model, matches its materials, sets the lighting, and renders an animated product showcase.
A multimodal agentic model that can directly see and operate real computer interfaces.
Try it now.
⭐GitHub: github.com/sii-nex/Nex-N2.6
🤗HuggingFace: huggingface.co/nex-agi/Nex-N…
🔗OpenRouter API: openrouter.ai/nex-agi/nex-n2…
🔗MOSS API: platform.moss.cn/docs/models…
Xipeng Qiu retweeted
Meet the team behind MOSS-Image.
The @ComfyUI -Org/MOSS-Image repo on Hugging Face is over 6.3M downloads in the past month.
See what the model they trained can do. 👇 nitter.cf/ting_/status/212081531…
Xipeng Qiu retweeted

Switch from Claude Code to Codex, Cursor or your own harness, and Nex-N2.6 still calls only the tools that are actually there. The open-weight 321B multimodal agentic model from Nex-AGI is built on GLM-5.3-Flash for computer use, coding and long-horizon tasks. 📜 Apache 2.0 🤖 modelscope.ai/models/nex-agi…
🛠️ Harness-agnostic tool use: 100% valid tool selection across 956 real-world contexts, matching GPT-6-Sol and up from 80.56% for Nex-N2.5-Pro.
🔁 Far less looping: reasoning repetition drops 90%, from 16.0% to 1.6%, on 698 real failure cases replayed from the exact point where the previous model stalled. Fewer wasted tokens on long runs.
🖥️ Stronger computer use: 83.0 on OSWorld, 5.0 points above its GLM-5.3-Flash base, while holding 84.1 on Terminal-Bench 2.1.
⚡ Ready to run: 256K context via API, or self-host the FP8 weights on SGLang behind an OpenAI-compatible endpoint with low, high or max reasoning effort.


Xipeng Qiu retweeted
Meet Nex-N2.6, our latest multimodal agentic model supporting text, image, and video inputs.
Open-sourced by Shanghai Innovation Institute, the model has performed strong benchmark results:
⚡Compared with Nex-N2.5-Pro, the reasoning repetition rate falls from 16.0% to 1.6%, while the overall non-repetition rate rises from 91.0% to 97.8%
⚡Achieved 100% valid tool selection rate across 956 tested contexts, on par with GPT-6-Sol
⚡Scored 83.0 on OSWorld and 84.1 on Terminal-Bench 2.1, ahead of DeepSeek-V4.1-Flash at 71.7 and 82.7
Nex-N2.6 is built with a stronger foundation to navigate interfaces, use tools, and complete lengthy tasks without losing its place.
Try now 👇
⭐GitHub: github.com/sii-nex/Nex-N2.6
🤗HuggingFace: huggingface.co/nex-agi/Nex-N…
🔗OpenRouter API: openrouter.ai/nex-agi/nex-n2…
🔗MOSS API: platform.moss.cn/docs/models…

Xipeng Qiu retweeted
Nex-N2.6 is now available for free via the MOSS API. 🚀
Nex’s eval results
⚡ In replay tests, reasoning repetition was 1.6% vs. 16.0% for Nex-N2.5-Pro.
⚡ 100% valid tool selection across 956 tested contexts
⚡ 83.0 on OSWorld and 84.1 on Terminal-Bench 2.1
Try it now 👇
Meet Nex-N2.6, our latest multimodal agentic model supporting text, image, and video inputs.
Open-sourced by Shanghai Innovation Institute, the model has performed strong benchmark results:
⚡Compared with Nex-N2.5-Pro, the reasoning repetition rate falls from 16.0% to 1.6%, while the overall non-repetition rate rises from 91.0% to 97.8%
⚡Achieved 100% valid tool selection rate across 956 tested contexts, on par with GPT-6-Sol
⚡Scored 83.0 on OSWorld and 84.1 on Terminal-Bench 2.1, ahead of DeepSeek-V4.1-Flash at 71.7 and 82.7
Nex-N2.6 is built with a stronger foundation to navigate interfaces, use tools, and complete lengthy tasks without losing its place.
Try now 👇
⭐GitHub: github.com/sii-nex/Nex-N2.6
🤗HuggingFace: huggingface.co/nex-agi/Nex-N…
🔗OpenRouter API: openrouter.ai/nex-agi/nex-n2…
🔗MOSS API: platform.moss.cn/docs/models…
Xipeng Qiu retweeted

Models trained on machine-generated transcripts beat the labeling models that produced them, in all five Arabic dialects. @xpqiu and coauthors show this with GigaSpeech 3, 39,000 hours of weakly labeled web audio.
pith.science/paper/2611.0247…

Just 42 hours left to try the MOSS-Image API for free.

🎉 5.6M+ downloads in the past month for Comfy-Org/MOSS-Image on @huggingface @ComfyUI
Just 42 hours left to try the MOSS-Image API for free.
The trial ends on Nov 11 at noon (UTC+8). Bring your own prompts and give it a try 👇

4
158
MOSS-Live is here. Our full-duplex, real-time voice AI can listen, speak, and get things done at the same time. 🎙️
MOSS-Live is here. Our full-duplex, real-time voice AI can listen, speak, and get things done at the same time. 🎙️
While tasks run in the background, it can keep listening, seeing what you see, and talking with you.
• Natural conversation: It distinguishes real interruptions from “mm-hmm,” waits when you pause to think, stays out of side conversations, and gives brief acknowledgments while listening.
• Speech awareness & live translation: It tracks where it is in its spoken response, picks up after interruptions, and translates while you speak.
• Proactive help: Set rules for when it should correct mistakes, keep count, or remind you.
• Tools & background tasks: Check weather or stock prices, or let longer tasks run in the background without putting the conversation on hold.
• Multimodal perception: Use video calls or screen sharing to give it visual context. It can also recognize environmental sounds and describe voice qualities.
Try MOSS-Live ➡️ shorturl.at/96uVt
MOSS-Image natively understands Chinese mythology, cinematic wuxia, and atmospheric scale without that generic western-AI look.

True EASTERN AESTHETICS in AI art is finally here! 🎨🐉
MOSS-Image natively understands Chinese mythology, cinematic wuxia, and atmospheric scale without that generic western-AI look:
✅ Direct film/game referencing (Black Myth: Wukong, Creation of the Gods, Crouching Tiger)
✅ Massive scale: Mountain temples resting on giant stone palms
✅ SLG Guidance Hack (single_layers: 22) for crisp, collapse-free details
✅ Tested: Dunhuang posters, wuxia sword duels, and Wong Kar-wai moods
Full guide & RunningHub workflows below: 👇
🔗youtu.be/3CGoD3D1AH8
#MOSSImage #ComfyUI #AIArt #EasternAesthetics #BlackMythWukong #GenerativeAI
4
193
Xipeng Qiu retweeted
The biggest lineup of open models yet for a @LocalLLaMAsub AMA. 👀
Speech, sound, music, images, video—we're bringing the whole MOSS model family!!!
🗓 Oct 30 · 8–11 AM PT
Join r/LocalLLaMA and bring your questions ➡️ reddit.com/r/LocalLLaMA/s/Ut…

MOSS-Image high resolution (up to 10MP)

Introducing MOSS Image MAX ULTRA HD, the latest post trained image model by the ComfyUI research team.
MOSS Image MAX MEGA ULTRA HD scores an impressive 1238 on our first party 4k anime characters with massive animal ears benchmark evaluations.
We believe so much in open models that we decided to open it before it's ready.
Kidding aside this is a test lora for MOSS Image that you can use to generate better high resolution (up to 10MP) images with MOSS Image with a bias towards anime but there was a lot of photographs in the training set.
Link to the lora here: huggingface.co/comfyanonymou…
Give it a try and let me know if we should do more of these.

7
204
Xipeng Qiu retweeted
Try MOSS-Image in ComfyUI with our free API. 🎨
⚡ Get your API key: platform.mosi.cn/?utm_source…

Xipeng Qiu retweeted
MOSS-Image API is live FOR FREE
⚡ API: platform.mosi.cn/?utm_source…
Join our Discord to share your creations, exchange ideas, and technical support: discord.com/invite/Wjku5AYyx…

Xipeng Qiu retweeted

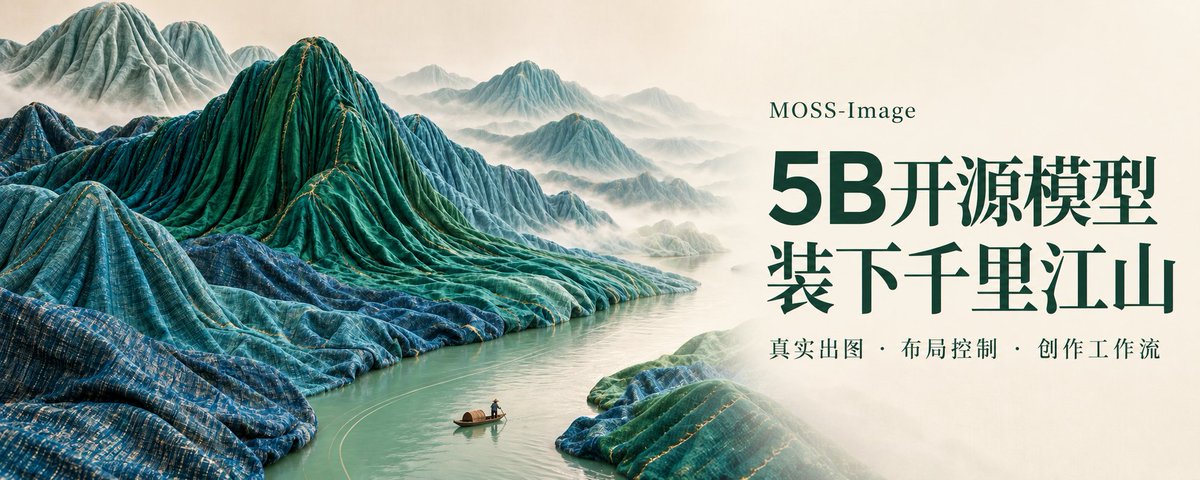
我把一城烟火、千里江山,交给了一个5B开源模型。
从宋城长卷、青绿群舞,到丝绸、青瓷和墨金山水:MOSS-Image 的真实成图、50 秒演示、提示词和 Layout 工作流都在这里。
点开长文,也去试一张。
🤝 Paid partnership
Xipeng Qiu retweeted
MOSS-Image API is coming soon in 24hrs
Join MOSS discord for FREE early access 👉 discord.gg/Wjku5AYyxx
Xipeng Qiu retweeted

Hi everyone! I'm a core dev of MOSS-Image, a 5B-parameter DiT image generation model.
Today: MOSS-Image-Base + MOSS-Image-SFT, model weights, inference code, and technical report. Our goal: a capable, controllable open-source image generation foundation for the community.
Xipeng Qiu retweeted

KohakuMossTrainer is released:
github.com/KohakuBlueleaf/Ko…
**Features**
- LyCORIS all algorithms
- SM70 ~ SM120
- Intel Arc GPU
- Windows and LInux
- multi GPU training
- Model offload
***Try to test it now!***

Xipeng Qiu retweeted
👀 want EARLY ACCESS to our next models?
join the MOSS Discord for upcoming early access opportunities, help with MOSS-Image, and ideas from fellow creators.
love seeing the community's LoRAs already 🫶 come show us yours
join MOSS discord 👉 discord.gg/z7TD5ehYts
