

We build open-source tools for reading and coding, train small models, and publish AI benchmarks.
Zürich, Switzerland
Joined September 2026
- Tweets133
- Following278
- Followers31
- Likes208




At Liquid's list prices, we estimate $6.66 per million English reading questions for d1.2 and $13.98 for d1.2-ultra, the same as their predecessors. No current model scores higher for less.
The extra $7.32 buys 69.0 vs 65.3 on our index. d1.2 gains 3.9 on Logic over d1.1.

1
2
32
On single English reading calls, our median time through Liquid's API went from 220 to 221 ms for the ultra, and from 173 to 219 ms for d1.2, network included. On our RTX PRO 6000, GLiDE v1.2 takes 104 ms and Decider Flash v1.3 33 ms.
zekiworks.github.io/analysis…

2
34
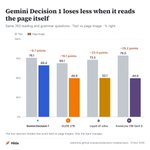
On the same 763 questions, switching from text to page images costs Gemini Decision 1 9.7 accuracy points, versus 24 on average for GLiDE, Liquid and KnowLine.
With text and image together, Gemini leads the decision models tested at 78.4% (KnowLine: 76.0%).

1
3
38
Gemini Decision 1 loses 4.5 accuracy points without Surya OCR 2: 34 fewer correct answers, versus 19 points on average for the other three models shown.
With OCR, KnowLine leads these four (75.5%); on page images alone, Gemini leads (66.4%).
zekiworks.github.io/analysis…

3
25
On the same 763 questions, switching from text to page images costs Gemini Decision 1 9.7 accuracy points, versus 24 on average for GLiDE, Liquid and KnowLine.
With text and image together, Gemini leads the decision models tested at 78.4% (KnowLine: 76.0%).

1
11
Gemini Decision 1 loses 4.5 accuracy points without Surya OCR 2: 34 fewer correct answers, versus 19 points on average for the other three models shown.
With OCR, KnowLine leads these four (75.5%); on page images alone, Gemini leads (66.4%).
zekiworks.github.io/analysis…

8

REAX 1.3 isn’t in Artificial Analysis’s (AA) Decision Index, so we applied AA’s Decision Score, which punishes confident errors, to our 3,288 questions.
REAX scores 79.3, KnowLine 31B Gen1.5 78.9. Mammoth-1 (AA #3) is third, ahead of AA’s #1 and #2.
zekiworks.github.io/analysis…


All 16 decision models had a median under half a second. REAX 1.3: 0.20 s on our GPU. d1-ultra: 0.18 s over its API. vLLM-SR d3: 0.06 s on our GPU.
AA timed Drex Max v1.1 at 0.28 s per task; we measured 0.33 s per question.
All results: zekiworks.github.io/analysis…

Perplexity reported 86% accuracy and a 370 ms median response time on Parallel’s benchmark. Our three runs agree on accuracy. Our median was about 110 ms slower, but we measure from our own machine, so it includes network time.
All 36 decision setups without search averaged 47.5%: close to random guessing, and far below always picking the first choice.
zekiworks.github.io/analysis…

1
1
7
In Turkish, search sometimes found text from the question itself. Of the 147 questions Perplexity’s Decider got right only with search, 41 shared at least 8 consecutive words with a search result. In English, 0 of 13 did.
Decider got 94 right only with search off, leaving a net gain of 53 out of 2,198. A second Turkish run gave a net gain of 52.
zekiworks.github.io/analysis…

6