

Allow for the current to flow, conduct and bring forth thy ode of care to those bonded by trust. 🌌 CREATOR 👨💻 Validator anodeofzen 📧 [email protected]
EOF
Joined July 2022
- Tweets130
- Following95
- Followers89
- Likes427


ZENODE retweeted

Human chromosome 21 is now on GenesisL1.
Yesterday, 16 November, The Bioinformatics Company completed a pilot deployment on GenesisL1: human chromosome 21 from the GRCh38 reference genome, together with chromosome 21 of 12 public genomes from the 1000 Genomes Project, written on chain in gl1-seq format.
What is on chain:
• Reference: the complete 46.7 Mb sequence of chromosome 21, with its GENCODE genes, transcripts and exons, and UniProt proteins
• Genomes: 12 open-access genomes in four parent–child trios, 24 haplotypes, each stored as a gl1-seq delta that records exactly what differs from the reference
• Footprint: 71,219 content-addressed objects, 26.8 MB of contract state, 346 transactions
Verifiable by design. Every object is stored under an identifier computed from its own content, so any copy can be checked byte for byte, wherever it was read from. Each of the 24 haplotypes can be rebuilt from the reference and its delta and checked against the identifier recorded for it on chain.
gl1-seq is version control for genomes: git for biological sequences. A genome becomes a verifiable version of a reference, with every change recorded exactly and checkable by anyone.
Open data only. Everything written is open-access public data. Personal genomic data is never written to the chain.
GenomeRegistry: 0x7380e7787566eb1a2f069aeefb9664abbebae020
GenomeStore: 0x955ee39cca0e281cb74b672ade7dbc3ced1e5374
Chromosome 21 was the pilot.
Next, expected before the end of November: the gl1-seq preprint and the complete human reference genome on GenesisL1.
gl1-seq.com

ZENODE retweeted

"Life is a form of protein molecules organisation".
Ive heard this first at the very first biochemistry facultative lesson with ms Tatiana Solomonovna Freindlin when at 10th grade and this phrase changed everything.
Years later after finishing medical university, having knowledge in molecular medicine, bioinformatics, data science and computer programming I understand this phrase much deeper than before and can even expand the meaning from various point of view.
Proteins are binaries, nucleic acids are source codes. Proteins are building blocks, nano machineries, shields and armors, and each and every action is programmed. Together, via their interactions in closed and open systems - internal and external - they drive life. Everything you see living is built by proteins. Everything you see living is programmed by nucleic acids.
Bioinformatics treat it exactly that way - as programs and their codes. And programs and codes are data.
Satoshi Nakamoto and his peers delivered the most successful decentralized database - the blockchain. This database is used to store financial txs data. But data about life is far more valuable than data about financial transactions, and there is no point to not use the best distributed permissionless database technology to store and protect and work with data about life - about programs and their codes that drive life.
This is what GenesisL1 is about: the term DESCI or decentralized science have never had more concrete meaning and this meaning is a Layer 1 that actually runs DESCI natively using that amazing tech pioneered by Nakamoto et el.
And it is not a promise at all, it is working already. Open gl1x.com/molnft - more than a million MolNFTs on GenesisL1: PDB structures, AlphaFold models and HLA alleles. 265,786 PDB structures are stored fully on chain - not a link, the structure itself. Every structure is NFT with its own owner and on-chain history, and you can search them, BLAST them and align them right in the explorer. Sperm whale myoglobin - the first protein whose structure was ever solved, back in 1958 - lives on chain right now: gl1x.com/molnft/101M. Open science data stays open and verifiable for everyone, private data stays encrypted and owned by those who created it.
Remember - nucleic acids are source codes. And every source code that matters lives in git: commits, diffs, branches, full history of every change. Biological source codes never had their own git. Until now.
On November 16 The Bioinformatics Company deployed GL1-seq (gl1-seq.com) pilot on GenesisL1: chromosome 21 of the human reference genome GRCh38 plus chromosome 21 of 12 public genomes. In coming weeks GL1-seq comes to GenesisL1 in full - novel git for biological sequences and genomes. Full human reference genome stored on chain - not a link, the genome itself. Every other genome is just a diff against it, every change is a commit with its own history, and everything reconstructs back lossless, base by base, in format both scientists and AI agents can read and work with. Built on it - genome, gene and proteome atlas: all human genes and the whole human proteome on chain. Personal genomes never go on chain - only commitments that prove nobody changed them.
In upcoming months and years, on top of AI progress there will be thousands of scientific breakthroughs made. Not talks about breakthroughs, but actual breakthroughs everyone will talk about. And every one of them will need data - open, verifiable, with provable origin. AI can find patterns, but AI can not prove where data came from and that nobody changed it. Blockchain can.
GenesisL1 will transform biotech towards blockchain the same way Bitcoin transformed finance. There is no technical barrier anymore, and there is no more important thing for life than life itself. All resources, all money of the world, all energy and all debates, everything - eventually end up at one single objective - to understand life and to use that understanding to improve and prolong it.
Please, stay tuned.

ZENODE retweeted

29,247 Osmosis accounts were swept into one address in 13 hours, including 14,657 L1 drained from 60 of them.
The same keys can sign for 8,480 GenesisL1 accounts holding 118,811.91 L1.
Attacker or whitehat recovery? Unconfirmed.
Full findings 👇
unmaskcrypto.io/news/keplr-s…
ZENODE retweeted
Imagine seeing who is behind every trade.
6,713 owners hold 1 L1 or more, each counted once across all their wallets.
589,744 untouched 2022 airdrop accounts are counted apart.
Every link with its evidence.
Don't trust. Unmask.
unmaskcrypto.io

ZENODE retweeted

Love seeing Coinbase CEO Brian pushing for open, reproducible science.
This is exactly where GenesisL1 gets interesting.
#GL1X already provides on-chain molecular records, bioinformatics tools and AI agent access.
The next ambition? Git for genomes.
We’re still early. $L1

Publicly funded science should work more like open source software.
Today a result is a PDF. The data often isn't shared, the code isn't public, and few studies ever get replicated.
Imagine every experiment as a repo. Data, code, and protocol, all versioned. Anyone could fork it, rerun it, and send a fix. Funders could reward replications as much as new papers.
AI makes this urgent. Agents are now making more discoveries than ever. The bottleneck becomes replication/validation. Then commercialization, which still requires moving atoms in the real world and meetings with regulators.
ZENODE retweeted

One trader bought 100k base:0xe6522a891702cd2e8cc2a5182638c9da1dd44b22 2 months ago at 10 12, and sold today at 18 16... Congrats on the 60% gains.
VC wallets are saying thanks and actively slurping.
A new wallet looks to be buying like the 2 VCs wallet.
Just new. But the same ways.
They can't help buying the dips.
VC level of entry on genesisl1:native
Chain and project is pure insanity. Nothing goes 100x in 5 minutes in this world.
You gotta buy when the market is like now. Things that look to be huge, just before they are huge.
Like the Early $Tao whales are saying. This is like Tao when they were the first on it.
Gl.
RT @genesis_L1: THE BIOTECH GOLD RUSH IS COMING. GENESISL1 BUILDS THE SHOVELS. ⛏️
In every gold rush, the biggest fortunes were made not b…
ZENODE retweeted

I'm seriously thinking about launching a CRYPTO AI MODEL COMPETITION on Crypto GL1F, with genesisl1:native prizes for the winners.
The crazy part?
✅ANYONE can participate.
☑️ No coding skills. No expensive GPUs. No AI expertise required.
Crypto GL1F just broke the coding barrier for building AI models, much like Pumpfun did for launching tokens. And burns 100% of the genesisl1:native collected through its platform fees.
With just a few clicks, you can build your own crypto AI model, publish it on Crypto GL1F and potentially monetize it on-chain.
Now imagine competing against hundreds (or potentially THOUSANDS ) of other AI models for a nice bag of genesisl1:native.
Challenge example:
Can your AI model predict whether BTC will rise 1% within the next 12 hours WITHOUT dropping more than 1% first?
How would the competition work?
Everyone will have 7 days to create and publish their AI models on Crypto GL1F.
Once that window closes, the 14-day competition begins.
During those 14 days, the market moves, but no new models can enter.
After the 14 days are over, we'll backtest all submitted models against that exact period of market data to see which performed best.
Best-performing models win genesisl1:native.
Simple. Transparent. Verifiable.
How many people can participate?
UNLIMITED.
And how many AI models can each participant submit?
UNLIMITED.
Imagine how many genesisl1:native tokens this competition could end up burning.
Btw, don't even think I'll be touching my own genesisl1:native bag. I'll be buying the tokens for the prize pool directly from the open market. Everything will be fully transparent and verifiable on-chain.
What genesisl1:native prize pool would get you to join? 👀
ZENODE retweeted
Dear BioAI, MedAI, SynBio and biohacking community,
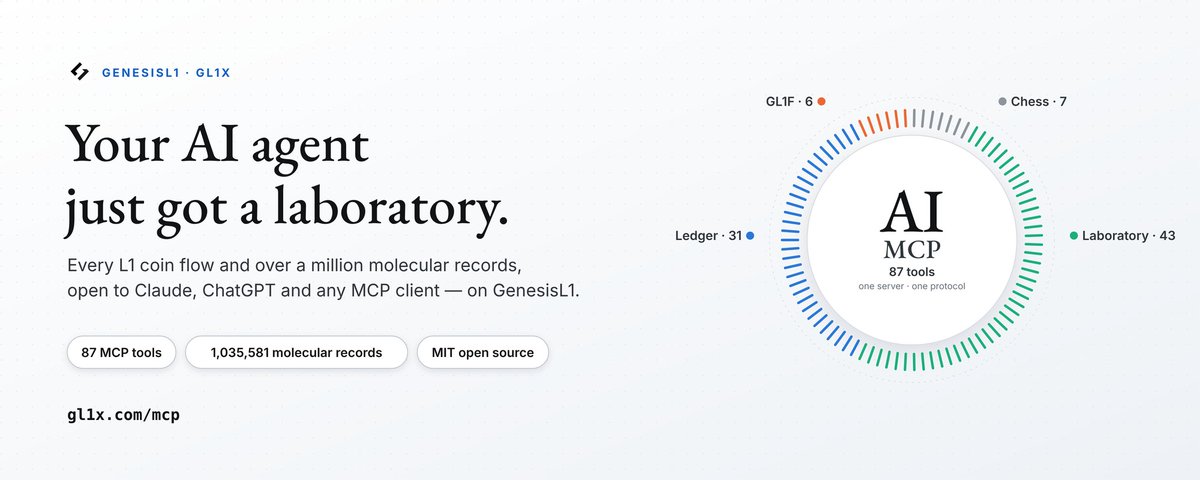
We are very happy to present the very first on-chain bioinformatics laboratory, as a part of the broad GenesisL1 decentralized science architecture:
gl1x.com/bio — Bioinformatics Onchain
Free. No account. Open to humans, programs and AI agents.
What it is
GenesisL1 carries hundreds of thousands of protein and nucleic acid structures published as MolNFT records, stored in contract state or anchored on chain with CID-verified IPFS content. GL1X treats that archive as a scientific database and runs the standard methods of sequence and structure bioinformatics over it, in its own code, with no external services, and each method validated against its reference program.
This is not a wrapper around someone else's server. It is a laboratory that lives on the chain.
What you can do today
🔎 Search & homology — molecular search by PDB ID, UniProt accession, NFT id, title, sequence or motif; full BLAST (blastp/n/x, tblastn, tblastx) over every sequence, identical to NCBI BLAST+ on the test set; PROSITE-style motif scans across sequences and 3D structures; profile HMM search reproducing the hmmsearch pipeline.
🧬 Structure — TM-align superposition of any chain against any other (or your own file); structure search over every indexed chain in seconds via the GSA structural alphabet; pre-computed experiment-vs-prediction comparisons for every UniProt accession present as both.
🔬 Full-atom analysis in the research workbench — DSSP secondary structure and H-bonds, accessibility, half-sphere exposure, contact maps, base pairs with pseudoknots, chain interfaces with buried surface, salt bridges; SS-pattern search (β-hairpins, helix-turn-helix); 3D templates for catalytic triads and metal sites.
💊 Pockets & druggability — cavities with volume, buriedness, hydropathy, charge and a druggability score, searchable across every structure; a ligand index of every cofactor, drug, ion and sugar with its binding-site residues.
🧪 pH environments — structure-based pKa for every ionizable group; charge, pI and stability of a protein in the stomach, intestine, blood, cytosol, endosome or lysosome, with membrane proteins getting a pH on each side.
⚗️ Proteomics — digestion by 24 enzymes, proteotypic peptides across the archive, masses, fragments, isotope patterns, MGF spectrum identification with target-decoy FDR, crosslink checks, HDX/LiP painting, a virtual 2D gel.
🌳 Families, evolution & variants — multiple alignment at MUSCLE-level accuracy, Jensen-Shannon conservation on the structure, NJ trees, mean-field DCA coevolution vs contacts, CD-HIT clustering, disorder/coiled-coil/TM annotation, substitution scans and ΔΔG from GL1F models.
📊 Datasets & on-chain ML — turn any search into a dataset (JSON/CSV/TSV) with documented features, or straight into GL1F model inputs; train off chain, publish the model as an NFT, run it on GenesisL1 on any record.
📚 Literature — PubMed search with up to 2,000 records clustered into a topic map in your browser (Broccoli), every structure linked to its literature.
✅ Proofs — every sequence in every result can be re-derived from the chain at a pinned block and from IPFS, with the calls to replay on your own node. Every hit names the record and the SHA-256 of what it describes. Deterministic answers, reference parity, held-out evaluation.
🤖 Agent-native — every tool above is an MCP tool and an API endpoint. An agent can identify a molecule, BLAST it, find its structural neighbours, analyse its pockets, digest it, align its family, scan its variants, read its literature, build a dataset, run a model and prove the sequences, end to end.
Where this is going
This is the opening move. The horizon is expanding constantly: the full human reference genome and pilot genomes are coming into chain state through GL1-seq, with 1000+ public genomes to follow, alongside Swiss-Prot, RefSeq proteins, UniRef50, paired antibody repertoires and IPD-IMGT/HLA. Peptide design (PEPTL), confidential IP (CIPNFT), scientific DAOs (COLLAB) and DeSci finance (DESCIFI) are being built around the same core.
Our aim is simple and ambitious: hundreds of thousands of researchers working on decentralized infrastructure, with tools and services for open science expanding at a pace the field has not seen before.
This is an invitation
Research on chain. Build on chain. Point your agents at the MCP server, call the API, fork the explorer, publish a model, mint your structures. Everything you compute here is provable, reproducible and belongs to no single server.
→ gl1x.com/bio · Docs: gl1x.com/docs/bioinformatics · API: gl1x.com/docs/api · MCP: gl1x.com/docs/mcp
Welcome to the laboratory.
GenesisL1

ZENODE retweeted
FirstBlock Validator delivered something nice for the GenesisL1 community. genesisl1:native
Make sure to follow and support them along the way. 🤝

Everyone says whales are accumulating $L1.
Unmask checked the chain:
Whales net bought 58.9% of what they traded in 7 days.
974,893 wL1 bought vs 576,996 sold.
74% of the L1 bought in the last 24h is still held.
Don't trust, verify 🔍 unmaskcrypto.io
#GenesisL1

ZENODE retweeted

After so many scams and so much greed in the space, #GenesisL1 has restored my faith that a project can stand for humanity and the greater good!
We are currently at the ground floor of perhaps the greatest innovation in #DeSciFi
Join us!
t.me/Genesis_L1


GenesisL1 will soon present a state-of-the-art Scientific DAO engine.
Every GenesisL1 protocol and dataset wired into DAO pipelines — with a new Decentralized Science Finance #DeSciFi layer at its core.
Finance the frontier of Science
#DeSci → DeSciFi.org

ZENODE retweeted
GenesisL1 will soon present a state-of-the-art Scientific DAO engine.
Every GenesisL1 protocol and dataset wired into DAO pipelines — with a new Decentralized Science Finance #DeSciFi layer at its core.
Finance the frontier of Science
#DeSci → DeSciFi.org
ZENODE retweeted
Two competing governance proposals for CIPNFT and GL1F security audit by two different companies were submitted onchain.
Native $L1 staked is your vote to shape future.
Please review, research, vote.
genesisl1.com/gov.html
genesisl1.com/gov.html?propo…
genesisl1.com/gov.html?propo…

ZENODE retweeted

I'm going to validate some shit again and I'll tweet about it now. The first network will be @genesis_L1 because its founder just wouldn't give up encouraging me to become a validator again and so I'm going to do it tonight. Here's a photo of the server.
ZENODE retweeted
We are upgrading the genesisl1:native onchain #Biotech insilico laboratory a few versions every week with amazing new features and improvements gl1x.com/molnft. Today, GenesisL1 stores >1M molecular records. A year from now: >100M sequences & the entire Human Genome onchain. #DeSci
ZENODE retweeted
A search gives you a list. A field has a shape.
Broccoli, GenesisL1's open-source clustering engine, turns any search into a zoomable map of named topics, in your browser.
11 sources. Up to 2,000 records. No keys. Built for researchers and AI agents.
nitter.cf/genesis_L1/status/2112…

ZENODE retweeted
If you are truly interested in Decentralized Science consider checking the genesisl1.com and the whitepaper genesisl1.com/whitepaper.pdf
My focus is immunology btw inlcl SARS-CoV-2 and I am a part of HLA Covid-19 consortium hlacovid19.org
dm @ email open

ZENODE retweeted
How to launch your first crypto AI model on GenesisL1.
NO CODING REQUIRED! 🤯
Here’s a quick guide to GL1F Crypto 👇
1️⃣ CHOOSE YOUR DATA
Open crypto.gl1f.com → Create Crypto AI model.
Select:
• Exchange: where the data comes from.
• Market: the coin you want to study.
• Candle: data resolution - 15m means one candle every 15 minutes.
• Start / End: the historical period your model will study.
For this example: Binance → ETH → 15m candles → six months of completed history.
2️⃣ DEFINE YOUR QUESTION
Use these example settings:
• Direction: Up
• EMA baseline: 5
• Target: 1%
• Stop: 0.5%
• Horizon: 5 hours
EMA is a moving average that gives more weight to recent prices. “5” means five candles.
Your question becomes:
“Will ETH reach 1% above EMA5 before reaching 0.5% below it, within the next five hours?”
Both levels are measured from the EMA baseline.
The model learns from historical yes/no outcomes.
3️⃣ CHOOSE YOUR SIGNALS
Signals are the information the model can see: price changes, volatility, volume, momentum, BTC movements and more.
Start with the “Optimal” preset.
More signals don’t automatically mean a better model.
Click “Build dataset” → “Continue to training”.
4️⃣ TRAIN YOUR MODEL
For your first experiment, keep the default model settings and use “Walk-forward” validation.
That means learning from earlier data and testing on what happened next.
The main settings:
• Trees: how many learning steps the model can take.
• Depth: how complex each tree can become.
• Learning rate: how much each tree contributes.
• Min leaf: minimum examples supporting a final tree decision.
• Final test %: the latest data reserved for evaluation.
Keep early stopping enabled: it stops adding trees when validation stops improving.
Train, inspect the results, then save your .gl1f file.
5️⃣ BACKTEST WITH COSTS
Use the final test period and include fees and slippage.
“Entry threshold” is the minimum probability required for a simulated signal.
0.60 = at least 60%.
Start with 1× leverage for this exercise.
Check drawdown, trade count and the full equity curve - not just the final return.
Avoid repeatedly changing settings to make the same final test look better.
6️⃣ RUN INFERENCE
Inference means asking your trained model to evaluate a new completed candle.
A result of 0.72 means:
“The model estimates a 72% probability of the specific event you defined.”
It is an estimate, not a guarantee.
7️⃣ OPTIONAL: PUBLISH
When deployment is available, you can mint your model as an NFT on GenesisL1, choose its license and configure free access, tips or paid usage.
Pick a market. Define a question. Build. Test. Learn.
No code required. Fees are burnable.
Experimental research software. Backtests are simulations; the platform explicitly excludes live trading and automated execution. 🤝
genesisl1:native

