

Cornell PhD '25; CS BA '17; Agent Architect, Gemini, RSI Ex?-Halo Pro; Eternal Halo Combine Kid
Ithaca, NY
Joined January 2011
- Tweets269
- Following493
- Followers1.1K
- Likes13.2K

Jordan Dotzel retweeted

Impressive

I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!

Jordan Dotzel retweeted

ALERT🚨: NVIDIA has been working overtime, nights, and weekends after being shocked 🤯 by last week’s TPUv7 FP8 submission showing better performance per dollar.
Unfortunately for NVIDIA, its first GB300 FP4 counter-submission is still 1.64x worse in performance per dollar than TPUv7 for external customers across most of the end-to-end performance curve.
The x-axis of the graph below uses end-to-end latency, so a higher curve is better. The TPUv7 curve has higher perf per $ across most of the E2EL Pareto frontier.
This initial submission looks like NVIDIA’s first attempt to close the gap, but the gap is still massive. We expect more counter-submissions from NVIDIA as they continue trying to narrow the difference.

Jordan Dotzel retweeted
BREAKING NEWS🚨: Google has submitted its FIRST TPUv7 FP8 vLLM results to our Agentic Inference Benchmark and has demonstrated 1.67x better perf per dollar than even GB300 NVL72 FP4. 🚀
It is amazing to see Google go full steam ahead with externalizing the power of TPUs outside of Google.👇️ (1/4)🧵

Jordan Dotzel retweeted

Q1 earnings are in: 2026 is off to a terrific start.
Our AI investments and full stack approach are lighting up every part of the business: Search queries are at an all-time high with AI continuing to drive usage. Google Cloud revenue grew 63%, Gemini models have incredible momentum, and it was our strongest quarter ever for consumer AI subs, driven by @GeminiApp.
Thanks to our partners + employees around the world. Much more to share on our earnings call in 20 minutes… and at Google I/O in 20 days!

Jordan Dotzel retweeted

What if you could not only watch a generated video, but explore it too? 🌐
Genie 3 is our groundbreaking world model that creates interactive, playable environments from a single text prompt.
From photorealistic landscapes to fantasy realms, the possibilities are endless. 🧵
Jordan Dotzel retweeted

Not consulting AI models in 2025 is medical malpractice. No other way to put it. I follow the field closely to know how to use it, and that saved my life. Not every patient does. People are dying today for misdiagnoses that o3 would get right 10 out of 10 times

this story is going wildy viral on reddit.
ChatGPT flagged a hidden gene defect that doctors missed for a decade.
ChatGPT ingested the patient’s MRI, CT, broad lab panels and years of unexplained symptoms. It noticed that normal serum B12 clashed with nerve pain and fatigue, hinting at a methylation block.
Within months tingling eased and brain fog cleared. The primary physician reviewed the genetics report and agreed the variant unified the entire case.
IMO, time has already come, taking a 2nd opinion from the best healthcare-AI model should be made part of medical code of practice.
------
reddit. com/r/ChatGPT/comments/1lrmom4/chatgpt_solved_a_10_year_problem_no_doctors_could/

Jordan Dotzel retweeted
Video, meet audio. 🎥🤝🔊
With Veo 3, our new state-of-the-art generative video model, you can add soundtracks to clips you make.
Create talking characters, include sound effects, and more while developing videos in a range of cinematic styles. 🧵
Jordan Dotzel retweeted

What if a small model could solve most of a task and call on a bigger, more powerful one only when it hits a really hard part?
It's exactly an idea behind SplitReason, a new method from @Cornell researchers.
To make SlipReason efficient on hardware, they also introduced a new paradigm, Reinforcement Learning for optimizing Efficiency (RL4E):
A model uses GRPO to learn how often or how carefully it should call the larger model for "help".
The results of SplitReason are promising:
- The small model’s accuracy increases by 28.3% while offloading only about 5% of the work to the big model.
- The final system is 4-6x faster than using a big model the whole time.
Details 🧵

Jordan Dotzel retweeted

Why Many Token When Few Do Trick?
Meet Attamba – Attamba replaces Key-Value projections with SSMs, unlocking multi-token compression before attention, improving perplexity by 24% over transformers of similar memory footprint!
Paper: arxiv.org/abs/2411.17685
🧵


🚀 Introducing Hymba-1.5B: a new hybrid architecture for efficient small language models!
✅ Outperforms Llama, Qwen, and SmolLM2 with 6-12x less training
✅ Massive reductions in KV cache size & good throughput boost
✅ Combines Mamba & Attention in a Hybrid Parallel Architecture
✅ Base and Instruct with open license on HF
🤗 HF: tinyurl.com/hymba1-5b-hf
📚 Arxiv: arxiv.org/abs/2411.13676
🐙 GitHub: github.com/NVlabs/hymba
Long post with analysis and insights

Jordan Dotzel retweeted

Thanks Dr. Masahiro Tanaka from Microsoft Deepspeed for an impressive guest lecture in my Deep Learning Efficiency course.
youtube.com/watch?v=9FogHL6s…

Jordan Dotzel retweeted
Excited to see @jaseweston highlighting the importance of contextual behavior in transformers! In our #EMNLP2024 paper 'ShadowLLM', we show that a tiny neural network can contextually predict which heads and neurons to prune.
arxiv.org/abs/2406.16635
(1/4)


🚨 Contextual Position Encoding (CoPE) 🚨
Context matters! CoPE is a new positional encoding method for transformers that takes into account *context*.
- Can "count" distances per head dependent on need, e.g. i-th sentence or paragraph, words, verbs, etc. Not just tokens.
- CoPE solves counting & copy tasks that standard transformers cannot.
- Better PPL on language modeling + coding tasks.
arxiv.org/abs/2405.18719
🧵(1/5)

Jordan Dotzel retweeted
Find me or my students (@AmishAcorns and @akhauriyash123) at @icmlconf next week to discuss our work on LLM quantization and NAS. DM me to get coffee or to hang out and talk about ML efficiency.
Papers:
- arxiv.org/abs/2405.03103
- arxiv.org/abs/2403.02484
Cute little snipes video made from a friend and fellow snipper snapper, Feccez
youtu.be/d1g0yNsifmE
3
5


Jordan Dotzel retweeted

@AmishAcorns STILL GOT IT! – at Atlantic City, NJ

Oh BABY 🔥
Matters are getting personal on #HaloClassic main stage right now.
twitch.tv/ugc | mixer.com/ugcevents
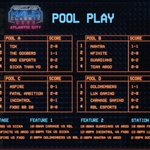
Great games today at @UGCevents and made it to the pool play tomorrow with @TeamArgo! No time for FFA though =(

3
4

Jordan Dotzel retweeted

Halo 2 Montage out now. Rts are appreciated ❤️ youtu.be/l__2ARoBjUo
