







While the Binance hack is pretty insane, $2.5 billion is not a small amount.
But this will be so blown out of proportion, $2.5 billion is nothing in Crypto world.
Just chill.
Wow they actually pulled back on their decision
That’s unexpected

Day 25/
We are doubling all usage limits for all Pro 100/200/500 tiers and Business Premium, effective today.
We heard your kind feedback and won’t be reducing usage limits for Pro 200, so your Work and Codex usage will stay the same. We’re also going to continue offering extended limits for dots for now, and usage of your dot will still continue to be separate from your default usage.
And we'll of course also keep shipping better models and other efficiency improvements that increase your effective usage over time.

If this is their “next” frontier boy oh boy are they in trouble.
Also, I don’t think anyone trusts Google’s benchmark scores anymore, unfortunately.


People are so funny, now that the OAI models are finally properly represented, Anthropic fanboys cry about how unfair this benchmark is
The cult of Anthropic is in full force
If you think that Sonnet is better than Astra or 6.1 Sol you should reconsider your relationship with AI.

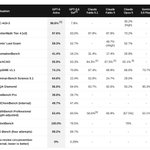
Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets
The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers.
Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale.
New to the Intelligence Index:
➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment
Upgraded:
➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions
➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised
➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool
Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0
Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1
Key results:
➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50
➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36)
➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04

Yeah but OpenAI are so behind 🤓
Yeah shut the fuck up

We are announcing three new discoveries in mathematics, computer science, and physics about harmonic analysis, complexity theory, and quantum field theory.
openai.com/index/building-sc…

What an embarrassment

Phantom Blade Zero achieves its goal of creating wonderfully fluid and cinematic kung fu-style combat - but balance and quality issues ultimately dim its shine.
Our review:
eurogamer.net/phantom-blade-…

ALT Phantom Blade Zero screenshot showing a character in a circular hat looking stern. Eurogamer 3/5
This is quite awesome

OpenAI models helped researchers—operating as part of our Patch the Planet initiative—discover critical security flaws in PHP, an open-source programming language used to run an estimated 70% of websites.
Over the past two months, we led a coalition of maintainers, researchers, and security providers to prepare fixes and protections ahead of disclosure. This duration was necessary because the fix was quite intricate and required a major change to the PHP engine. Every site using PHP can now safely upgrade their version to stay secure, in addition to applying mitigations from various security vendors.
Due to the severity of these flaws and PHP’s widespread use, we consider this bug to be one of the most impactful vulnerabilities in recent memory. It also marks a new phase, where AI can find security bugs with internet-scale impact.
This is an example of the Defender’s Window in action: to our knowledge, frontier AI was able to find this vulnerability ahead of attackers, giving defenders time to prepare.
openai.com/index/coordinated…

I'm trying to write an article and got downgraded to Opus 5 two times!
Here is me trying to tell others how great of a thing this is but a tiny mention of bio triggers Claude.
Are we deadass?

New on our Science Blog: designing protein binders against scorpion neurotoxins.
Scorpions sting about 1.2m people every year, and antivenoms are often costly or in short supply. Claude has made an early step toward finding new treatments.
anthropic.com/research/claud…

Over the years, Elon became a quite a controversial figure, mostly due to his association with DT.
Today’s Tesla Roadster again made me feel like it’s 2010-2015 all over again, back when Elon was called real life Tony Stark.
Feels nice
Bravo, Meta!
Not open-weight SOTA but certainly step in the right direction!
Will finally replace GPT OSS in many places

Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio


I love the updates but no Spanish seems really stupid dear OAI
Hahaha
Yap
Let’s see how generous those limits will be after the IPO
Anthropic is still Anthropic
Banning a whole company over a joke tweet is crazy work


Gemini 4 Argon is finally out of the oven!

Today we are rolling out Gemini 4 Argon globally in the Gemini API, to Pro + Ultra in Gemini App, and Ultra subs in Antigravity!
Argon is a huge step forward for Gemini, and a labor of love. This model has been battle tested by over 100,000 people at Google over the last month, with so much new innovation, ambition, and hard work baked into this release. The team has been heads down over the last 6 months working to make this possible across the stack (research, infra, safety, eng, etc).
We rolled the model out to cyber defenders as part of our fairwind program and early access customers over the last 2 weeks, it has been amazing to see and talk to folks who are now using this model daily. Seeing the models writing capability, raw knowledge and persistence for coding, paired with new features like 1M token output when the model needs to work more has gotten me even more excited about our path ahead.
This is just the start of the Gemini 4 era. As you saw with 3.5, 3.6, 3.7, and 3.8 Flash, our iteration speed with Gemini is fast : ) Now with Gemini 4 Argon to work from, I am cannot wait to see the progress continue, and most importantly see what this new model enables for the world.
This is such a special moment in the arc of technology, as millions of people everyday tackle problems they could never have thought possible before. Gemini 4 Argon was built to help you tackle the hardest problems. I have personally felt this spark with Argon and hope you do too. Onwards!!
Currently, Meta doesn’t give a shit about profit margins
But don’t be fooled
This model is much more expensive than it looks


Good change. I wonder if there is any way to speed up the compaction 🤔
Day 7/
We have increased default context length for GPT-6.1 Sol to 500k when used through Codex & Work, up from 272k or an ~ 80% increase.
We will go higher in the future, but it helps reduce occurrence of compactions and with tasks that require keeping a lot of context and nuance over periods of time. It was carefully tested and is the new sweet spot for most of our users. You can still override it if you want to be higher our lower, with maximum context length of GPT-6.1 Sol of 1M.