

Associate Prof #NLProc | Find me on the other platform
Groningen, The Netherlands
Joined July 2017
- Tweets390
- Following265
- Followers1.2K
- Likes799



Arianna Bisazza #EMNLP 🇨🇳 retweeted

[1/8] Thrilled to share that our paper “Optimizing Language Models for Crosslingual Knowledge Consistency” has been accepted to #ICML2026! 🎉
We ask a simple question: can we make multilingual LLMs more consistent across languages with #RL?
🔗Paper+Code: arxiv.org/abs/2603.04678

Arianna Bisazza #EMNLP 🇨🇳 retweeted
[1/2] Heading to #EMNLP2025 to present our work on multilingual reasoning. (Fri Nov 7, 12:30-13:30)
We analyze the trade-off between controlling reasoning languages and accuracy. We also explore mitigations like prompt hack, post-train (and GRPO🤩) for this issue.
Come say hi!

Arianna Bisazza #EMNLP 🇨🇳 retweeted
1/ Multilinguality & RL folks: Previously, we found LMs often fail to produce reasoning traces in the user's language; prompting/SFT helps, but hurts accuracy. (To be presented on Fri Nov 7, 12:30-13:30 #EMNLP2025 )
⚠️ More importantly, we already tested an RL fix! Thread below.


2/ many previous works, including ours, showed that prompting does not work...
We present some“budget alignment” recipes:
• SFT : 817 multilingual chains to teach in-language reasoning
• GRPO (math500-only RL): recover/boost accuracy while keeping the language policy learned in SFT
• And model merging!
Arianna Bisazza #EMNLP 🇨🇳 retweeted

Presenting today our work "Unsupervised Word-level Quality Estimation Through the Lens of Annotator (Dis)agreement" at the #EMNLP2025 Machine Translation morning session (Room A301, 11:45 China time). See you there! 🤗
Happy to introduce TurBLiMP, the 1st benchmark of minimal pairs for free-order, morphologically rich Turkish!
Pre-print: arxiv.org/abs/2506.13487
Fruit of an almost year-long project by amazing MS student Ezgi Basar, in collab w/ @FrancescaPado15
@JumeletJ

One step further in our quest to bring interpretability techniques to the service of MT end users: Are uncertainty & model-internals based metrics a viable alternative to supervised word-level quality estimation?
New paper w/ @gsarti_ @zouharvi @MalvinaNissim!


Large Reasoning Models are raising the bar for answer accuracy & transparency, but how does that work in multilingual settings? Can LRMs reason in your language, and what does that entail?
See new preprint led by @Jirui_Qi & @shan23chen!

[1/]💡New Paper
Large reasoning models (LRMs) are strong in English — but how well do they reason in your language?
Our latest work uncovers their limitation and a clear trade-off:
Controlling Thinking Trace Language Comes at the Cost of Accuracy
📄Link: arxiv.org/abs/2505.22888

Applying interpretability techniques to speech LMs is far from being a solved problem!
Read why in @linguisticshen’s paper, fruit of a nice collaboration w/ @hmohebbi75 @afraalishahi @gchrupala where I keep learning interesting stuff about speech and SLMs! :-)

I am excited to announce that my paper "On the reliability of feature attribution methods for speech classification" has been accepted to #Interspeech2025!
Co-authors: @hmohebbi75 @AriannaBisazza @afraalishahi @gchrupala
Find the preprint here: arxiv.org/abs/2505.16406

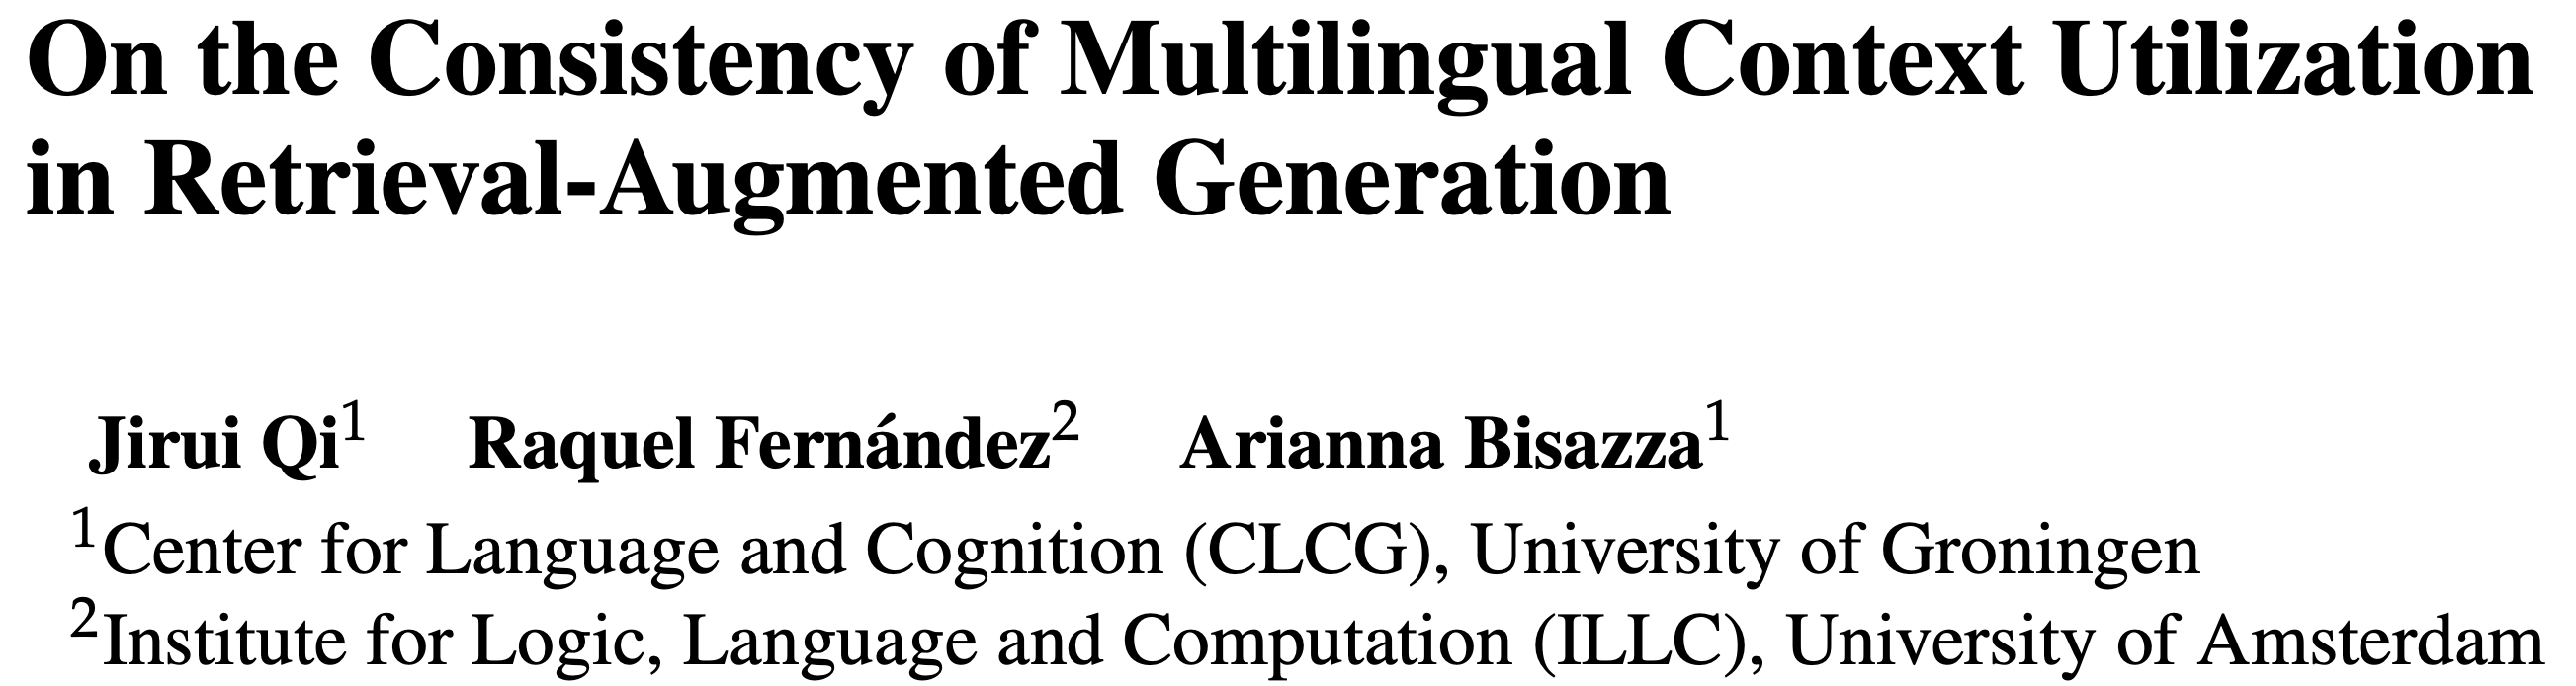
RAG is a powerful way to improve LLMs' answering abilities across many languages. But how do LLMs deal with multilingual contexts? Do they answer consistently when the retrieved info is provided to them in different languages?
Joint work w/ @Jirui_Qi & @raquel_dmg
See thread! ⤵️
✨ New Paper ✨
[1/] Retrieving passages from many languages can boost retrieval augmented generation (RAG) performance, but how good are LLMs at dealing with multilingual contexts in the prompt?
📄 Check it out: arxiv.org/abs/2504.00597
(w/ @AriannaBisazza @raquel_dmg)
#NLProc
Modern LLMs "speak" hundreds of languages... but do they really?
Multilinguality claims are often based on downstream tasks like QA & MT, while *formal* linguistic competence remains hard to gauge in lots of languages...
Meet MultiBLiMP!
(joint work w/@JumeletJ & @LAWeissweiler)


Importantly, MultiBLiMP is also a pipeline to construct minimal pairs automatically from Universal Dependencies treebanks, which we hope to extend to many more syntactic phenomena in future collaborative efforts (reach out if interested in this!)
We see our work as a (breadth-first) complement to the valuable development of language-specific BLiMPs which offer more depth but are hardly scalable to lots of languages.
For more details and interesting LLM results, see @JumeletJ's thread ⤴️ & paper arxiv.org/abs/2504.02768