

Guitarist(CINEOLA . Lucid And The Flowers . Sad Vacations . Sabachthani . mondfish ) / Composer / Improviser / Guitar Instructor / Cat Lover
Joined July 2015
- Tweets133K
- Following1.3K
- Followers1.7K
- Likes108K


Pinned Tweet
【 Live Schedule 】
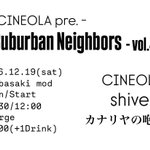
・CINEOLA
12.19(Sat) 柴崎mod
CINEOLA pre.
『Suburban Neighbors - vol.4』
2027.1.9(Sat) TBA
・LUCID AND THE FLOWERS
12.13(Sun) 柴崎mod
「Coffee and Cigarettes」


2026.09.20 (Sun)
三軒茶屋heaven's door
monochromed&heaven's door presents
『sounds from the cave vol.4』
CINEOLA / 灯りを
Shooting & Edit : VJ Bori (音景-Onkei-)@Bori_LMSD


kaetsu takahashi retweeted

这两天 AI 圈发生了一件特别打脸的事,但整个行业几乎都在装哑巴:一个只有 1.09 亿参数的小模型,在对真实世界的理解上,居然硬生生干翻了 720 亿参数的巨无霸。
对,你没看错,体型足足小了 660 倍。
这几年的大厂全都魔怔了一样,信奉“大力出奇迹”。大家从 2024 年起就默认了一套逻辑:只要往死里堆显卡、喂够海量的文字和图片,模型变大之后自然就懂世界了。
只有 Yann LeCun 一直梗着脖子唱反调,说光靠堆规模根本没戏。因为跟 Meta 赌的方向完全相反,他去年 11 月干脆拍拍屁股走人,跑去巴黎自己拉队伍单干。
结果就在上周四,他联手 Randall Balestriero 直接把实锤证据甩在了所有人脸上。
你说凭什么?硅谷烧了上千亿美金的算力信仰,怎么就被一个几百倍小的模型给掀了桌子?
给不太了解底层训练逻辑的朋友拆解一下这组数字有多吓人。
不是小一两倍,是整整小了 660 倍。而且为了达到同样的理解深度,新方法只喂了 2160 万个样本就通关了,而现在全世界所有聊天机器人都在用的“预测下一个词”,足足吞了 9 亿个样本才勉强追上。
这还没完。为什么算力堆成山,效率反而被按在地上摩擦?
你以为是之前喂的数据还不够多,其实从根子上就喂错了东西,这就是我常说的盲人摸象式暴力。
你可以这么理解,这就好比教一个小孩认识什么是“苹果”。LeCun 验证的法子,是一手拿张苹果的照片,一手拿着描述这张照片的句子,把“同一件事的两种视角”绑在一起给他看,小孩看几眼就彻底通透了。
而现在主流大模型干的事,是从同一篇长文章里随便抠出两段话,逼着它顺着上句猜下句。
那两段话根本不是同一件事的不同切面,硬凑在一起死记硬背,不仅学得极其缓慢,还贼烧钱。
不是模型的脑容量不够大,而是死记硬背的文字接龙永远拼不出真实的世界。
这种顶级科学家的路线之争,咱们看个热闹也就算了。
但有个事吧,我翻来覆去还是想多说两句。就是“方向比蛮力重要”这件事,到底给我们敲了什么警钟。
因为我自己每天都在高强度用各种大模型写代码、理逻辑,经常遇到那种参数量吓死人、但一碰到真实物理常识就胡说八道的时刻。
无论是巨头训模型还是我们自己折腾项目,绝不迷信盲目堆量的算力迷信。先把底层的配对逻辑跑通,用巧劲去破蛮力的局,至于巴黎那间新实验室接下来还会憋出什么大招,我们一起往下看。

Yann LeCun was right & nobody in this industry wants to say it out loud.
109 million parameters beat 72 billion.
He has spent years saying scale is not the thing that makes a model understand the world. Meta bet the other way. He left in November and started his own lab in Paris.
Last Thursday he published the proof.
The theory everyone has been running on since 2024 is that if you train models big enough, on text, on images, on sound, they all end up with the same picture of reality inside them. Size does it. Nobody ever proved that part.
Randall Balestriero and LeCun proved it. And the proof says size was never doing the work.
What does the work is which two things you show a model together.
A photo and the caption of that photo are two views of one thing. Models trained on pairs like that get there fast.
Two paragraphs pulled from the same document are not two views of one thing. Models trained on those get there slowly and expensively.
Next word prediction is the second kind. That is what every chatbot in the world runs on.
In their tests the first method reached the same understanding after 21.6 million examples. Next word prediction needed 900 million.
And a 109 million parameter text model ended up closer to an image model's view of the world than a 72 billion parameter language model was.
660 times smaller.

kaetsu takahashi retweeted

Yann LeCun was right & nobody in this industry wants to say it out loud.
109 million parameters beat 72 billion.
He has spent years saying scale is not the thing that makes a model understand the world. Meta bet the other way. He left in November and started his own lab in Paris.
Last Thursday he published the proof.
The theory everyone has been running on since 2024 is that if you train models big enough, on text, on images, on sound, they all end up with the same picture of reality inside them. Size does it. Nobody ever proved that part.
Randall Balestriero and LeCun proved it. And the proof says size was never doing the work.
What does the work is which two things you show a model together.
A photo and the caption of that photo are two views of one thing. Models trained on pairs like that get there fast.
Two paragraphs pulled from the same document are not two views of one thing. Models trained on those get there slowly and expensively.
Next word prediction is the second kind. That is what every chatbot in the world runs on.
In their tests the first method reached the same understanding after 21.6 million examples. Next word prediction needed 900 million.
And a 109 million parameter text model ended up closer to an image model's view of the world than a 72 billion parameter language model was.
660 times smaller.


kaetsu takahashi retweeted

ペットサウンズは世界に先駆けて日本で初CD化、ブライアン・ウィルソンがソロアルバム発表、ココモの全米1位と88年は節目の年
ビーチ・ボーイズ(The Beach Boys)『Pet Sounds』はいつ名盤となった? 山下達郎、村上春樹、大滝詠一らの言葉や証言などで評価の変遷を辿る mikiki.tokyo.jp/articles/-/4…

kaetsu takahashi retweeted

完全に壊れたMinimoogをエミュレートした、Full Bucket Music「Broken Mini」無償配布中です。
computermusic.jp/2024/11/bro…
@universe_ex より

kaetsu takahashi retweeted
【 Live Schedule 】
・CINEOLA
12.19(Sat) 柴崎mod
CINEOLA pre.
『Suburban Neighbors - vol.4』
2027.1.9(Sat) TBA
・LUCID AND THE FLOWERS
12.13(Sun) 柴崎mod
「Coffee and Cigarettes」
2026.09.20 (Sun)
三軒茶屋heaven's door
monochromed&heaven's door presents
『sounds from the cave vol.4』
CINEOLA / 灯りを
Shooting & Edit : VJ Bori (音景-Onkei-)@Bori_LMSD


