

Senior AI Engineer @google • Kauffman Fellow • ☸ • 🇵🇷 • ⛷ • 🏊🏾 • 🧘🏿♂️ • implacable • L∃∀N
San Francisco Bay Area
Joined May 2009
- Tweets12.6K
- Following1.2K
- Followers2.3K
- Likes12.8K




Marcos Polanco retweeted

Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index
Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas.
As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon.
Key results for Gemini 4 Carbon with high reasoning:
➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work
➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude Opus 5.5 (max, 62) on the Artificial Analysis Coding Agent Index. Carbon ranks second on both Terminal-Bench 4.0 (64%) and FrontierCode v1.1 (51%), behind Claude Opus 5.5 (max) at 56%. Google has historically underperformed in this area and so this improvement stands out
➤ Improved agentic knowledge work, but not yet leading: On AA-Briefcase, Gemini 4 Carbon (high) scores 1609 Elo, a 126-point improvement over Gemini 4 Argon (high, 1483), but still behind models including Grok 4.7 (xhigh, 1638), Muse Wonder (max, 1659) and Kimi K3.1 Pro (1678). The largest gain comes from Presentation, up 293 Elo to 1598, alongside a 120-point improvement in Analytical Quality to 1671
➤ Lower Cost per Task than Claude Opus 5.5 for comparable overall intelligence: Gemini 4 Carbon costs $7.76 per Intelligence Index task, ~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Claude Opus 5.5 (max, 173k). At the same $4/$20 standard pricing, its Cost per Task is in line with Gemini 4 Argon ($7.68), while scoring 9 points higher on the Intelligence Index
➤ Leading AA-Omniscience v1.1 score, with low hallucination: Gemini 4 Carbon scores 54 on our recently updated AA-Omniscience v1.1, 6 points ahead of Claude Opus 5.5 (max, 48) and 8 points ahead of Gemini 4 Argon (46). Accuracy (% correct) rises 10 points over Argon to 58%, while its hallucination rate rises from 4% to 11%. This is still the second lowest of any model, behind only Argon, compared with 50% for both Claude Opus 5.5 (max) and GPT-6 Astra (max)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens, the same as Gemini 4 Argon’s standard pricing, with a 50% discount. Cached input tokens receive a 95% discount ($0.20 per 1M)
Congratulations to the @GoogleDeepMind team!

Marcos Polanco retweeted

Gemini 4 Carbon is our next frontier model.
It’s state-of-the-art across cybersecurity and long-horizon capabilities.

Marcos Polanco retweeted

Meet Nex-N2.5 family, our latest open source agentic models.
Mini (35B) and Pro (397B) bring multimodal understanding and computer use. Max (1.6T) is a text-only MoE model built for complex reasoning, coding, and agent workflows.
Strong benchmark results in workflow automation and computer use:
⚡ Max scores 50.2 on AutomationBench v1.0.6—just 0.1 points behind Claude Opus 5
⚡ Pro scores 56.4 on OSWorld-2, ahead of Qwen3.8-Max at 46.7
With continuous action, visual feedback, and self-correction, NEX-N2.5 can work across Blender and CAD tools, handle expense reimbursements, and even play PC games—turning visual understanding into sustained, real-world execution.
🔗@huggingface
huggingface.co/nex-agi/Nex-N… huggingface.co/nex-agi/Nex-N… huggingface.co/nex-agi/Nex-N…
🔗@modelscope
modelscope.cn/models/nex-agi… modelscope.cn/models/nex-agi… modelscope.cn/models/nex-agi…
🔗 Github github.com/nex-agi/Nex-N2.5
🔗Website nex-agi.com/
Marcos Polanco retweeted

I'm happy to share that Mojo and MAX are now fully open - for development, extension, and commercial use! This includes the full Mojo programming language, but also the MAX graph compiler, MLRT runtime internals, and hardware abstraction logic.
Get your agents going!👇
Marcos Polanco retweeted
We added Gemini 4 Argon to our AutoResearchExam Pareto curve. It is 2-3 times cheaper compared to the other frontier models for almost the same ML engineering performance. Congratulations to the GDM team.

Marcos Polanco retweeted

ALERT🚨: NVIDIA has been working overtime, nights, and weekends after being shocked 🤯 by last week’s TPUv7 FP8 submission showing better performance per dollar.
Unfortunately for NVIDIA, its first GB300 FP4 counter-submission is still 1.64x worse in performance per dollar than TPUv7 for external customers across most of the end-to-end performance curve.
The x-axis of the graph below uses end-to-end latency, so a higher curve is better. The TPUv7 curve has higher perf per $ across most of the E2EL Pareto frontier.
This initial submission looks like NVIDIA’s first attempt to close the gap, but the gap is still massive. We expect more counter-submissions from NVIDIA as they continue trying to narrow the difference.

Marcos Polanco retweeted

We’ve teamed up with Google DeepMind and Zapier to host the inaugural Bench Summit by Kaggle.
Gain hands-on insights from the AI startups and researchers defining today’s evaluation standards, and get closer to the frontier.
Secure your spot or apply to speak:
rsvp.withgoogle.com/events/b…

ALT Announcement graphic from Kaggle for the Bench Summit. The image has a light cream background with a stylized, artistic illustration of a mountain peak overlaid with yellow contour lines and subtle geometric wire frame arrows pointing upward. Logo at the top reads "kaggle." Text at the bottom includes a red pin icon for the location "San Francisco", a calendar icon for "October 28, 2026", and the main heading: "Shape the next generation of evaluation @ Bench Summit".
Marcos Polanco retweeted

Come and work with me and my team @GoogleDeepMind!
We're looking for people with a background in philosophy, politics, computer science etc. who want to work on the biggest challenges in AI ethics and alignment:
google.com/about/careers/app…
Marcos Polanco retweeted
BREAKING NEWS🚨: Google has submitted its FIRST TPUv7 FP8 vLLM results to our Agentic Inference Benchmark and has demonstrated 1.67x better perf per dollar than even GB300 NVL72 FP4. 🚀
It is amazing to see Google go full steam ahead with externalizing the power of TPUs outside of Google.👇️ (1/4)🧵

Marcos Polanco retweeted

My take after testing Argon 4 over the past week, is that Google is back in the running. It feels like the org was already AGI pilled but agent usage wasn't high, which is why Claude pulled ahead. This is the first frontier agent model that seems to actually seems to be getting usage internally at Google. Extremely bullish sign and great for consumer who can pick from 3 (maybe 4 with Meta?) frontier labs again.

BREAKING: Gemini 4 is OUT and it's SURPRISINGLY GOOD??
I admit I was ready to trash this model qhen I saw the benchmarks but six of us at @every spent the past week testing it across coding, writing, design, and knowledge work, and were pleasantly surprsied.
It’s a breakthrough if your company lives in Google’s ecosystem, and a strong option for frontier hoppers as a secondary model for certain tasks. I
Here’s our vibe check:
My new favorite writing partner. DeepMind hired professional writers with red pens to stamp out AI slop, and it worked. I use it to untangle structure and sharpen metaphors; it also taught me something new tracing in a few of my favorite books. It's got a natural feel for structure and detailed explanations that Astra and Opus lack.
Shaky at refactors, fast on greenfield apps. At low effort on a from-scratch build, Gemini 4 built @kieranklaassen a working webcam heart-rate monitor in 35 minutes—matching Claude Opus 5.5’s quality and beating OpenAI’s models on that test. Where it cuts corners is self-verification and existing codebases. In 17 of Kieran’s 38 benchmark runs, it opened and closed its code-review step just 30 milliseconds apart instead of inspecting its changes. And on my Senior Engineer benchmark—refactoring a vibe coded slop codebase—it worked for four hours and 47 minutes and scored just 21% (versus 81% to 85% for GPT-6 Astra, Fable 5.1, Sonnet 5.5, and Opus 5.5). Not great.
A 2026 model trapped in a 2025 harness. Antigravity, Google’s desktop agent app, feels six months to a year behind Claude Code and Codex—lacking cloud environments, SSH, a built-in browser, and smart permission checks (leaving you clicking constant pop-ups or using unrestricted "Turbo" mode).
Net Result: I keep ChatGPT and Claude open day to day, and switch to Gemini 4 when I need an editorial partner to structure a tough essay, sharpen a metaphor, or close-read a book. Reach for it for live writing collaboration, fast low-effort prototypes, or steerable UI and dashboard design—ideally via Cursor or the API to skip Antigravity.
When a model is good enough to force you to use a bad harness, it tells you something.
State of Play: Google hadn’t shipped a major flagship upgrade since Gemini 3 Pro last November. For teams whose companies live in Google’s ecosystem, the model you can use inside your approved work tools finally belongs with the frontier pack. DeepMind closed the model gap; now Google needs to bring the app around it into 2026.
Read our full vibe check: every.to/p/vc-gemini-4-argon…

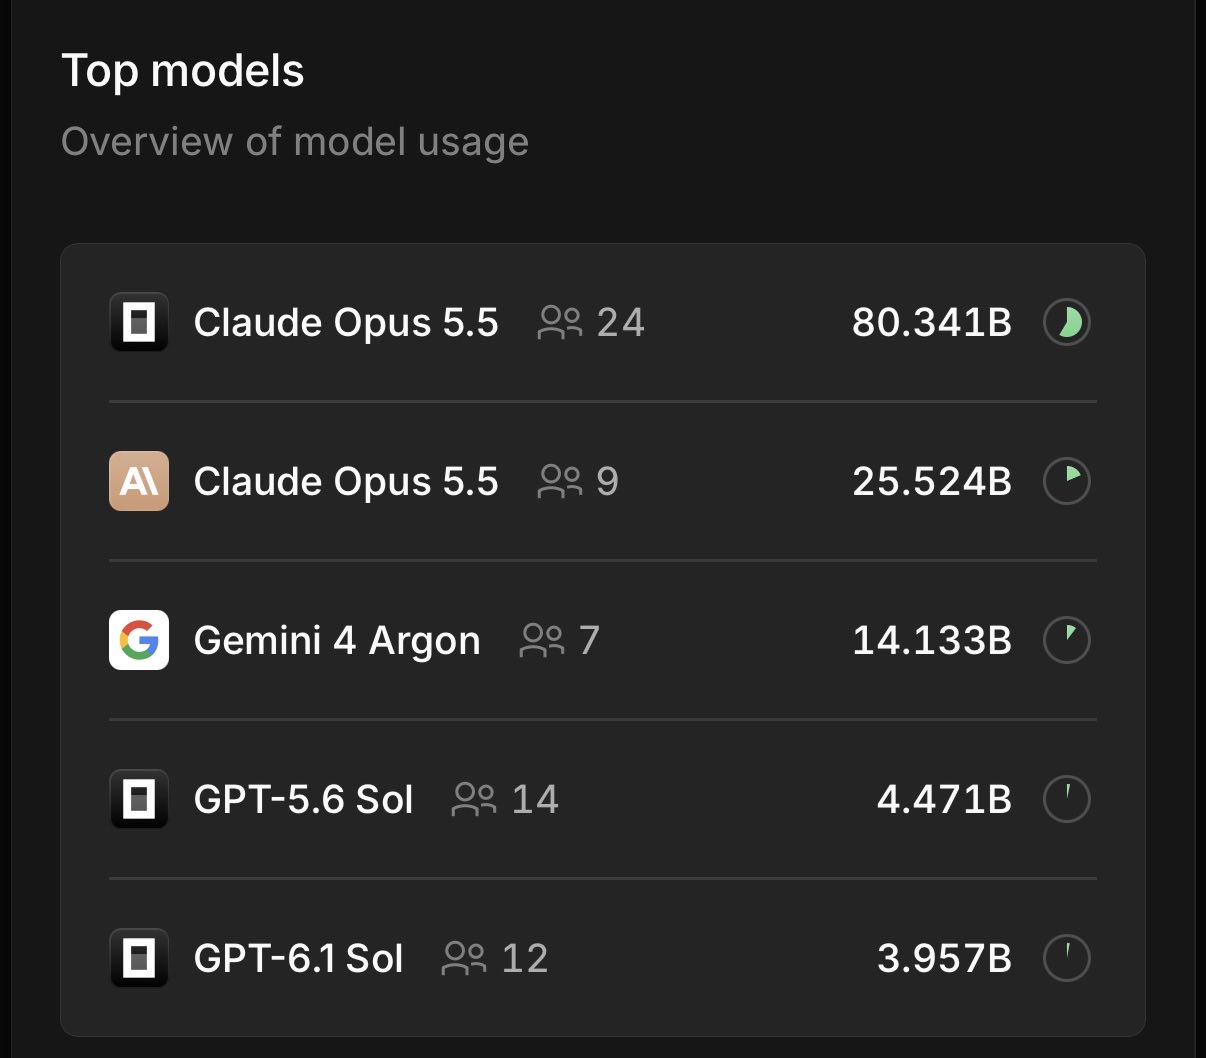

Marcos Polanco retweeted
BREAKING: Gemini 4 is OUT and it's SURPRISINGLY GOOD??
I admit I was ready to trash this model qhen I saw the benchmarks but six of us at @every spent the past week testing it across coding, writing, design, and knowledge work, and were pleasantly surprsied.
It’s a breakthrough if your company lives in Google’s ecosystem, and a strong option for frontier hoppers as a secondary model for certain tasks. I
Here’s our vibe check:
My new favorite writing partner. DeepMind hired professional writers with red pens to stamp out AI slop, and it worked. I use it to untangle structure and sharpen metaphors; it also taught me something new tracing in a few of my favorite books. It's got a natural feel for structure and detailed explanations that Astra and Opus lack.
Shaky at refactors, fast on greenfield apps. At low effort on a from-scratch build, Gemini 4 built @kieranklaassen a working webcam heart-rate monitor in 35 minutes—matching Claude Opus 5.5’s quality and beating OpenAI’s models on that test. Where it cuts corners is self-verification and existing codebases. In 17 of Kieran’s 38 benchmark runs, it opened and closed its code-review step just 30 milliseconds apart instead of inspecting its changes. And on my Senior Engineer benchmark—refactoring a vibe coded slop codebase—it worked for four hours and 47 minutes and scored just 21% (versus 81% to 85% for GPT-6 Astra, Fable 5.1, Sonnet 5.5, and Opus 5.5). Not great.
A 2026 model trapped in a 2025 harness. Antigravity, Google’s desktop agent app, feels six months to a year behind Claude Code and Codex—lacking cloud environments, SSH, a built-in browser, and smart permission checks (leaving you clicking constant pop-ups or using unrestricted "Turbo" mode).
Net Result: I keep ChatGPT and Claude open day to day, and switch to Gemini 4 when I need an editorial partner to structure a tough essay, sharpen a metaphor, or close-read a book. Reach for it for live writing collaboration, fast low-effort prototypes, or steerable UI and dashboard design—ideally via Cursor or the API to skip Antigravity.
When a model is good enough to force you to use a bad harness, it tells you something.
State of Play: Google hadn’t shipped a major flagship upgrade since Gemini 3 Pro last November. For teams whose companies live in Google’s ecosystem, the model you can use inside your approved work tools finally belongs with the frontier pack. DeepMind closed the model gap; now Google needs to bring the app around it into 2026.
Read our full vibe check: every.to/p/vc-gemini-4-argon…
Marcos Polanco retweeted

Over the last 5 years, Google teams have published 90 peer-reviewed papers (90k+ citations) on disease understanding.
Today, @pushmeet and I shared how Google is helping researchers accelerate discoveries across the continuum—from foundational biology to the bedside: blog.google/innovation-and-a…

Marcos Polanco retweeted

The people wanted it, here it is.
Full disk search, in milliseconds. 17,000x faster than Finder.
github.com/noahdunnagan/fsea…

Marcos Polanco retweeted

Every fundamental law of physics - Newton, Einstein, Quantum Field Theory - is derived from a single equation. Physicists don't propose new laws by writing forces anymore. They write a new Lagrangian and the math produces the physics automatically. The same principle that governs a swinging pendulum governs every quantum field in the universe - and the optimizer inside every LLM training run is solving the same underlying problem.
The mechanism is stationary action. A system takes the path where the total action stops changing for any small variation. That condition produces the Euler-Lagrange equation. One equation, any number of variables, any theory of physics. In Quantum Field Theory the variables are fields across all of space and the gradient must vanish at every point simultaneously - exactly the convergence condition gradient descent hunts for across billions of LLM parameters during backpropagation.
20 minutes. Bookmark & watch today. The single equation that every law of physics is secretly a special case of.


Marcos Polanco retweeted

These days, you can pretty much solve any task by defining an eval and hillclimbing over it, instead of directly defining the deterministic/agentic workflow to solve it.
The data provider companies' entire job is to define evals for all economic activity to make the frontier models capable of doing anything.
Your job then becomes pointing frontier intelligence in the right direction - defining what to solve, and how to measure what good looks like.
Agent application interfaces will evolve to capture this. The most complex processes will still need some sort of explicit workflow builder interface, but most tasks can be compressed into goals and eval instructions.
Marcos Polanco retweeted

The future of intelligence isn’t just about larger scale, it’s about elegant, efficient representations. Very excited to launch EmbeddingGemma 2, our new open model bringing natively multimodal embeddings directly to on-device applications.
Download the model weights on @huggingface huggingface.co/google/embedd… and @kaggle kaggle.com/models/google/emb…


Marcos Polanco retweeted

We are making Markdown files work natively across Google Drive and Docs.
You can now preview .md files in Drive, open them in Docs, edit them, comment on them, and collaborate without converting the file into a Google Doc!

Mathematics is about to graduate. It will grow into a full-scale industry and become the true infrastructure of all scientific and technological progress, a foundation that every other field stands on rather than a quiet corner of academia.

Reading all those recent beautiful essays by Terry Tao, Kevin Buzzard and @wtgowers, I could not resist, but write up my deeply personal perspective on how I perceive and see things:
docs.google.com/document/d/e…
Marcos Polanco retweeted
Google’s new Gemini 4 Argon equals GPT-6 Astra on the Artificial Analysis Intelligence Index at 60% of the Cost per Task with discounted prices. Google is now back to being one of the top three labs in intelligence achieved
Gemini 4 Argon is @GoogleDeepMind’s first proprietary model above the Flash class in over 7 months. With high reasoning (the highest available), it scores 53 on the Artificial Analysis Intelligence Index, matching GPT-6 Astra (max, 53) and 1 point ahead of GPT-6.1 Sol (max, 52), with gains driven by lower hallucinations and stronger agentic capabilities.
At its current 50% pricing discount and with cache discounts increased to 95%, Gemini 4 Argon costs $1.99 per Intelligence Index task, 60% of GPT-6 Astra (max), but 2.7x GPT-6.1 Sol (max). After the discount ends, this will rise to $3.98 (~1.2x GPT-6 Astra (max)).
Gemini 4 Argon is currently being rolled out to selected users and is not publicly available. The 50% discount is an initial promotion. Google has not yet confirmed the promotion end date
Key benchmarking results for Gemini 4 Argon with high reasoning:
➤ Google returns as one of the top three labs on intelligence: Gemini 4 Argon (high) scores 53 on the Artificial Analysis Intelligence Index, matching GPT-6 Astra (max, 53) and 1 point ahead of GPT-6.1 Sol (max, 52). This is 23 points above Google’s previous non-Flash model, Gemini 3.1 Pro Preview (30) and 12 points ahead of Gemini 3.8 Flash (high)
➤ Launch discounts of 50% make Gemini 4 Argon competitive on Cost per Task: At current discounted pricing, Gemini 4 Argon (high) costs $1.99 per Intelligence Index task, 60% of GPT-6 Astra (max, $3.26) for a comparable level of intelligence. This cost efficiency is driven by lower token prices, rather than reduced token use, with Gemini 4 Argon averaging 62k output tokens per task, compared with 27k for GPT-6 Astra (max). Google has not yet confirmed the promotion end date, but on standard pricing, Cost per Task will increase to $3.98
➤ Stronger agentic performance: Historically a weaker area for Gemini models, Gemini 4 Argon shows improvements across agentic evaluations. It ranks #1 on AutomationBench-AA at 77.5%, 6 points ahead of Claude Sonnet 5.5 (max, 71.3%). On Terminal Bench 4, Gemini 4 Argon achieves 57%, a +53 point improvement from Gemini 3.1 Pro Preview, only behind Claude Sonnet 5.5 (max, 64%), Claude Opus 5.5 (max, 60%) and GPT-6 Astra (59%). On AA-Briefcase, it reaches 1494 Elo. This is driven by a 65% rubric pass rate, the highest we have recorded, but lower Analytical Quality (1576 Elo) and Presentation Quality (1308 Elo)
➤ Lowest hallucination rate among leading models: On AA-Omniscience, Gemini 4 Argon has a 15% hallucination rate, the lowest of any model scoring 45+ on the Intelligence Index, compared with 51% for GPT-6 Astra (max) and 54% for GPT-6.1 Sol (max). This means Argon is much more likely to acknowledge when it does not know an answer rather than guess incorrectly. On accuracy, Gemini 4 Argon scores 50%, a 5 point decrease from Gemini 3.1 Pro Preview, and 13 points below GPT-6 Astra (max, 63%). With this slightly lower accuracy, its overall AA-Omniscience score of 42 remains in line with GPT-6 Astra (43) and GPT-6.1 Sol (42)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens at standard pricing, currently discounted 50% to $2/$10. Cached input tokens receive a 95% discount ($0.10 per 1M at discounted pricing), up from 90% on Gemini 3.8 Flash
➤ Long Decode Continuation: We tested Gemini 4 Argon with Long Decode Continuation, a new Gemini API feature that pauses long responses and resumes them across follow-up calls. This lets reasoning run up to 1M output tokens without request timeouts
